Si deseas distinguir tus productos, servicios o ambos de los de otra empresa, es posible que necesites una marca o nombre comercial. Descubre qué son, en qué consiste su procedimiento de registro y qué implica.

Información sobre los plazos de presentación de solicitudes de transformación de marcas de la Unión Europea en marca nacional española. Más información


Si tienes un nuevo dispositivo, producto o procedimiento que resuelva un problema técnico o tenga una ventaja práctica, existen distintas formas de protegerlo en España y en otros países. Descubre cómo hacerlo.

¿Tu innovación reside en la estética, la ornamentación o la apariencia de tu producto? Protégela mediante un diseño industrial. Descubre qué derechos confiere el registro y cómo realizar la tramitación.

Las indicaciones geográficas protegen el nombre de un producto originario de una zona geográfica, a la cual le debe una determinada calidad, reputación u otra característica. Descubre qué son, en qué consiste su procedimiento de registro y qué beneficios conceden.

Las patentes publicadas en todo el mundo son una valiosa fuente de información científica, técnica y comercial.

Si eres emprendedor/a o una empresa y quieres potenciar y mejorar la rentabilidad de tu negocio protegiendo de forma adecuada los activos intangibles de tu organización, en este espacio encontrarás lo necesario.


 98
resultados
 Última actualización
16/11/2026 [21:03:00]


 Resultados 25 a 50 de 98

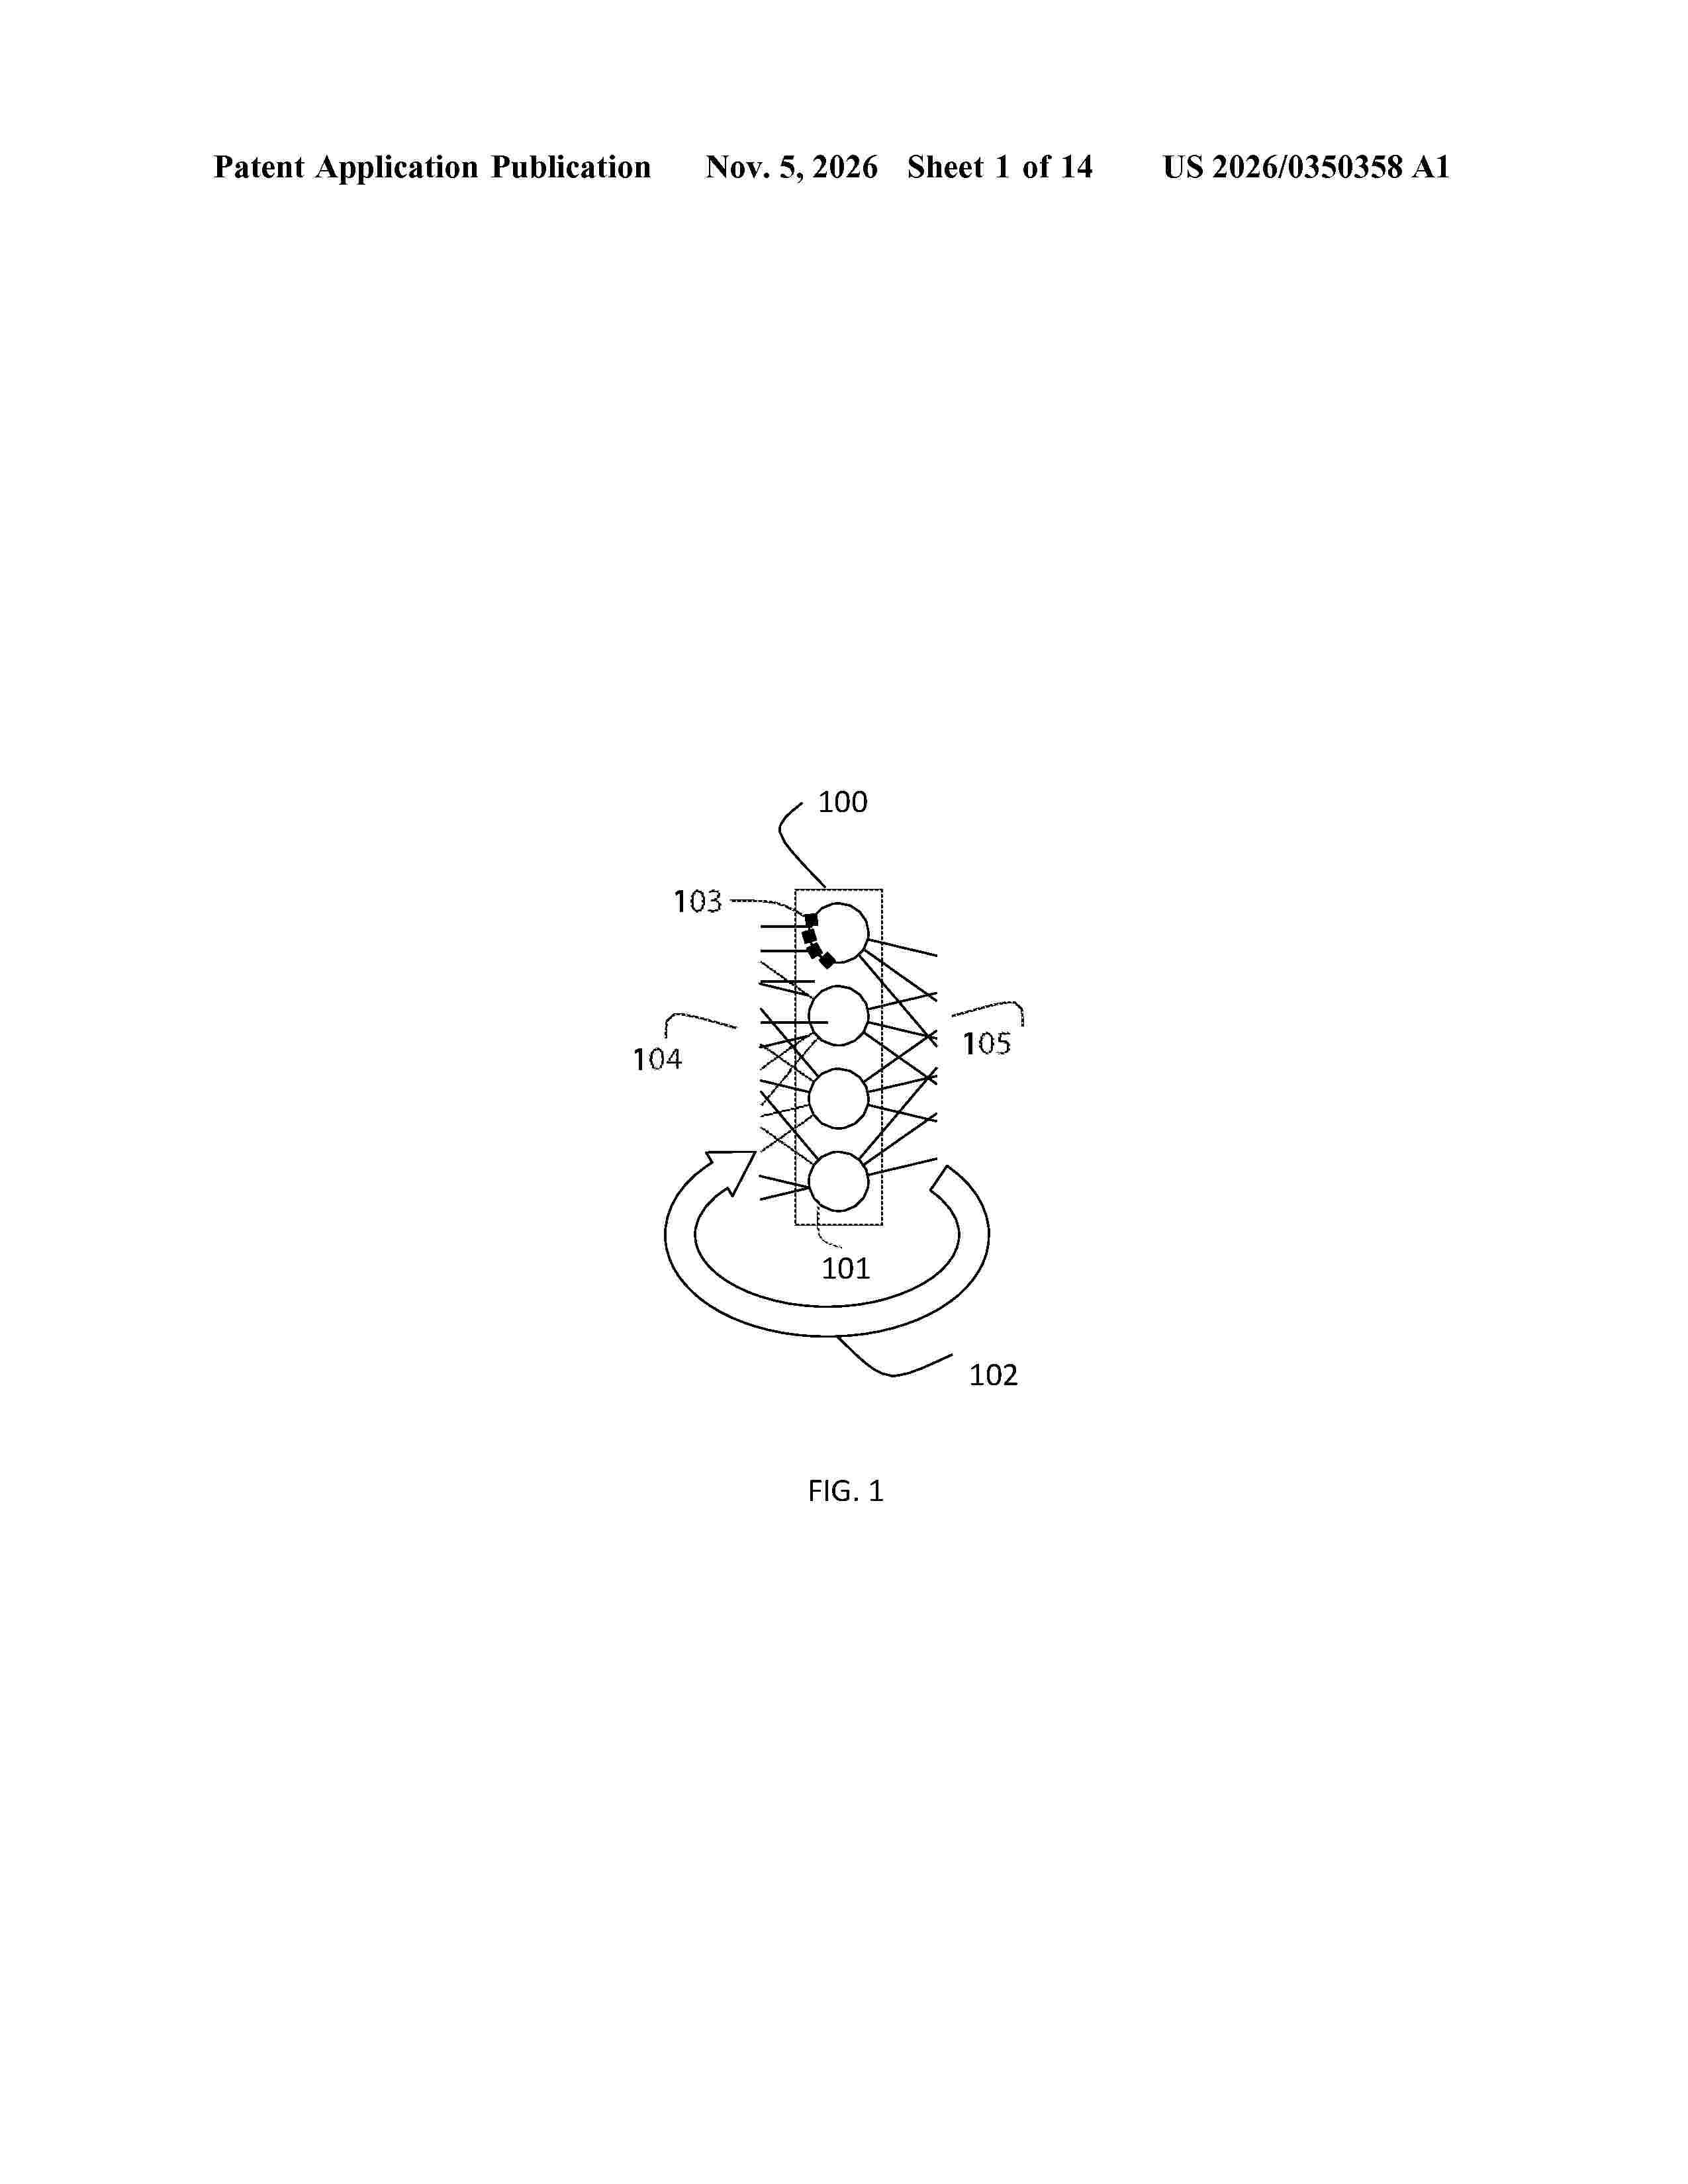
Resumen de: US20260350358A1
0000 A method is described for designing systems that provide efficient implementations of feedforward, recurrent, and deep networks that process dynamic signals using temporal filters and static or time-varying nonlinearities. A system design methodology is described that provides an engineered architecture. This architecture defines a core set of network components and operations for efficient computation of dynamic signals using temporal filters and static or time-varying nonlinearities. These methods apply to wide variety of connected nonlinearities that include temporal filters in the connections. Here we apply the methods to synaptic models coupled with spiking and/or non-spiking neurons whose connection parameters are determined using a variety of methods of optimization.

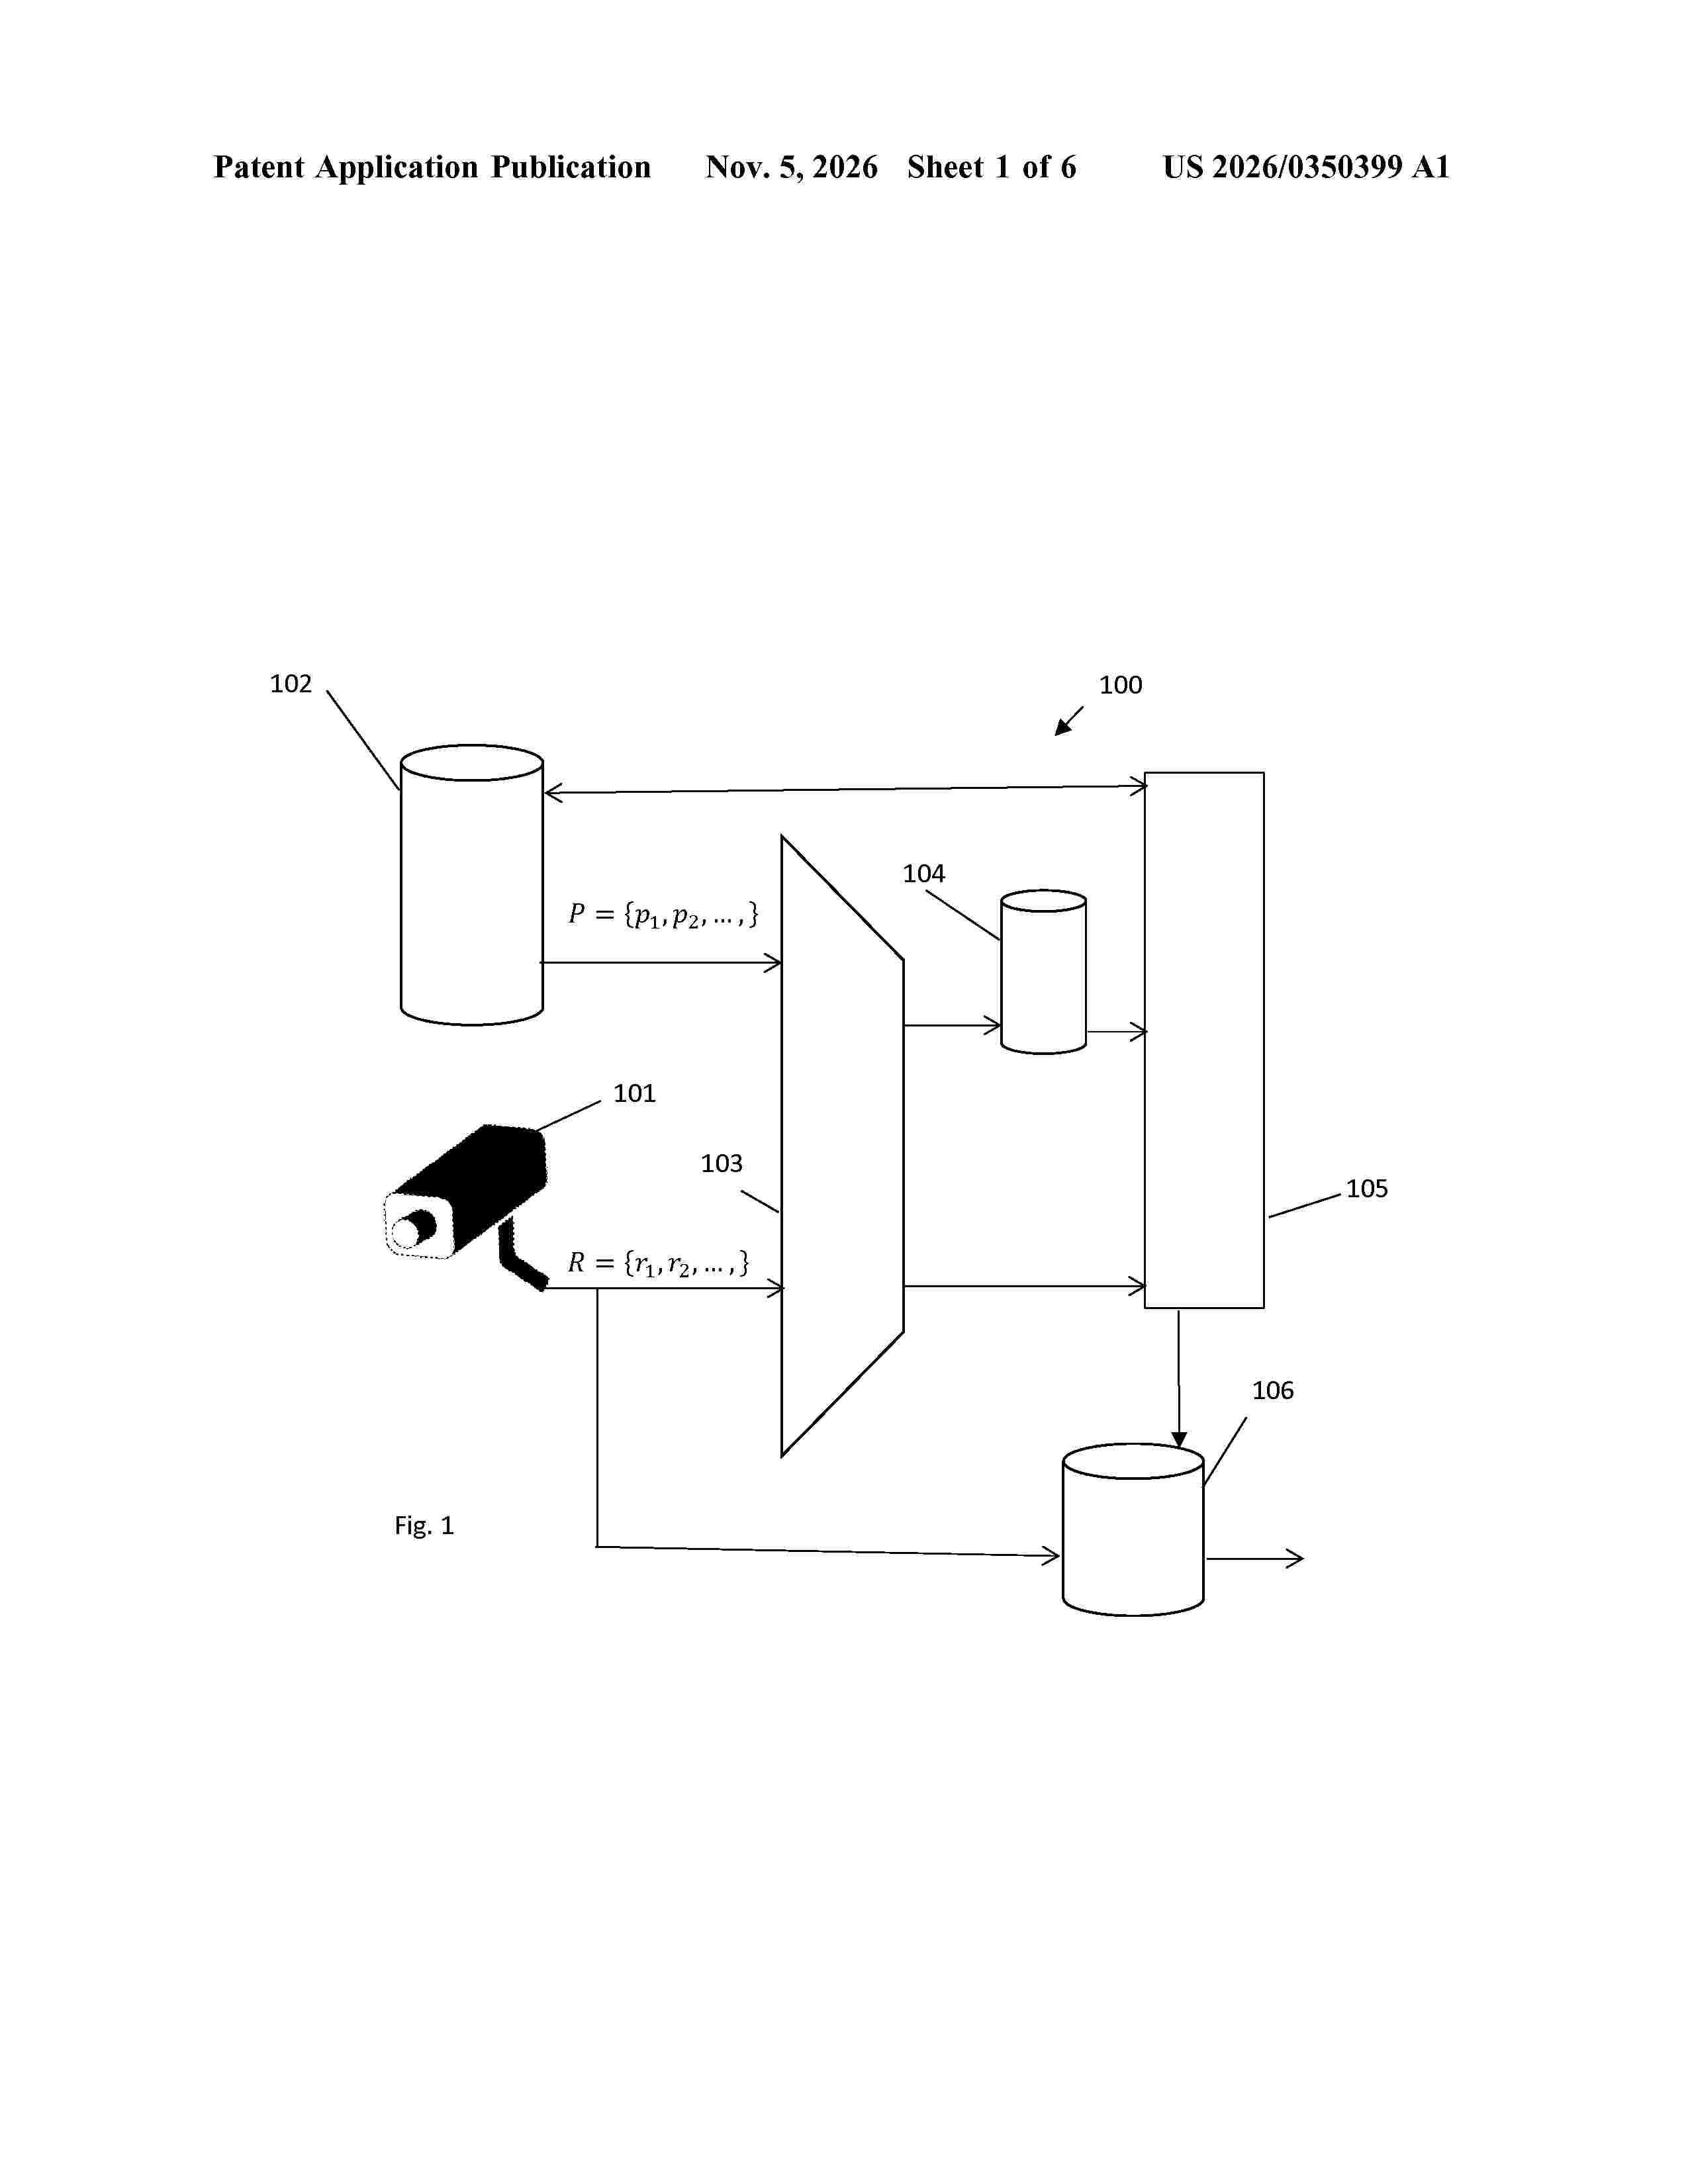
Resumen de: US20260350399A1
0000 An encoder neural network is described which can encode a data item, such as a frame of a video, to form a respective encoded data item. Data items of a first data sequence are associated with respective data items of a second sequence, by determining which of the encoded data items of the second sequence is closest to the encoded data item produced from each data item of the first sequence. Thus, the two data sequences are aligned. The encoder neural network is trained automatically using a training set of data sequences, by an iterative process of successively increasing cycle consistency between pairs of the data sequences.
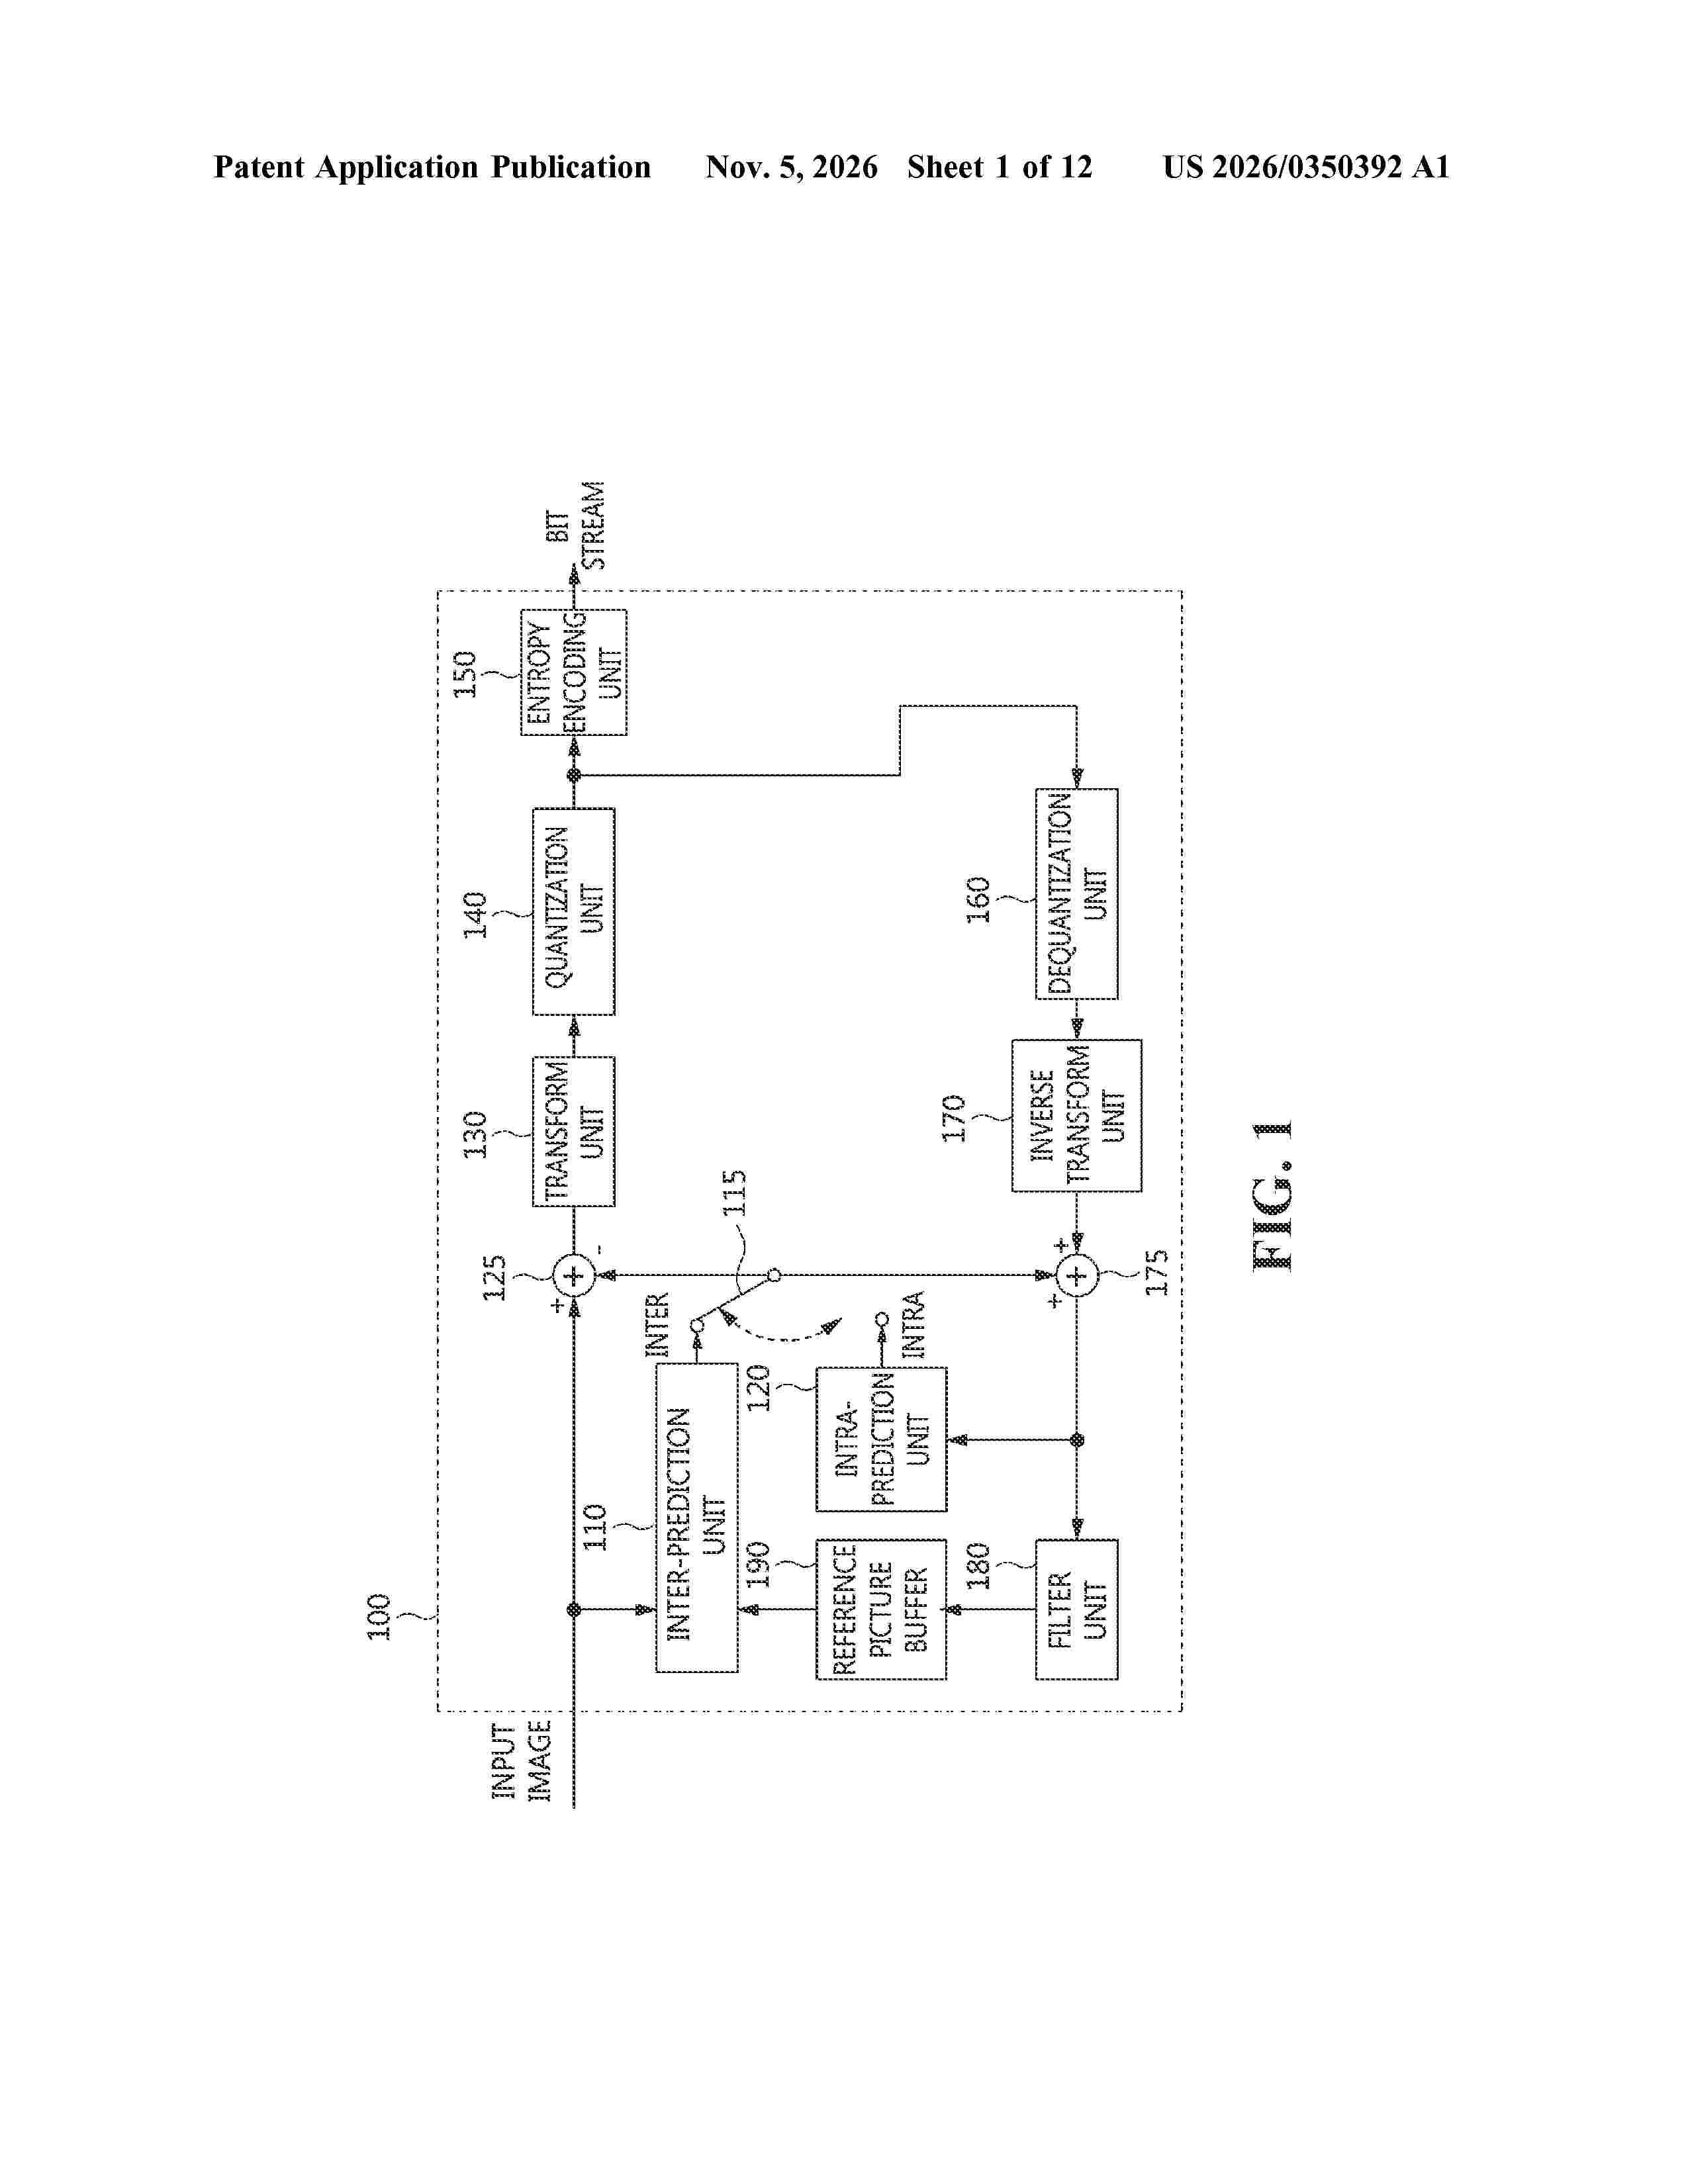
Resumen de: US20260350392A1
Disclosed herein are a method and apparatus for compressing learning parameters for training of a deep-learning model and transmitting the compressed parameters in a distributed processing environment. Multiple electronic devices in the distributed processing system perform training of a neural network. By performing training, parameters are updated. The electronic device may share the updated parameter thereof with additional electronic devices. In order to efficiently share the parameter, the residual of the parameter is provided to the additional electronic devices. When the residual of the parameter is provided, the additional electronic devices update the parameter using the residual of the parameter.
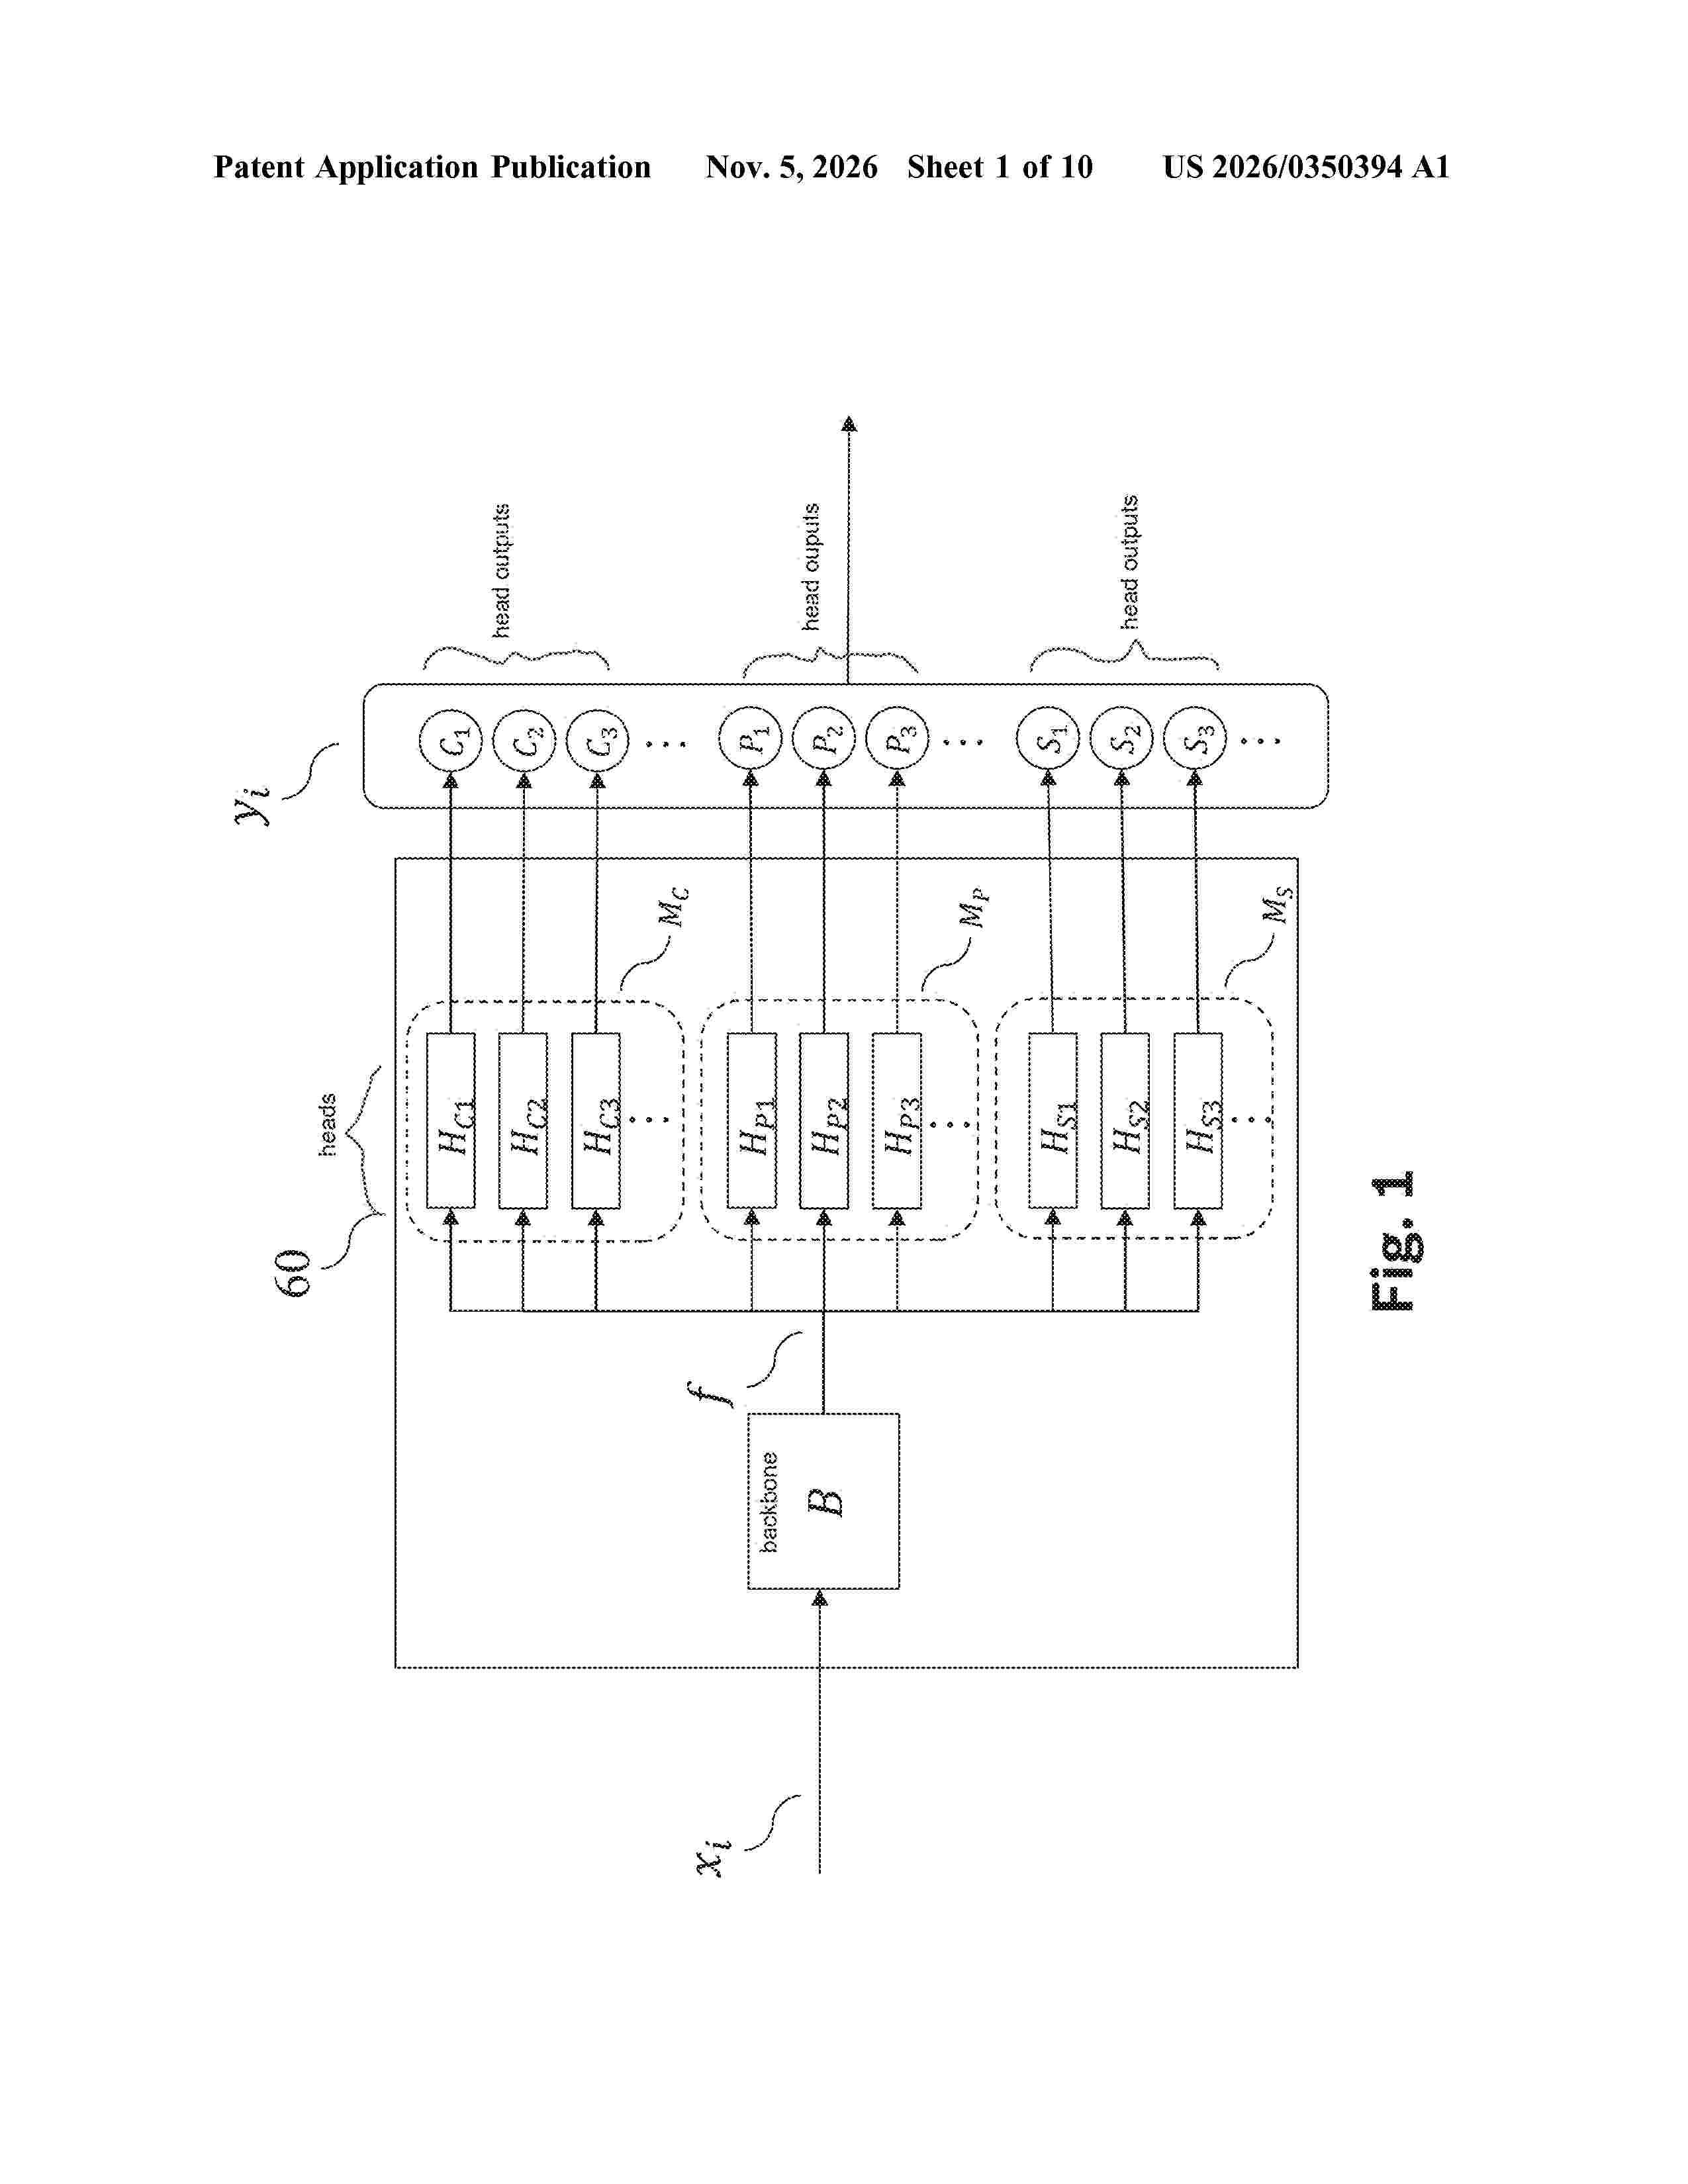
Resumen de: US20260350394A1
0000 A computer-implemented method for training a neural network. The neural network detects objects in images. The training includes: ascertaining a feature representation of a training image using a backbone of the neural network; ascertaining head outputs based on the feature representation and using heads of the neural network, wherein the head outputs, for regions of the training image, each characterize a presence or absence of an object or characterize an extension of the object or characterize a position of the object or characterize the extension and the position; ascertaining first loss values, wherein each first loss value corresponds to a head output and characterizes a deviation of the head output from a desired head output; adjusting a parameter(s) of the backbone and/or at least one parameter of a head based on a second loss value, wherein the second loss value characterizes a sum of the first loss values.
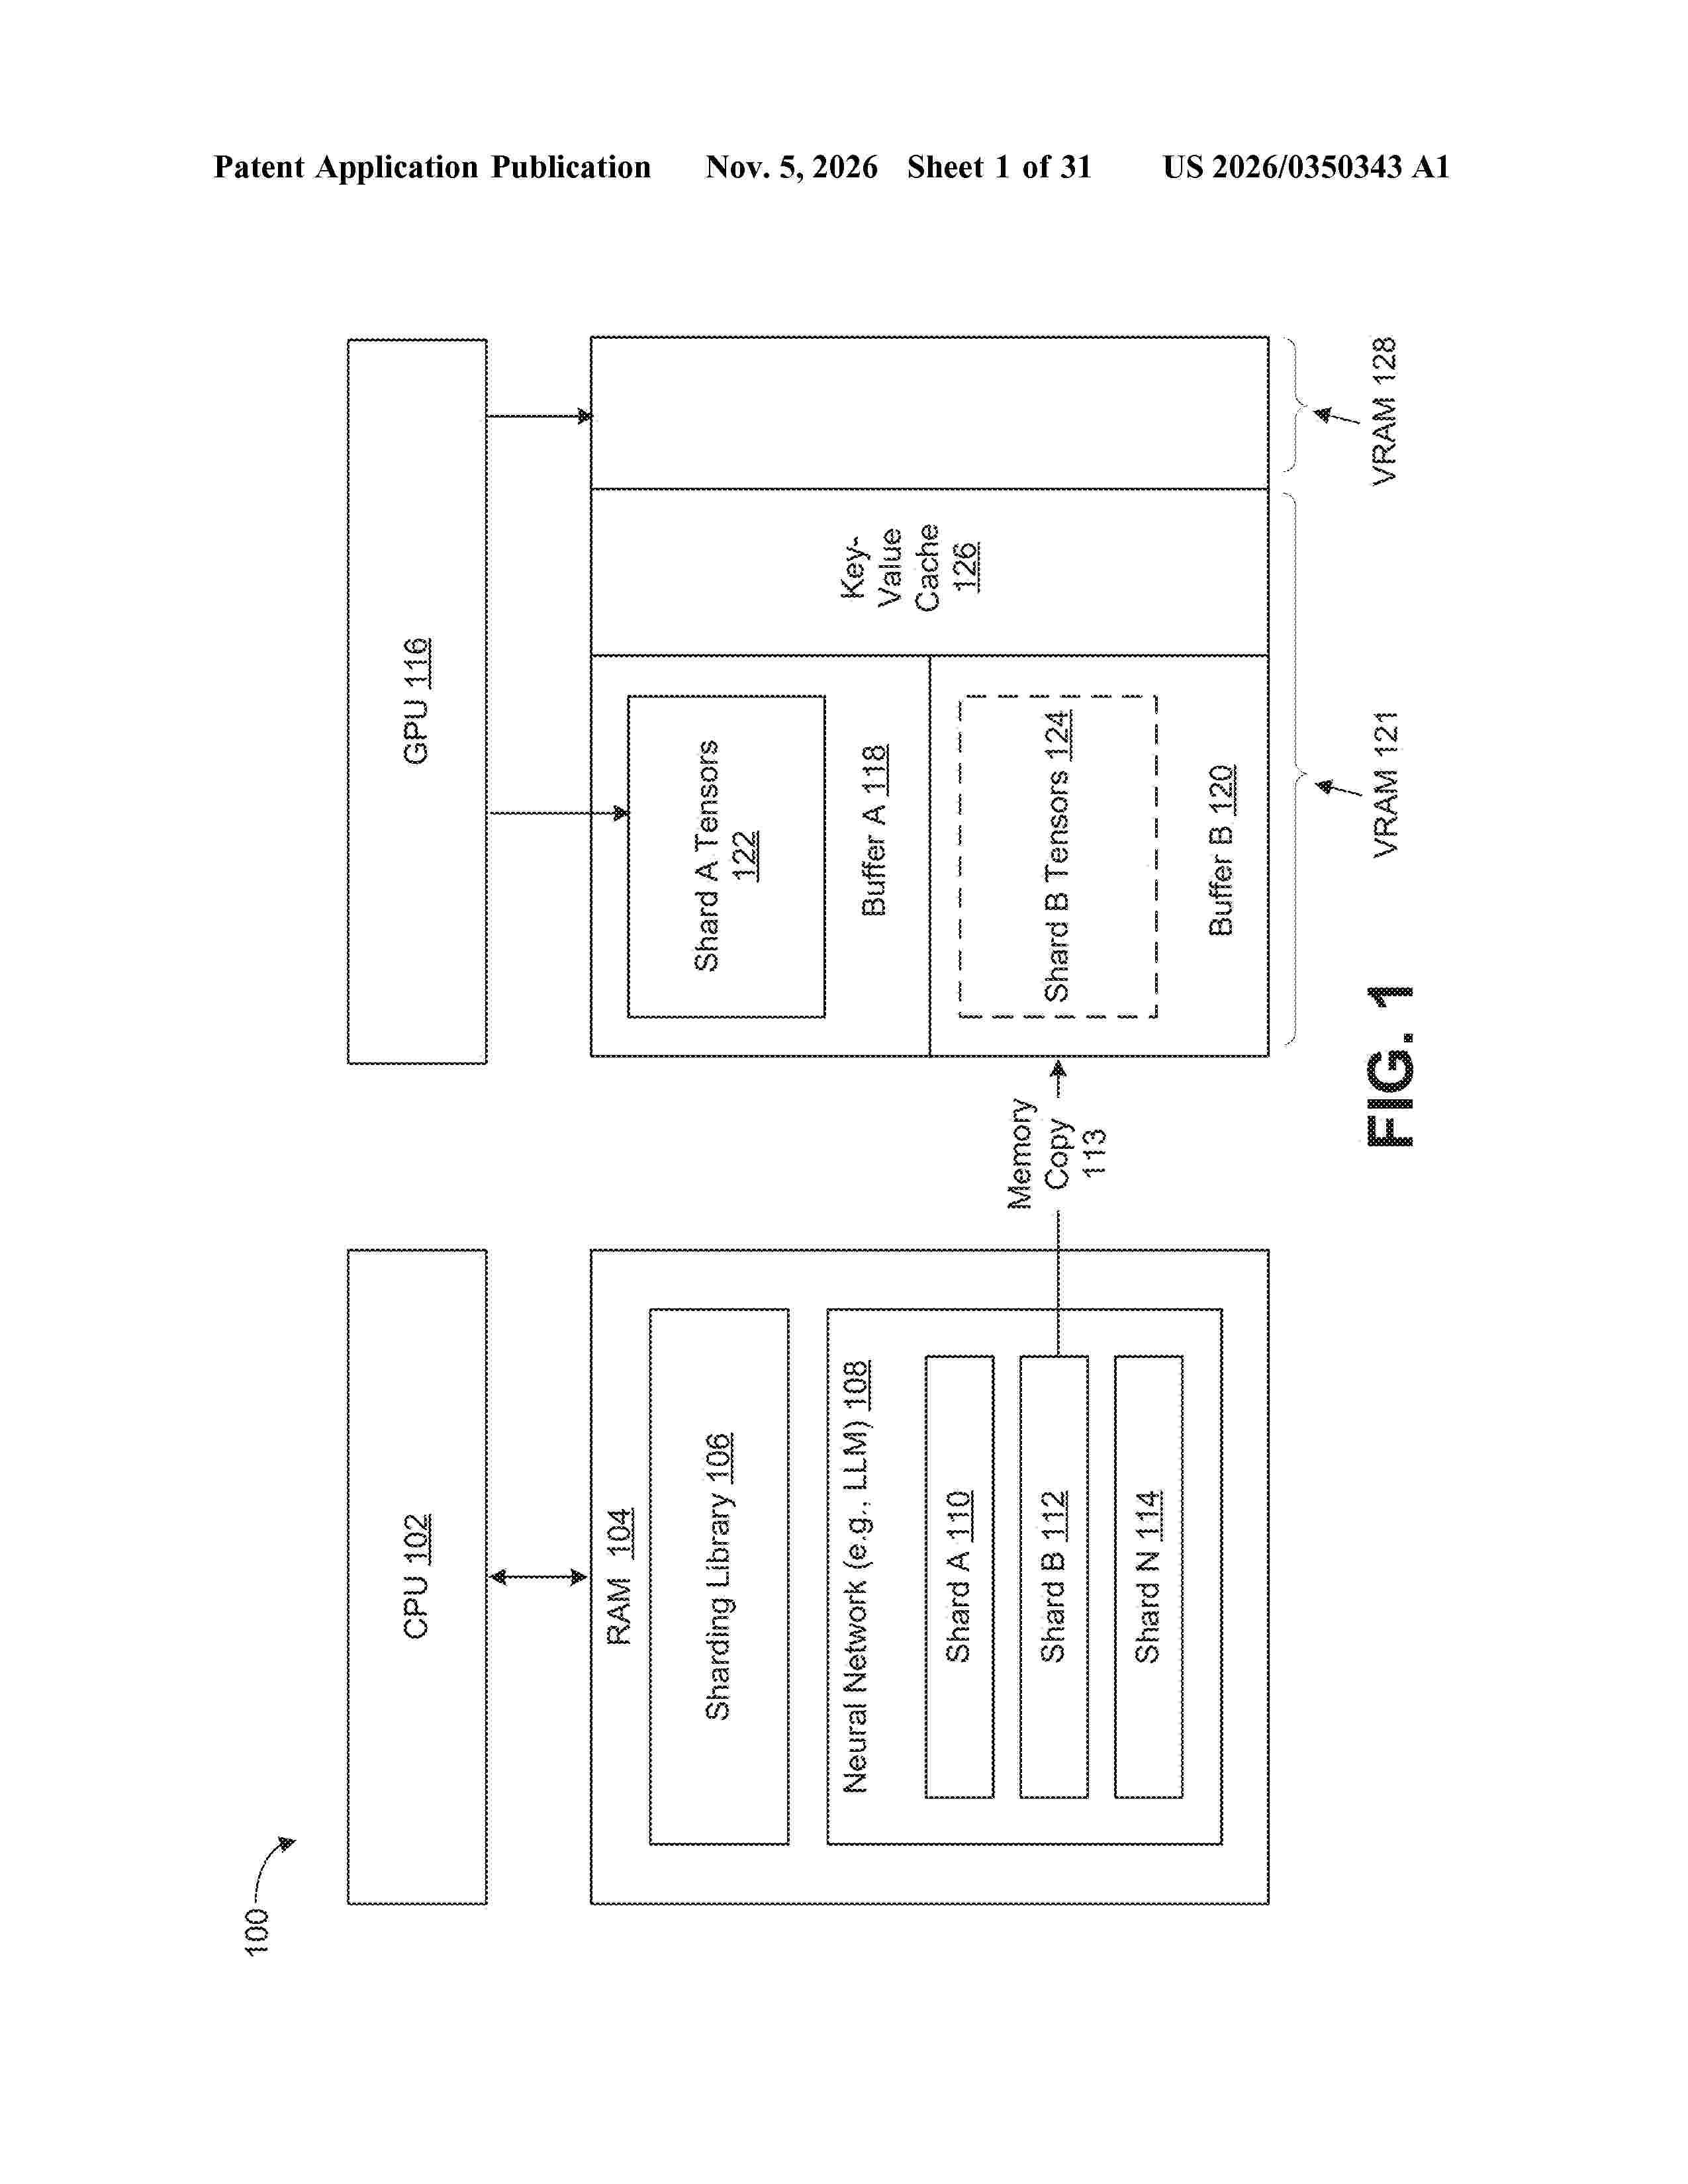
Resumen de: US20260350343A1
0000 Apparatuses, systems, and techniques to perform neural networks. For example, one or more processors cause a second portion of a neural network to be loaded into memory concurrently with inference performed using a first portion of the neural network; and cause the loaded second portion to be used to perform inference using output of the first portion of the neural network.
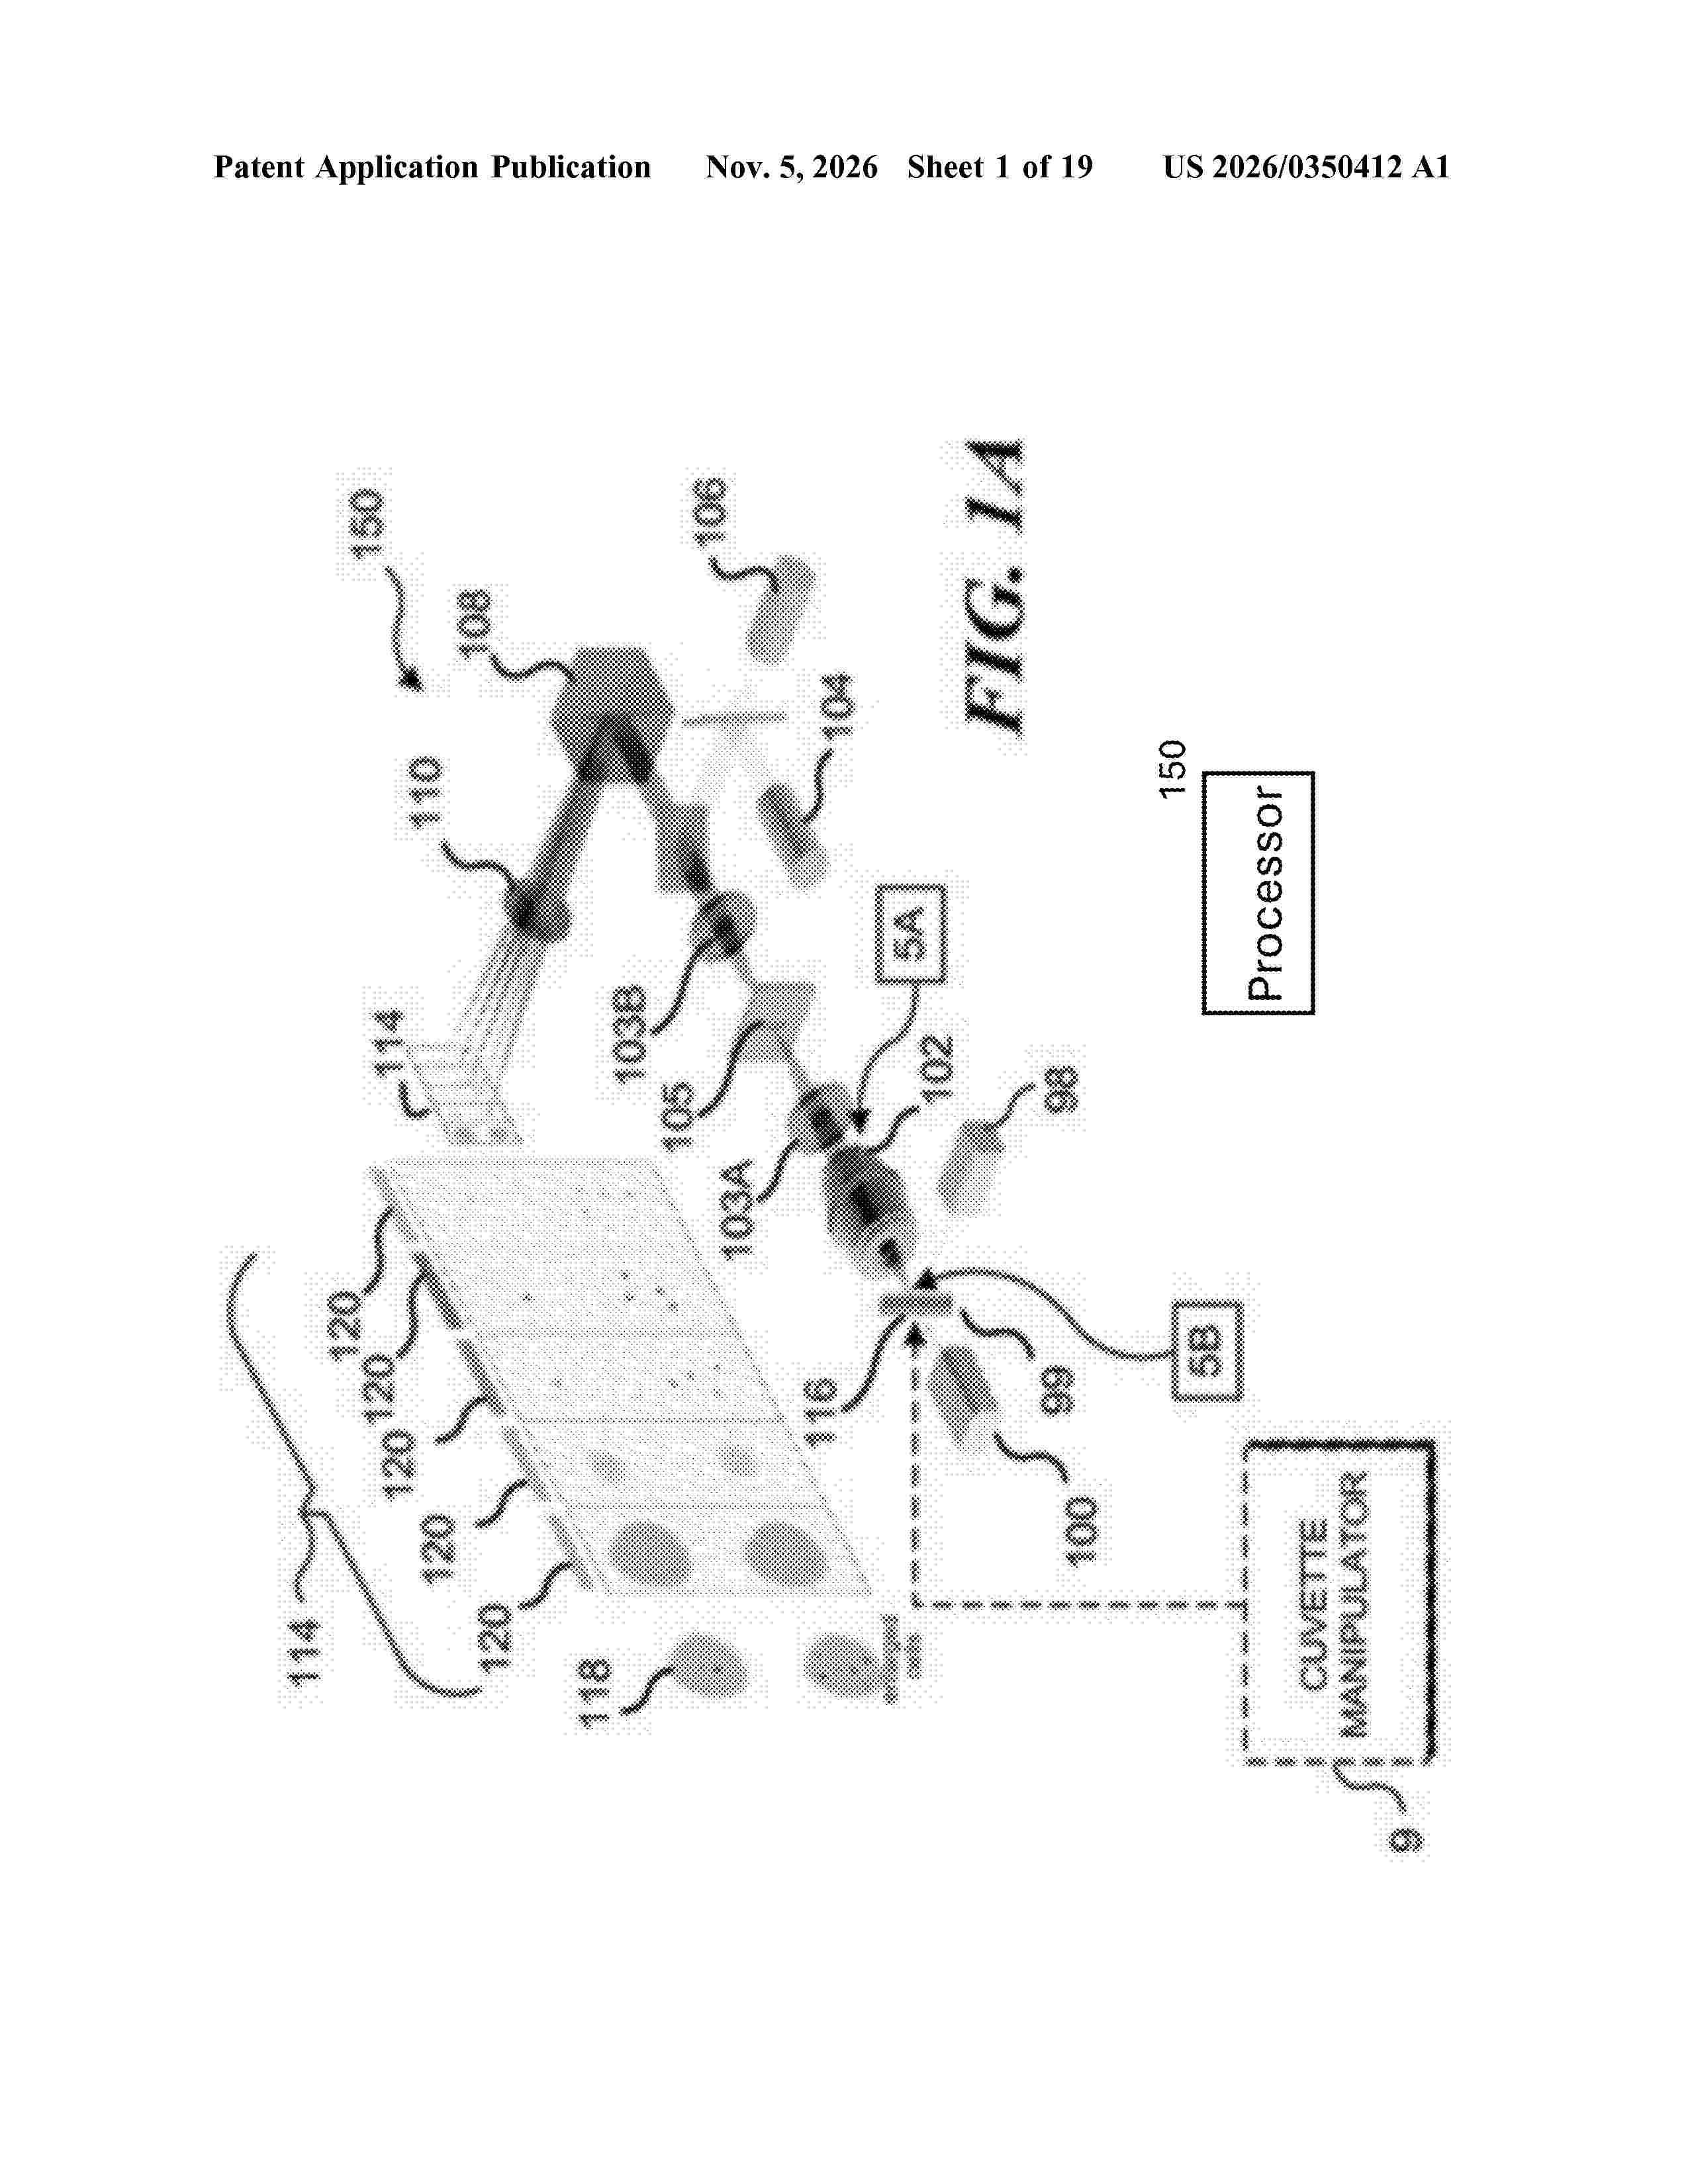
Resumen de: US20260350412A1
Methods of speeding the training of a convolutional neural network (CNN) to classify new images of biological cells captured by an imaging flow cytometer (IFC) are disclosed. Transfer learning with and without mapping is used based on the selection of pre-trained CNN to be used. New images of biological cells can be classified with new classes that are provided such as classes for red blood cells and classes for DNA damage of lymphoma biological cells.
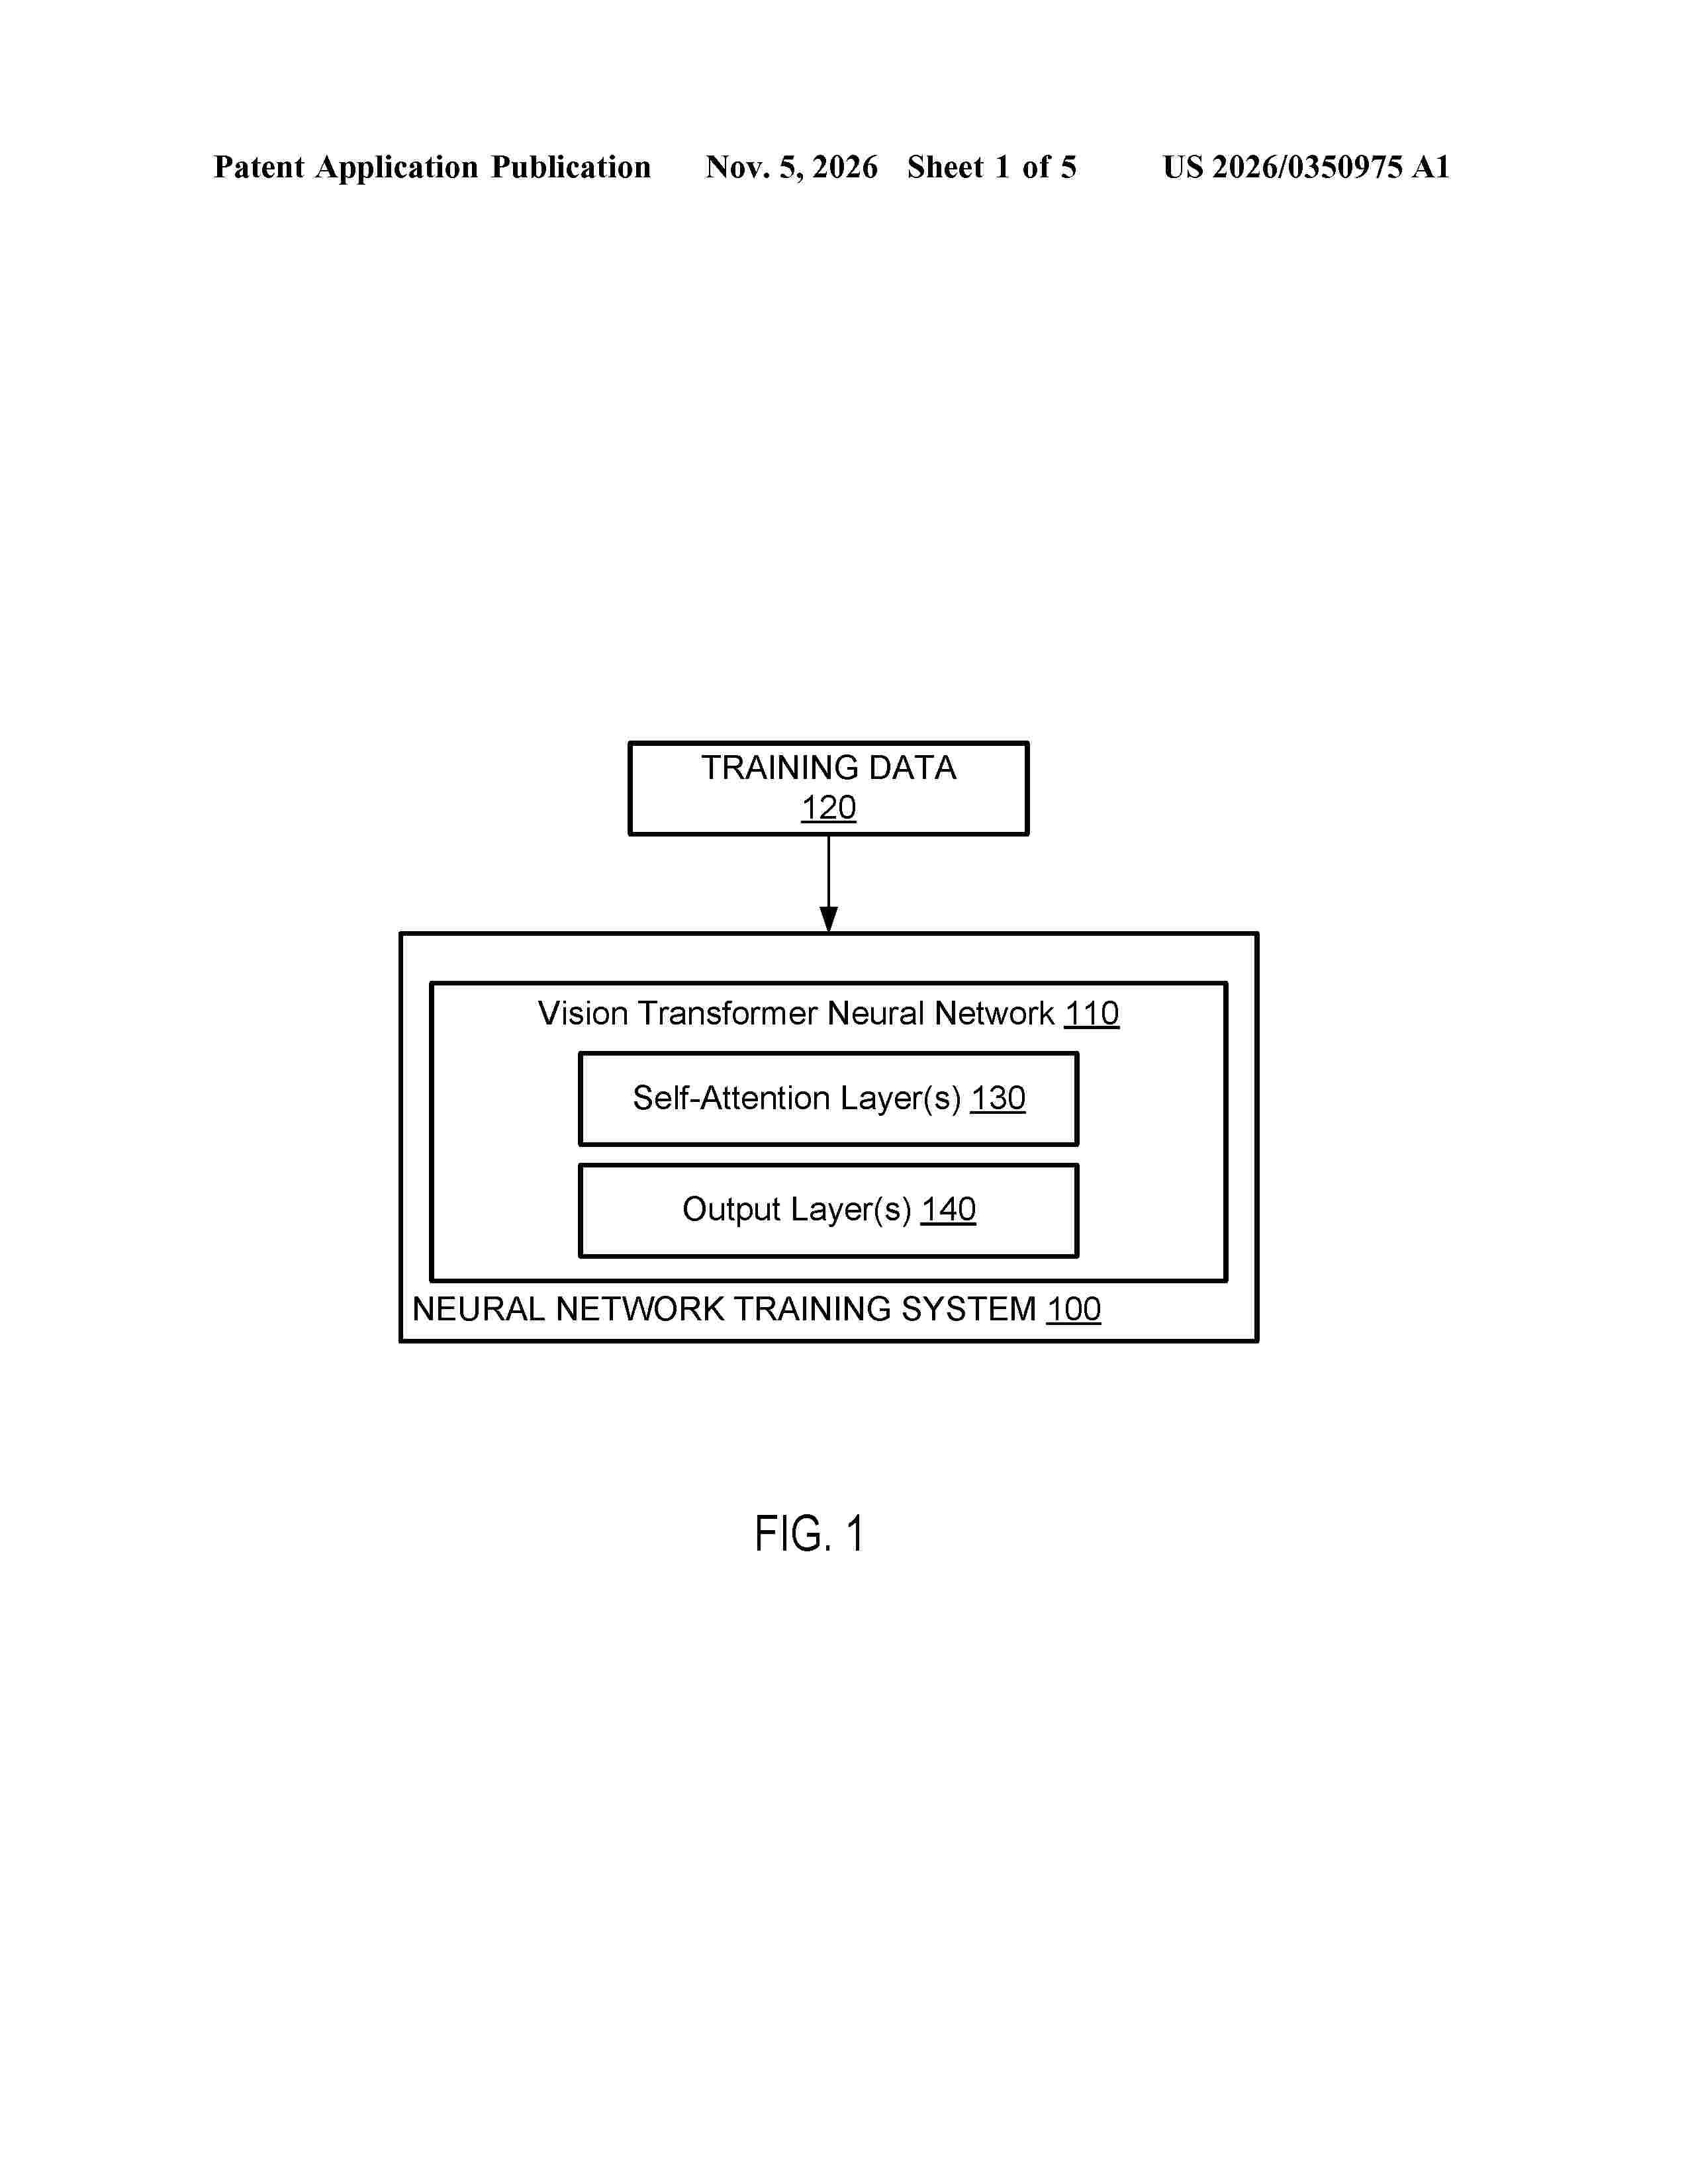
Resumen de: US20260350975A1
0000 Methods, systems, and apparatus, including computer programs encoded on computer storage media, for training Vision Transformer (ViT) neural networks.
Resumen de: US20260350739A1
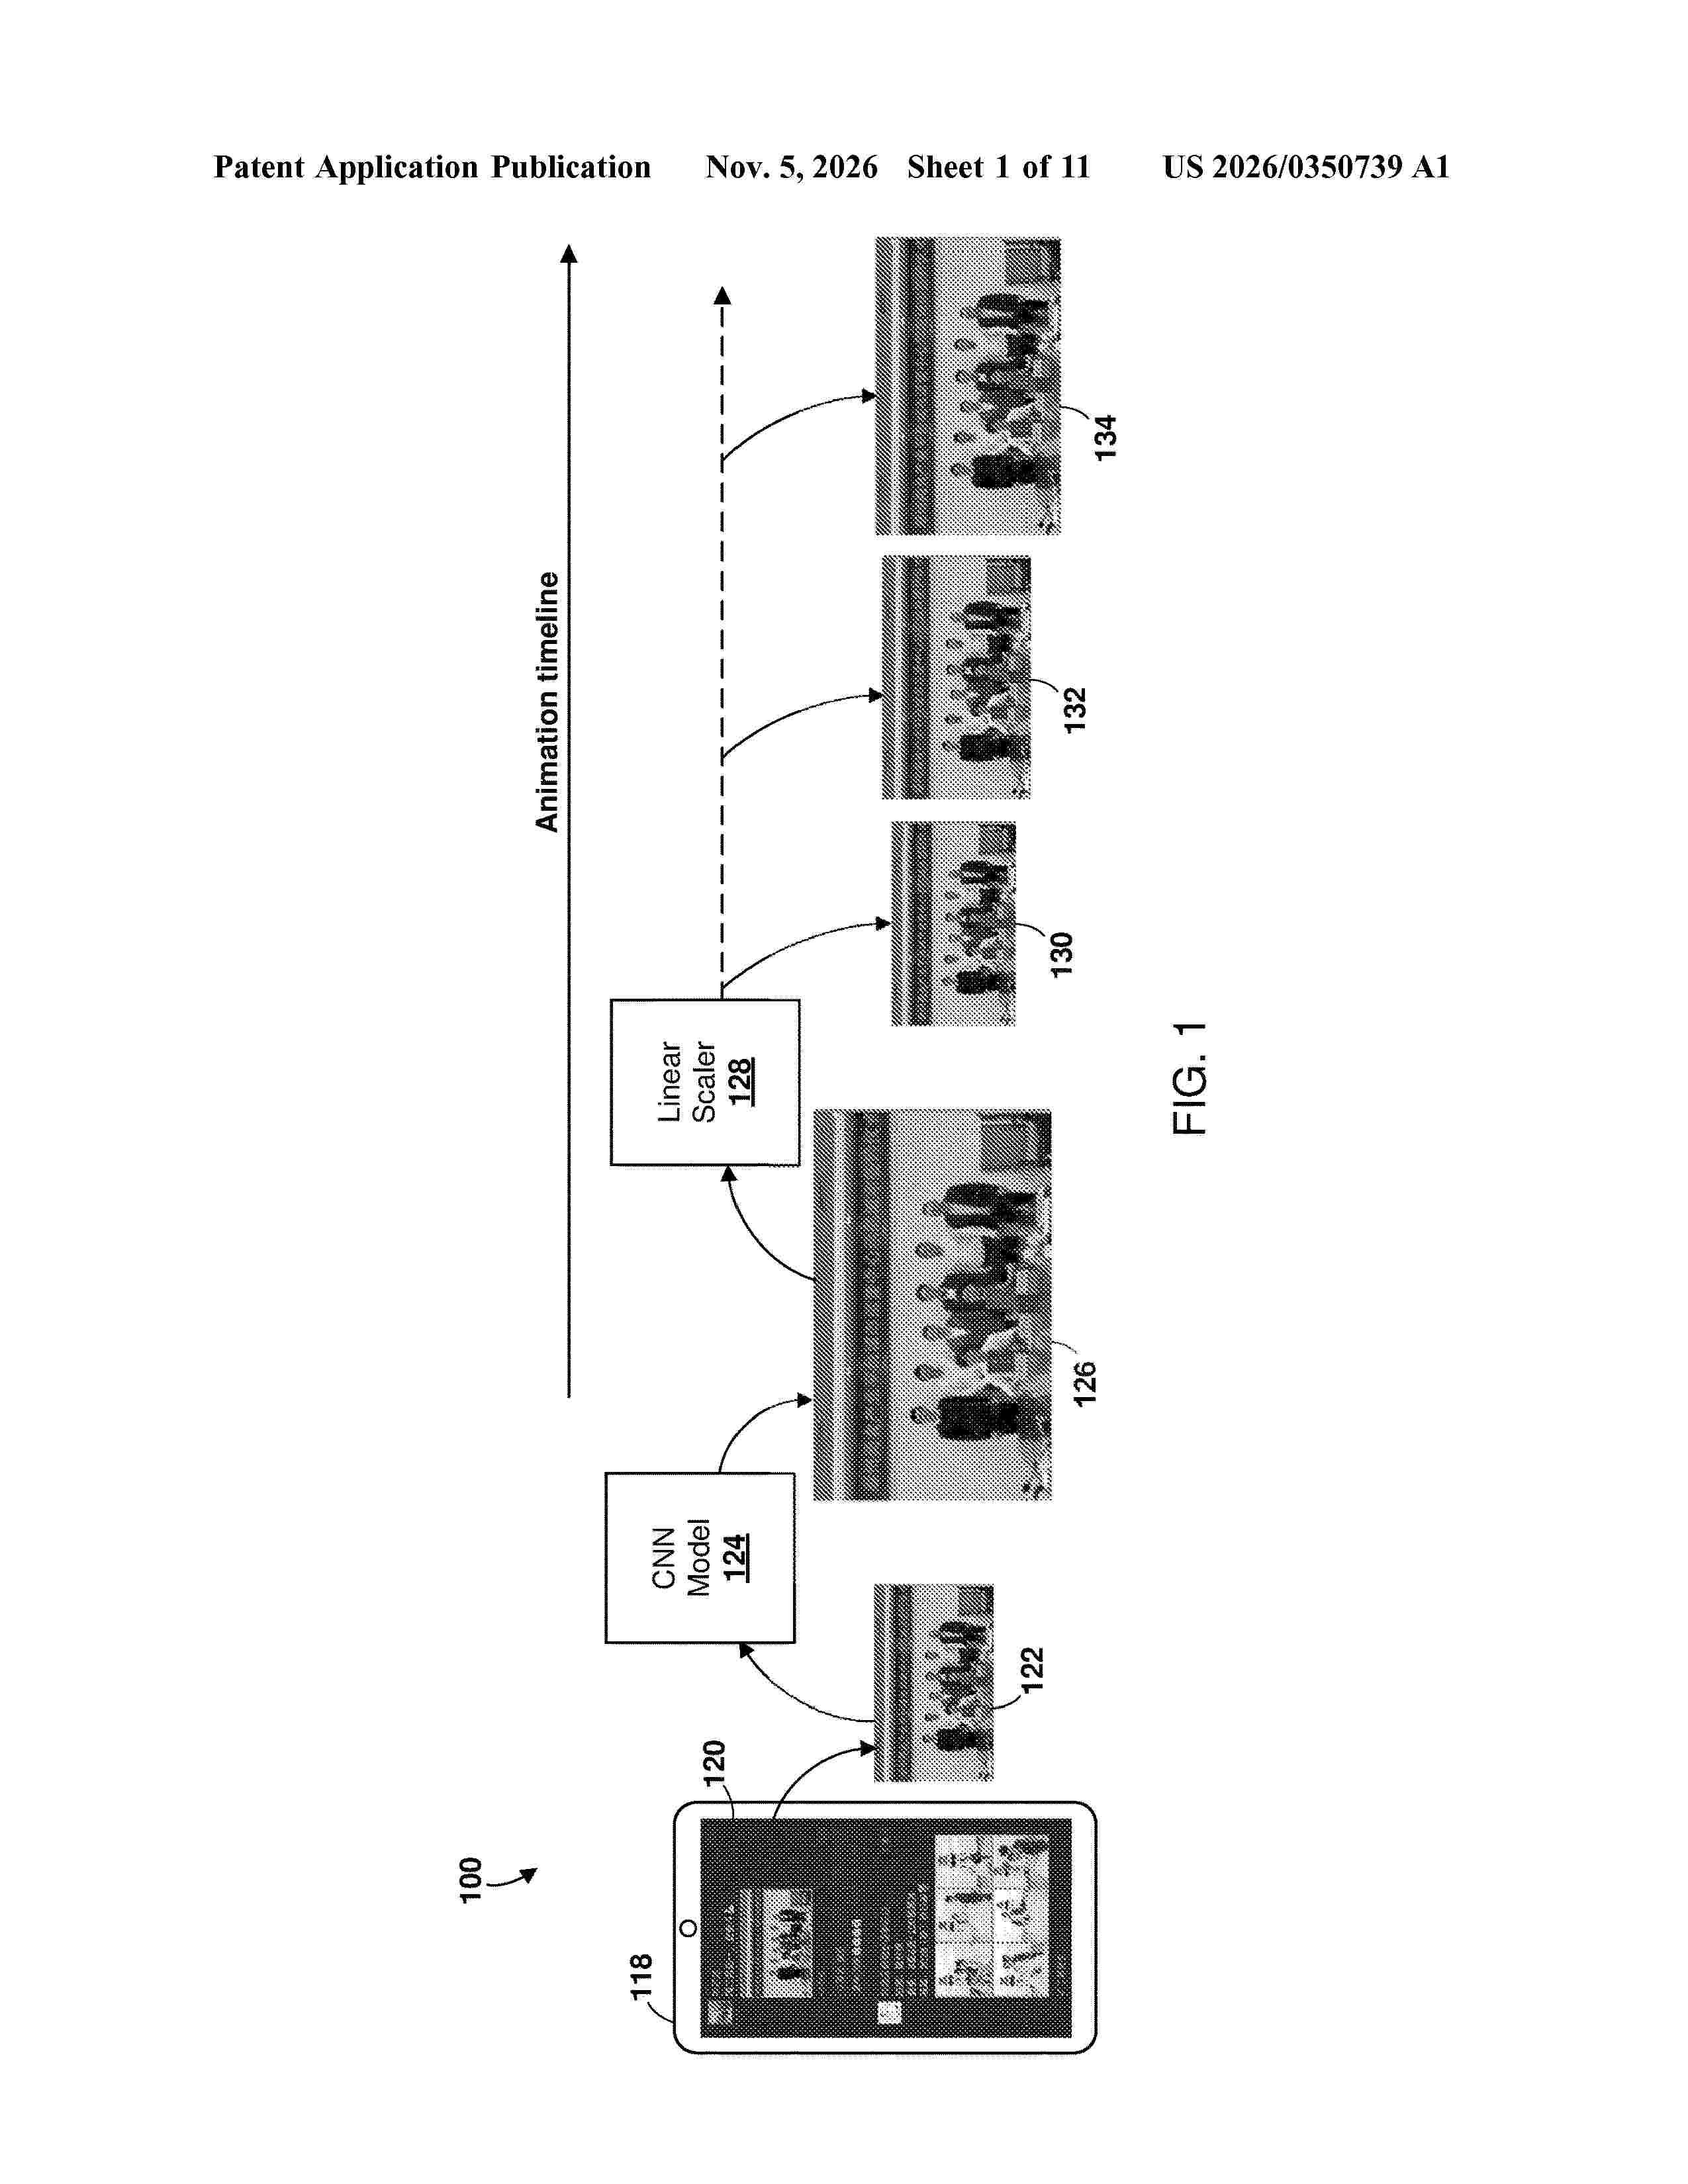
Systems and methods for performing a zoom operation on a display of a computing device, which include identifying a region of interest (ROI) of an image presented on the display based on a zoom user input, determining a scaling factor for a final zoomed presentation of the ROI based on an image rendering requirement and/or an inference speed of a frame generation convolutional neural network (CNN), using the CNN to generate the final zoomed presentation of the ROI to the determined scaling factor, down-scaling the final zoomed presentation to generate a sequence of intermediate size image frames each having dimensions smaller than dimensions of the final zoomed presentation of the ROI and greater than dimensions of the ROI, and rendering an animation of changes in a displayed size of the ROI using the sequence of intermediate image frames of the ROI.
Resumen de: CA3329704A1
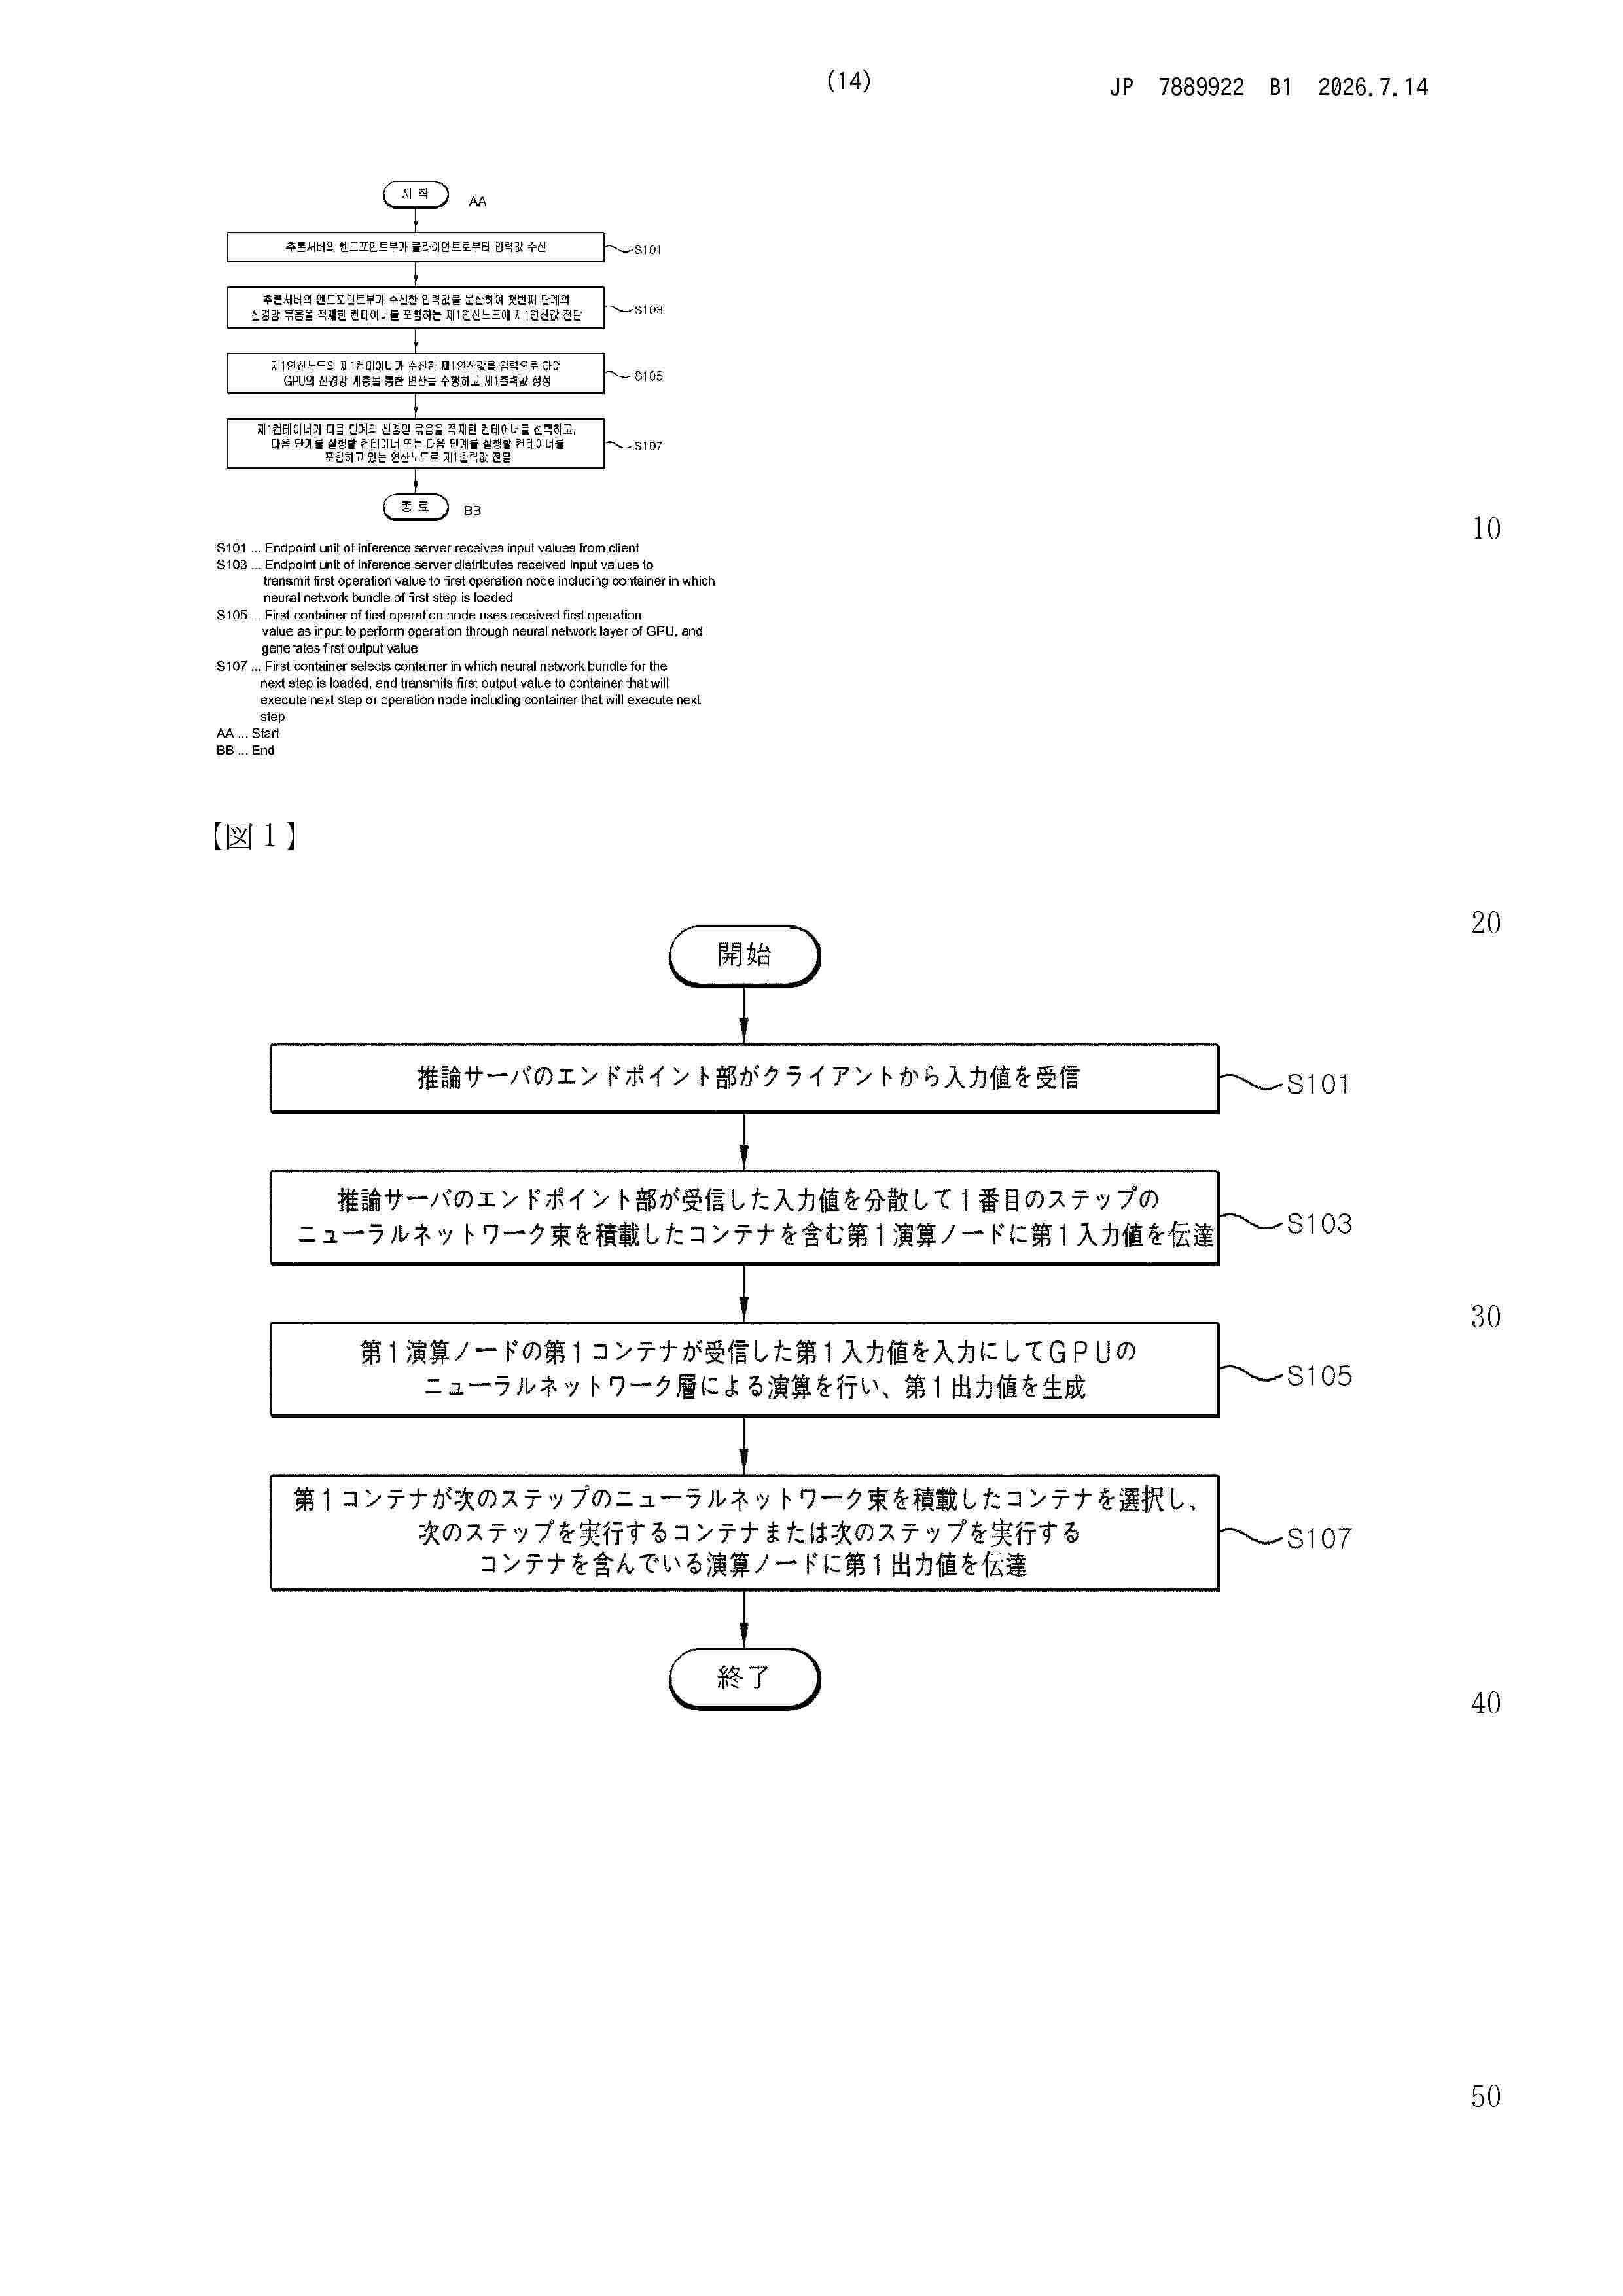
The present invention relates to a multi-node cluster-based inference method through GPU separation allocation of a pre-trained layer and a fine-tuning layer of multiple deep learning models. According to an embodiment of the present disclosure, the method includes: receiving, by an endpoint unit of an inference server, an input value from a client; distributing, by the endpoint unit of the inference server, the received input value, and transmitting the first input value to a first computation node including a container in which a neural network bundle of a first stage is loaded; performing, by a first container of the first computation nodes, an operation through a neural network layer of a GPU by using the received first input value as an input, and generating a first output value; and selecting, by the first container, a container in which the neural network bundle of the next stage is loaded, and transmitting the second output value to the computation node that includes the container in which the next stage is to be executed or the container in which to execute the next stage.
Resumen de: WO2026227712A1
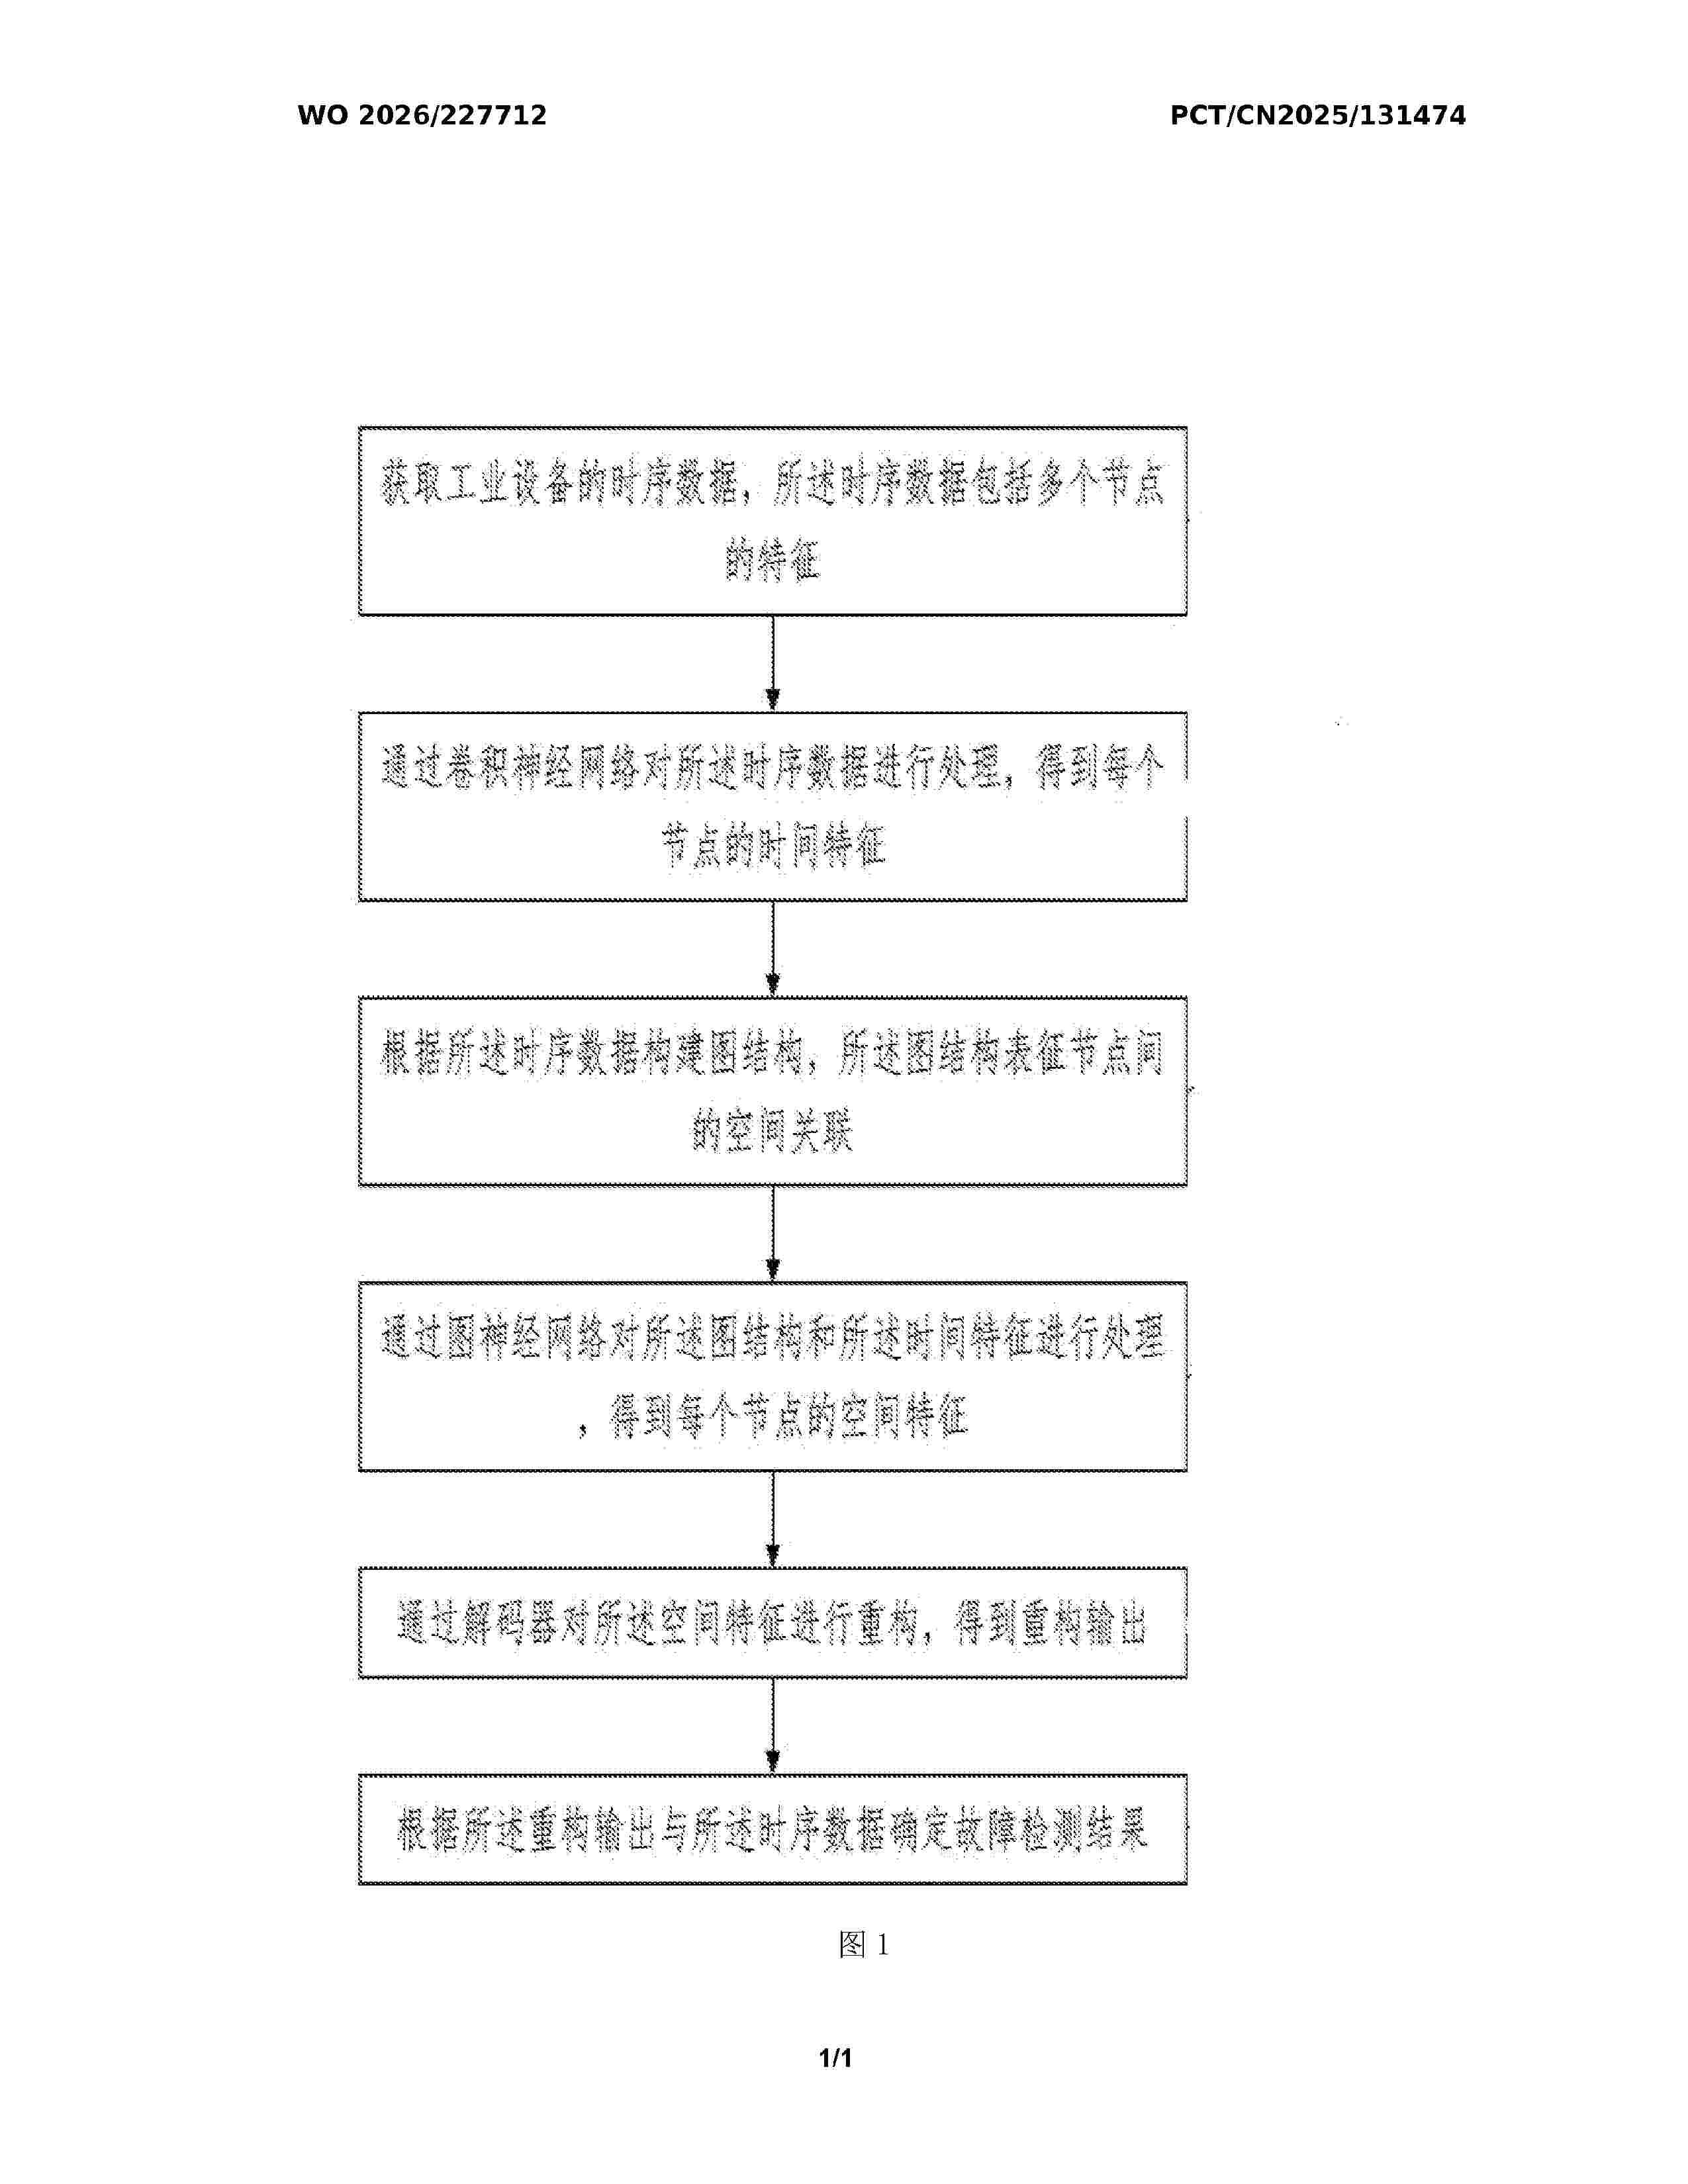
Provided is a reconstruction error-type fault detection method based on a graph neural network. The method comprises: obtaining time series data of industrial equipment, the time series data comprising features of a plurality of nodes; processing the time series data by means of a convolutional neural network to obtain a time feature of each node; constructing a graph structure on the basis of the time series data, the graph structure representing spatial association between the nodes; processing the graph structure and the time feature by means of a graph neural network to obtain a spatial feature of each node; reconstructing the spatial features by means of a decoder to obtain a reconstructed output; and determining a fault detection result on the basis of the reconstructed output and the time series data. The reconstruction error-type fault detection method based on the graph neural network improves the accuracy and robustness of fault detection, is suitable for real-time monitoring and predictive maintenance of complex industrial systems, and has important practical value.
Resumen de: US20260346145A1
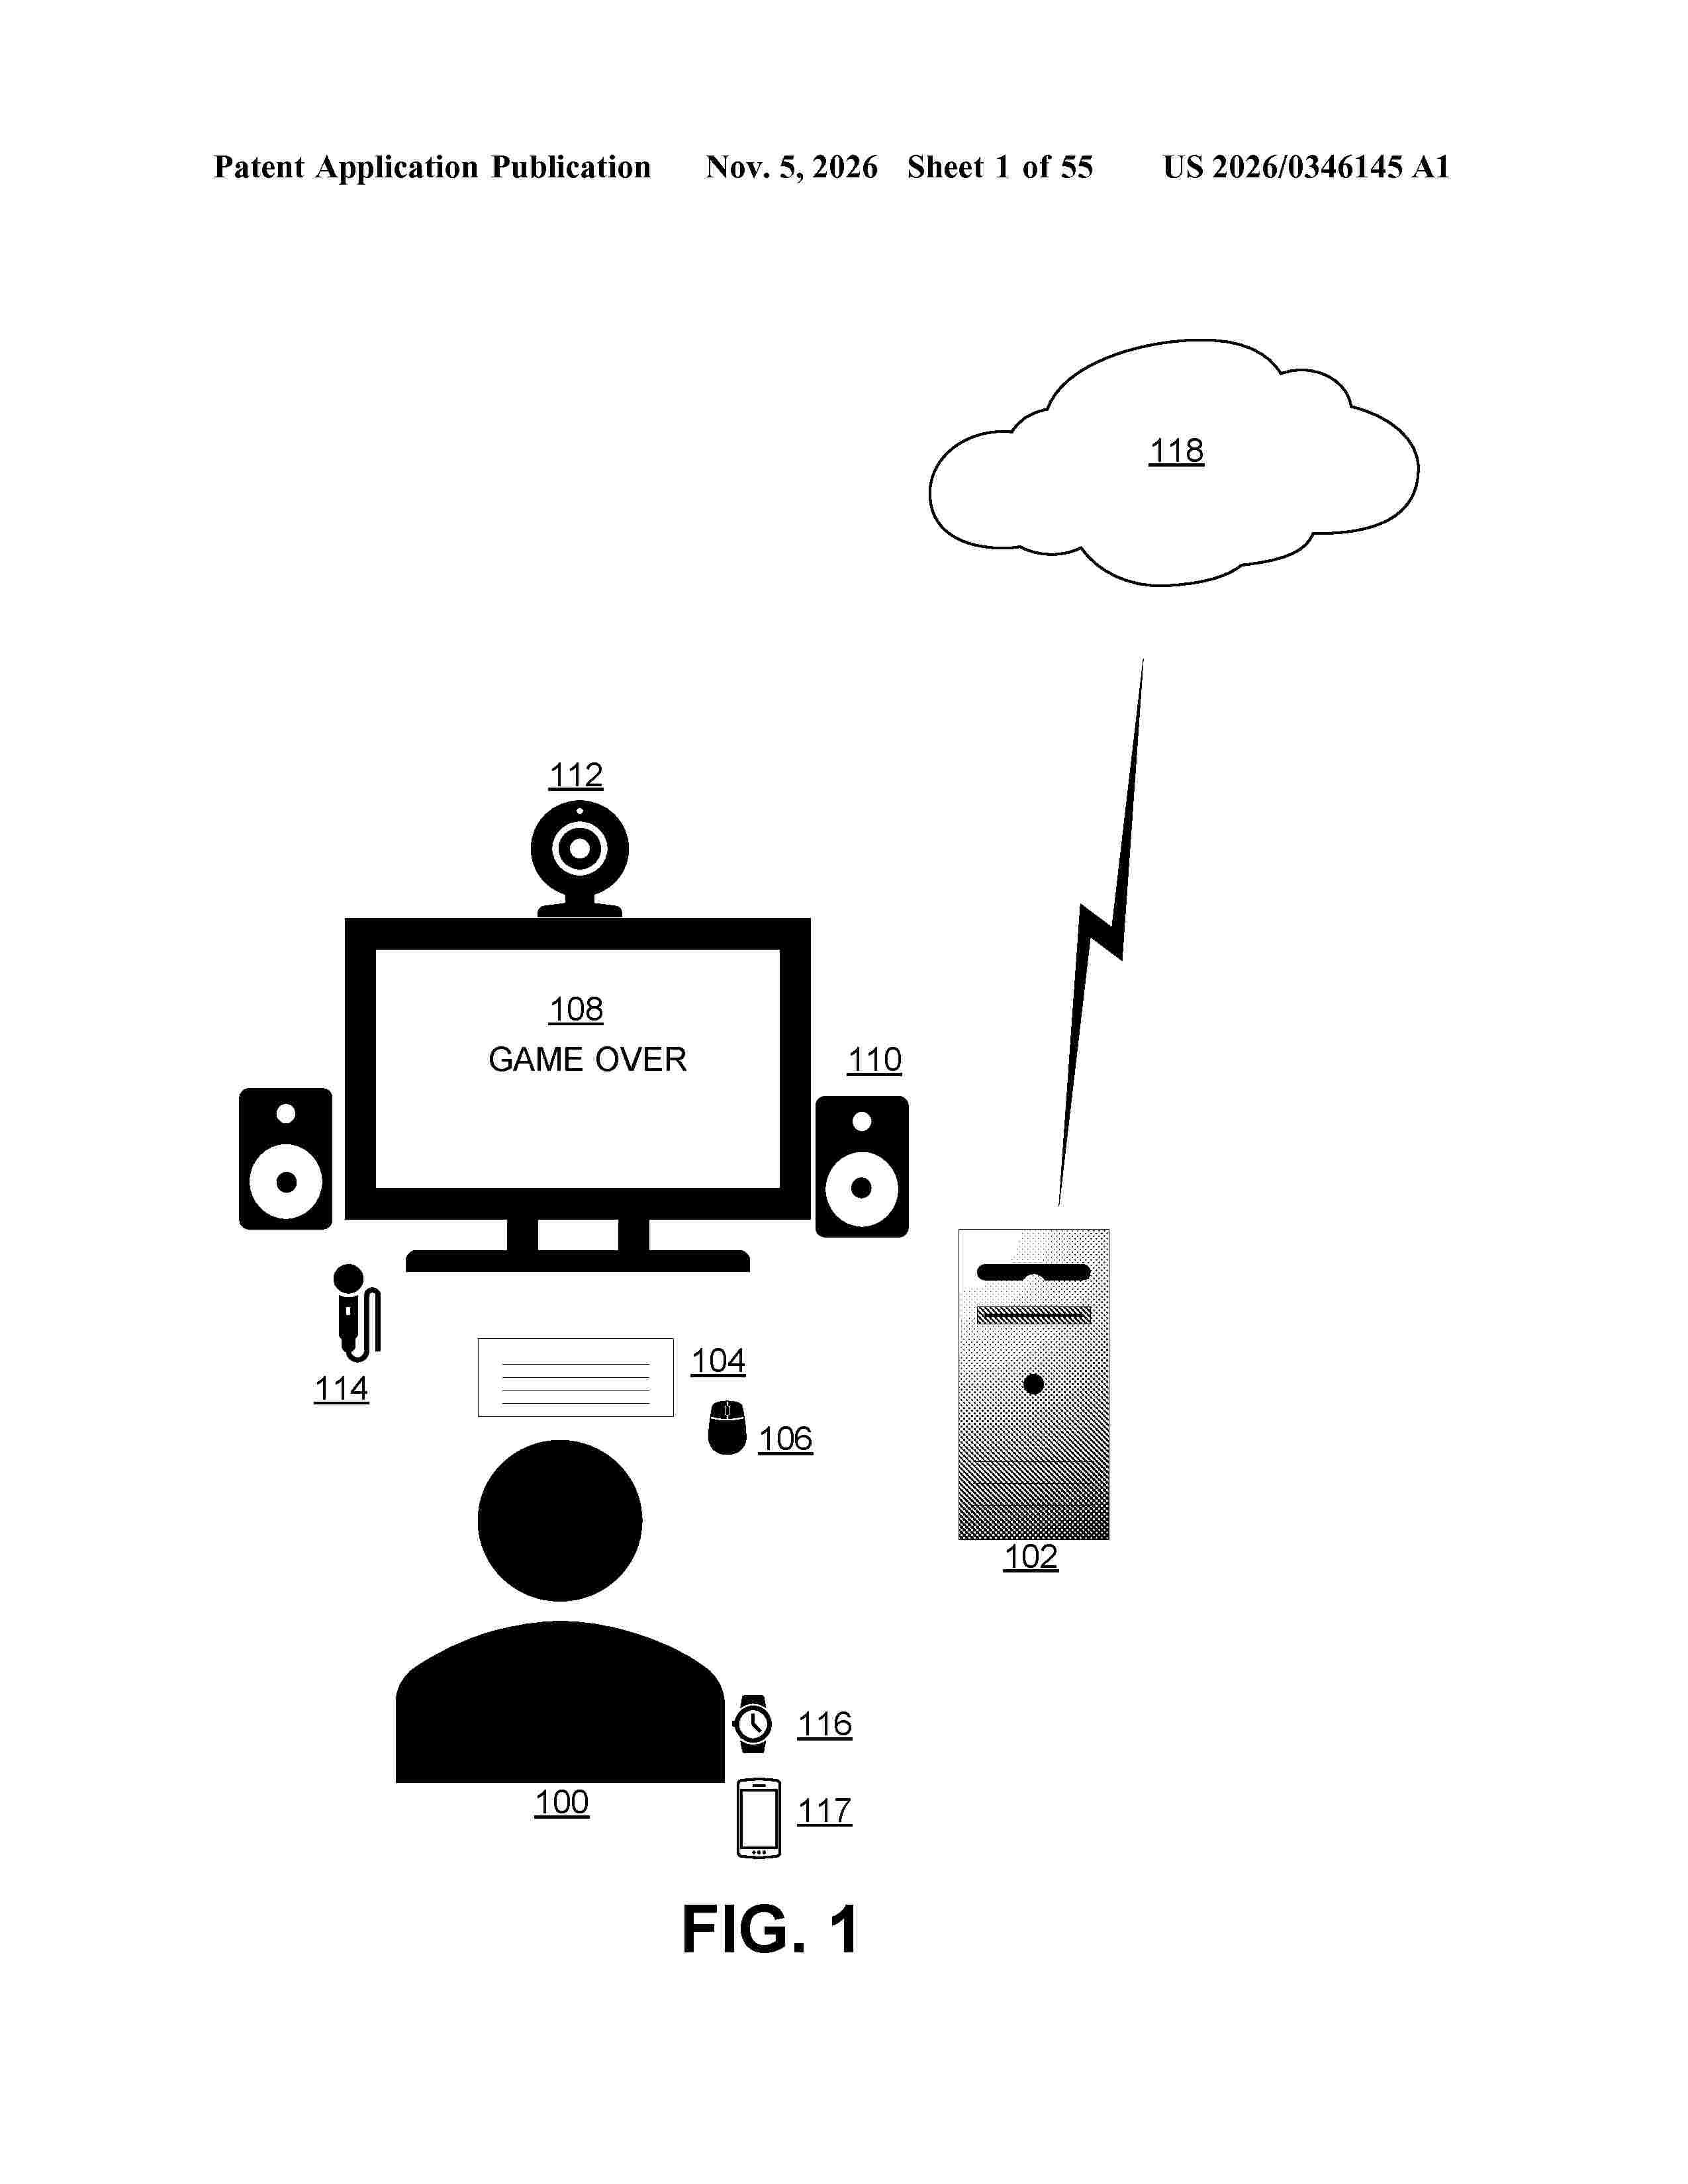
0000 Apparatuses, systems, and techniques to provide emotion-based experience adjustment. In at least one embodiment, one or more neural networks are used to adjust one or more properties of one or more games based on an emotional state of a user.
Resumen de: WO2026232172A2
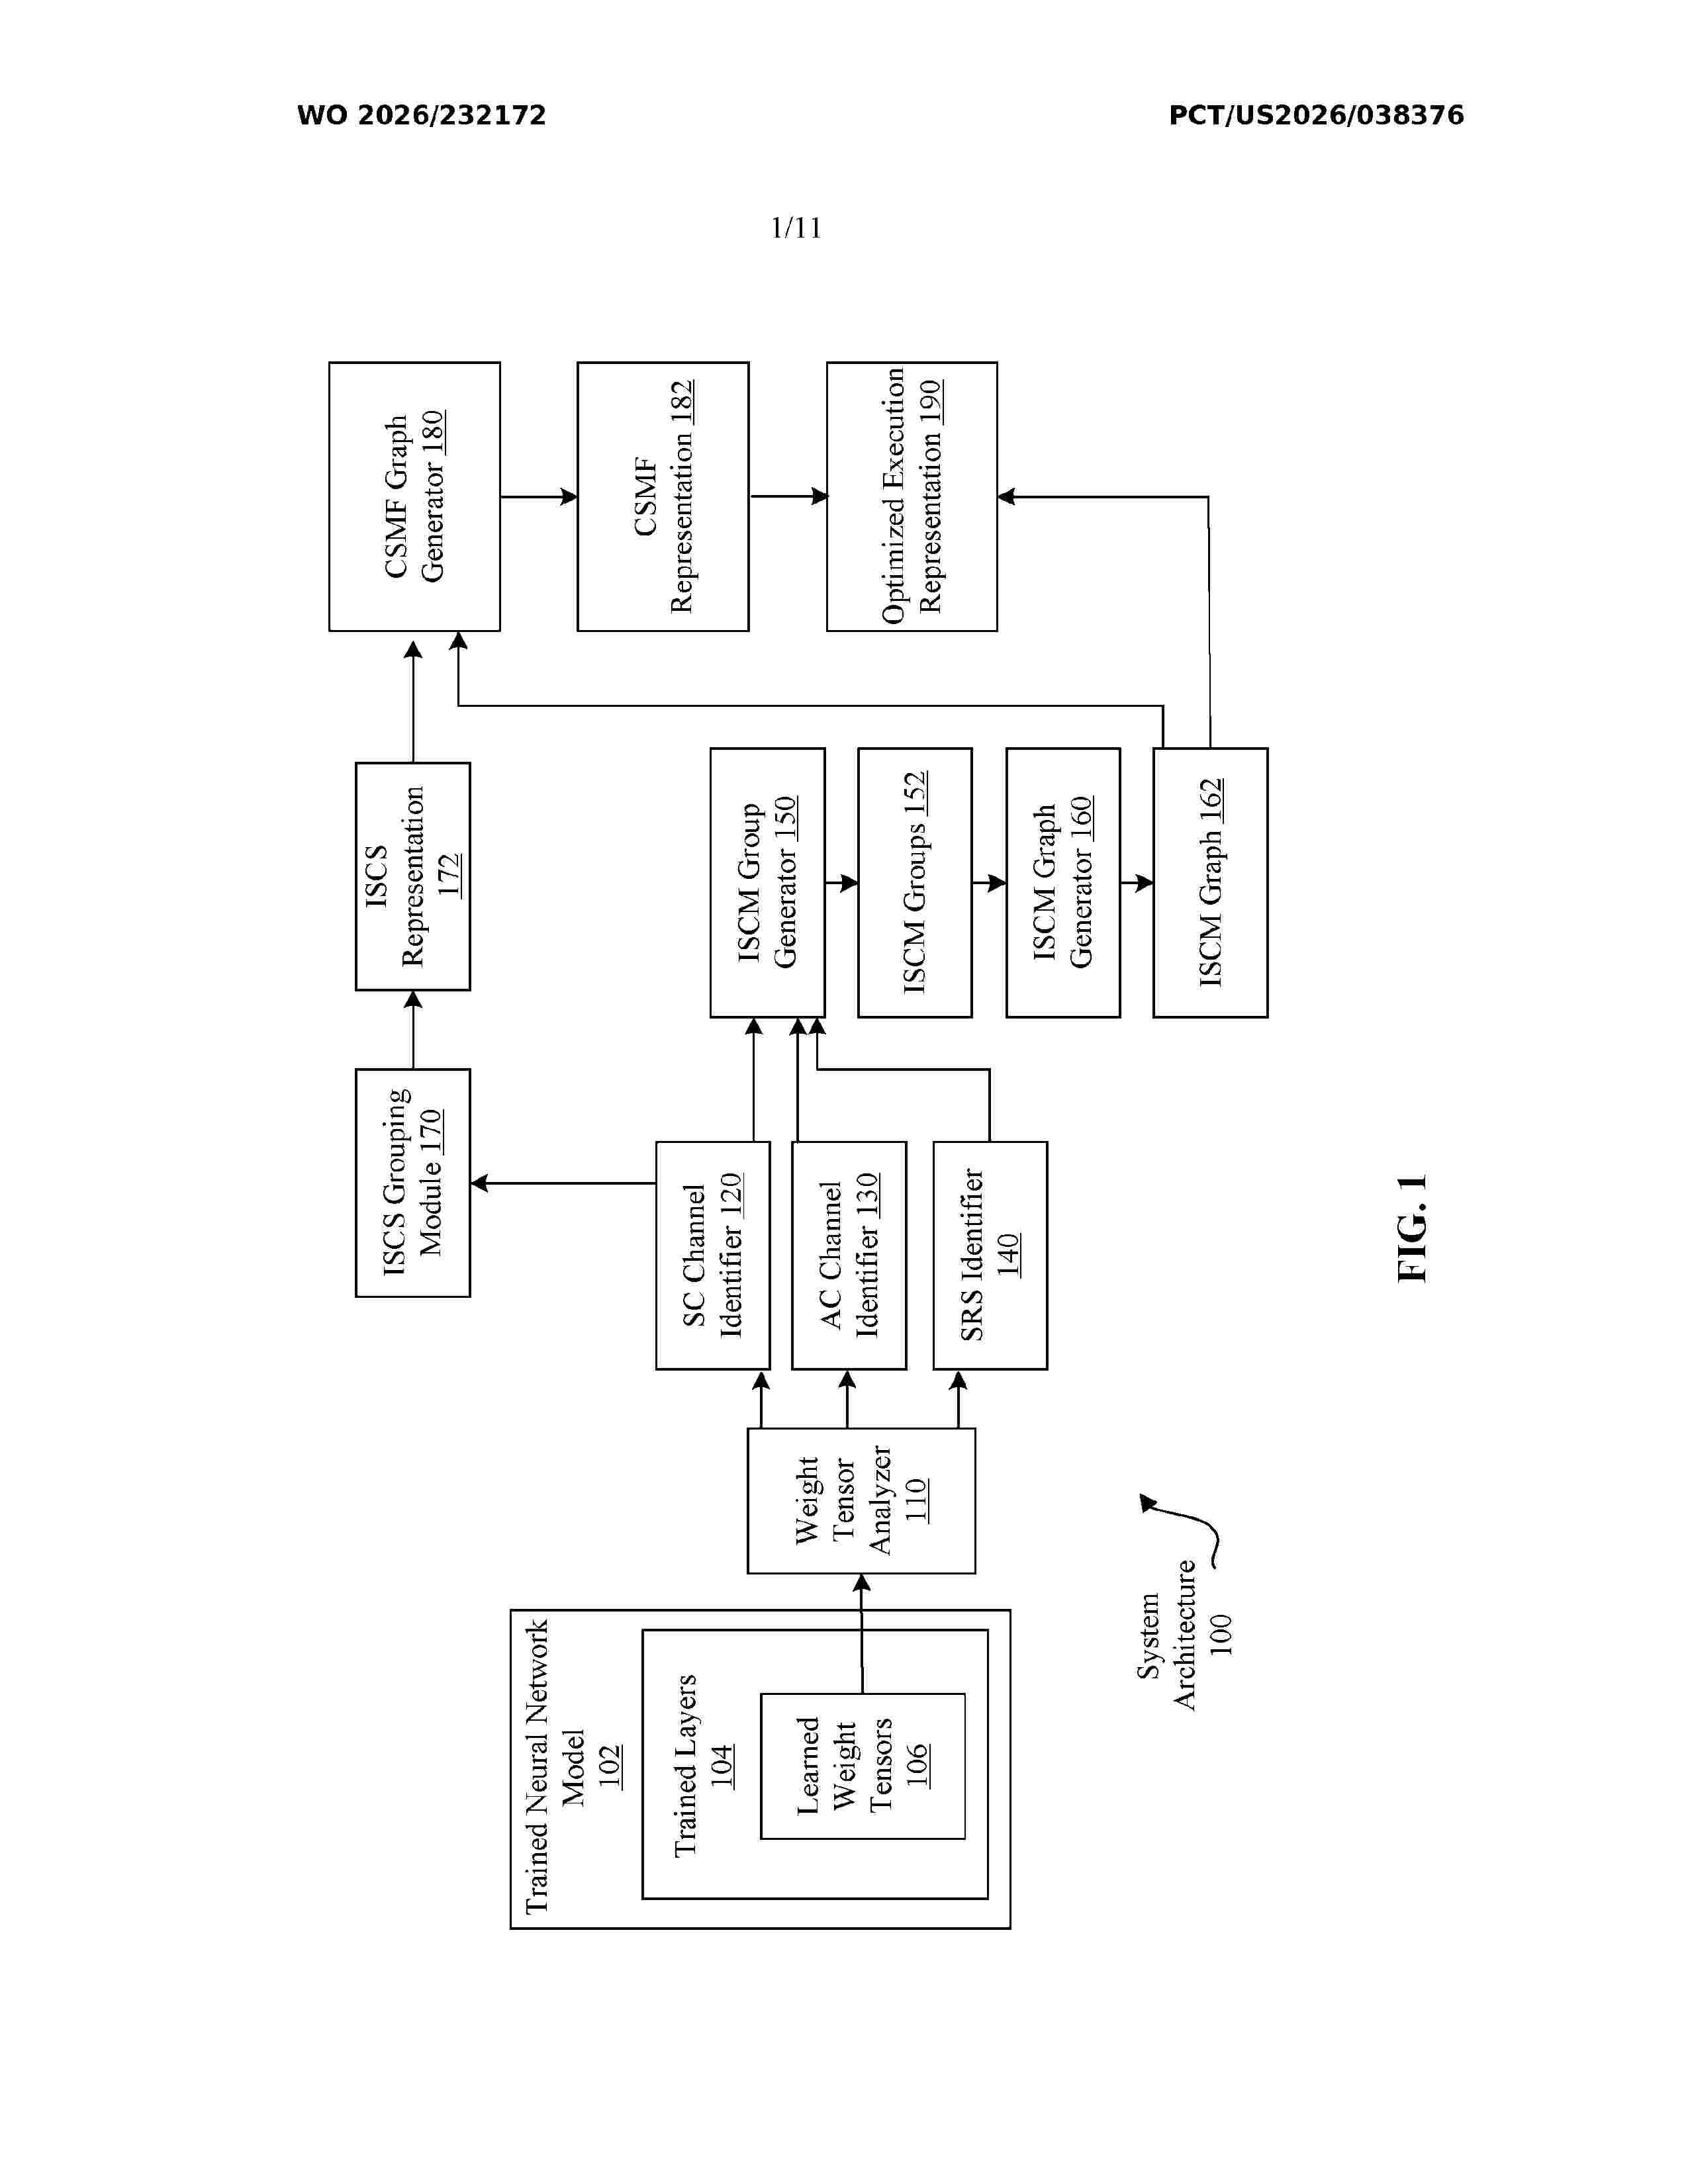
A method for utilizing a Structural Receptive Set (SRS) structure in a trained neural network model includes accessing learned weight tensors of a trained neural network layer comprising input channels and output channels. Semantic Core (SC) channels are identified from the output channels based on the learned weight tensors. For an SC channel, a Structure Auxiliary (AC) channel set is identified based on structural similarity among output-channel weight tensors. An SRS comprising a subset of the input channels structurally used to compute an SC/AC output group is determined for the SC channel and the AC channel set. An Invariant Structure Channel Mapping (ISCM) group comprising the SC channel, the AC channel set, and the SRS is generated and used to produce a sparse input-output dependency structure that enables the SC/AC output group to be computed from fewer than all input channels.
Resumen de: EP4835739A2
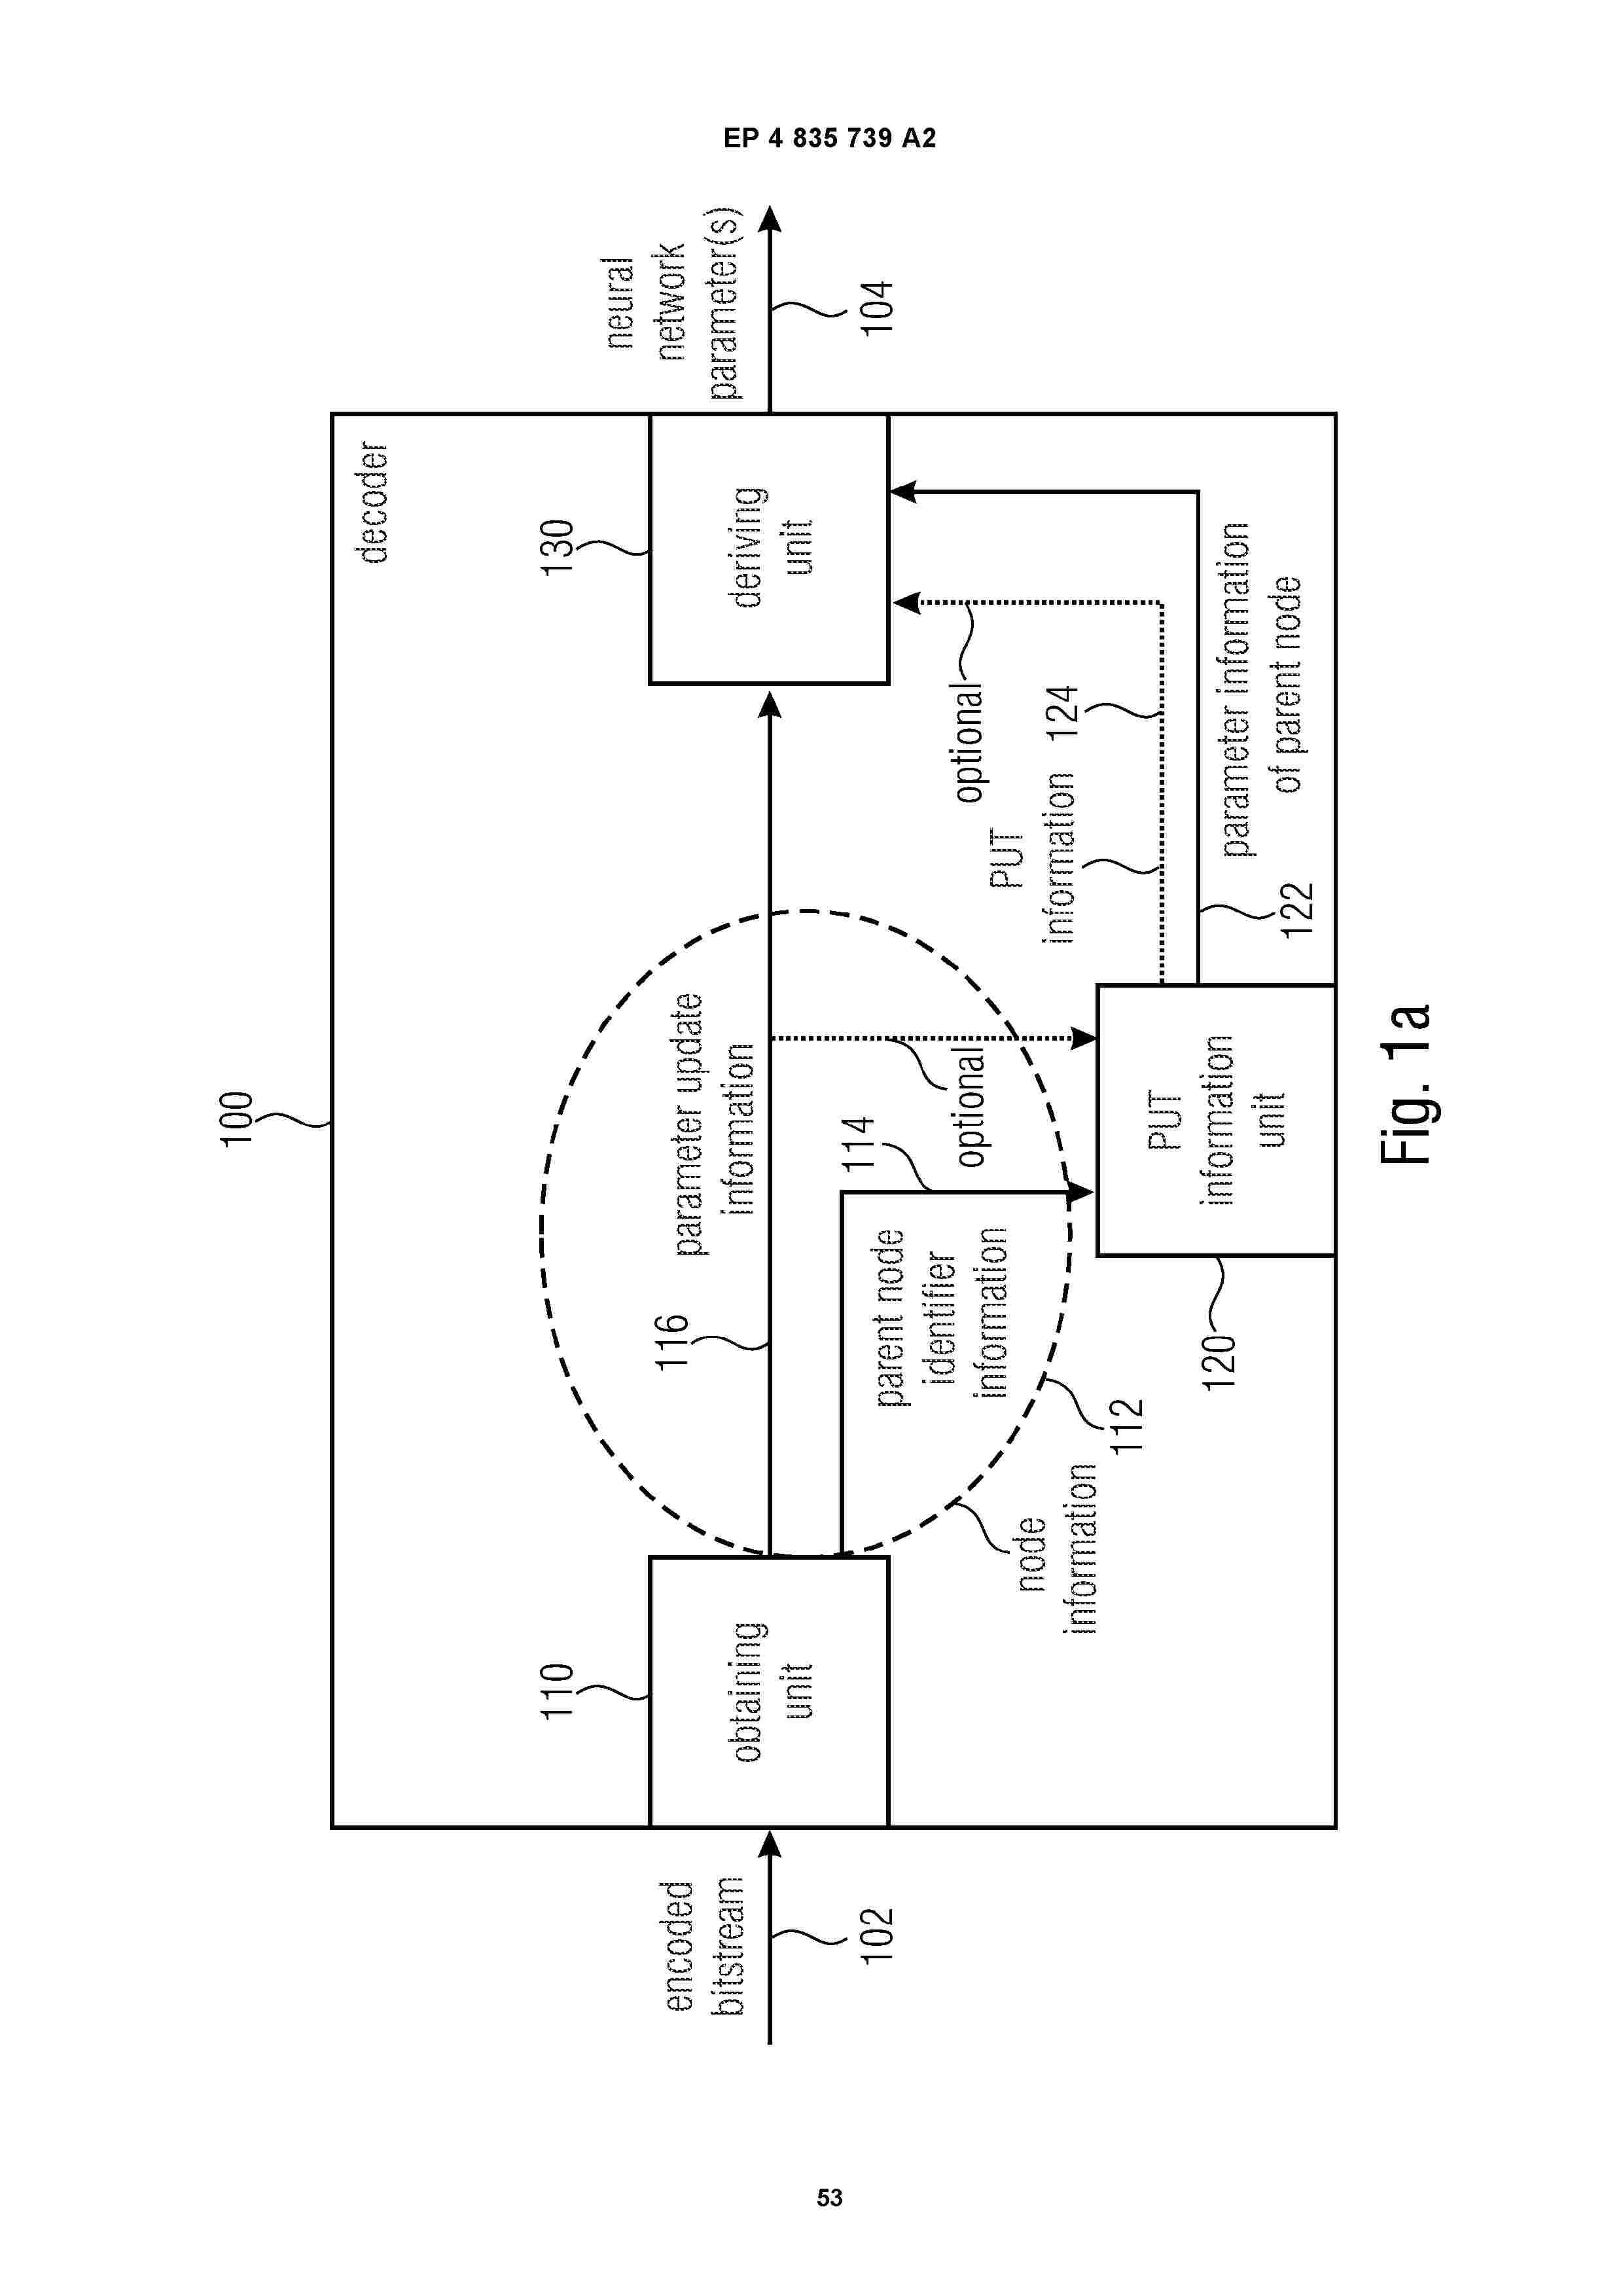
0001 Embodiments according to the invention comprise a decoder for decoding parameters of a neural network, wherein the decoder is configured to obtain a plurality of neural network parameters of the neural network on the basis of an encoded bitstream. Furthermore, the decoder is configured to obtain, e.g. to receive; e.g. to extract from an encoded bitstream, a node information describing a node of a parameter update tree, wherein the node information comprises a parent node identifier, which is, for example, a unique parent node identifier, for example an integer number, a string, and/or a cryptographic hash, and wherein the node information comprises a parameter update information, e.g. one or more update instructions, for example a difference signal between initial neural network parameters and a newer version thereof, e.g. corresponding to a child node of the update tree. 0002 Moreover, the decoder is configured to derive one or more neural network parameters using parameter information of a parent node (the parameter information comprising, for example a node information of the parent node, the node information for example comprising a parameter update information and a parent node identifier of the parent node, e.g. for a recursive reconstruction or recursive determination or recursive calculation or recursive derivation of the one or more neural network parameters and/or for example comprising a node parameter of the parent node, e.g. neural network parameters a
Resumen de: EP4835741A1
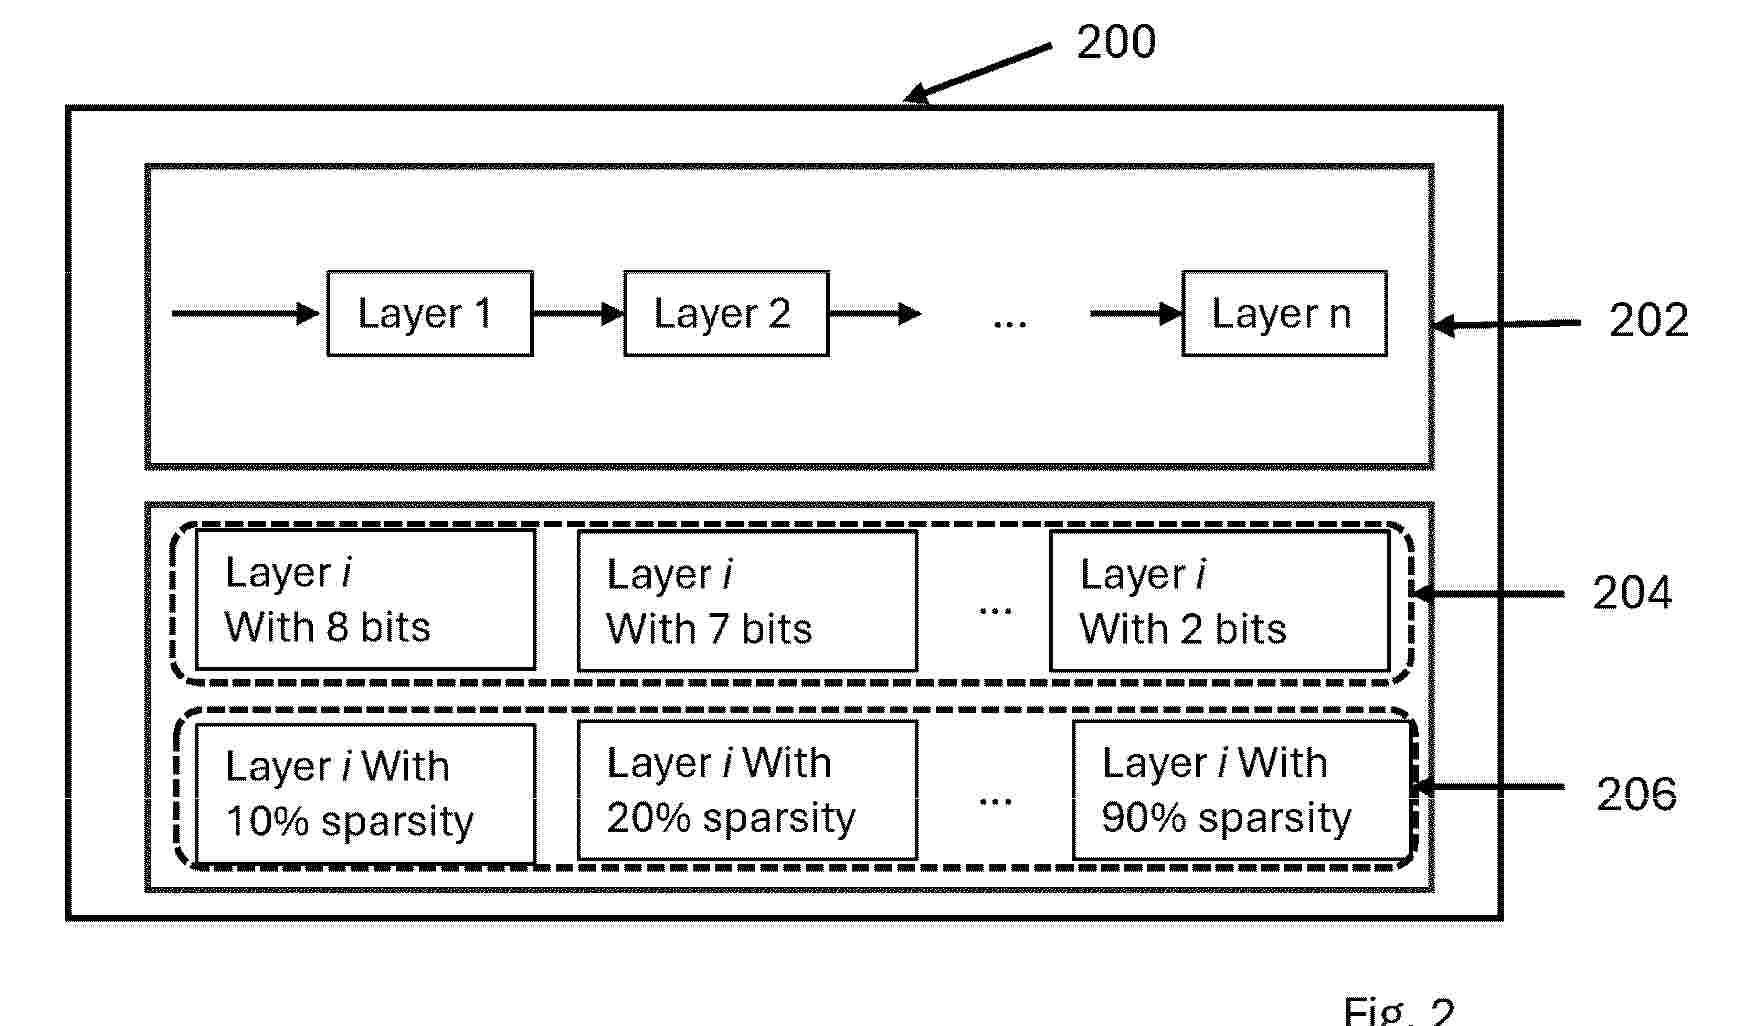
0001 The present disclosure relates to a computing system and a method for calculating and using a compression policy of a neural network, comprising the steps of: selecting a plurality of compression methods, a plurality of compression ratios associated with the plurality of compression methods, and a target global compression ratio for the neural network; compressing each of the plurality of layers of the neural network according to each combination of the plurality of compression methods and of the plurality of compression ratios; for each of the plurality of layers, calculating a value for a loss function and a value for a cost function; calculating the compression policy for the target global compression ratio using the value for the loss function and the value for the cost function for each of the plurality of layers, and compressing the neural network according to the compression policy.
Resumen de: EP4835834A1
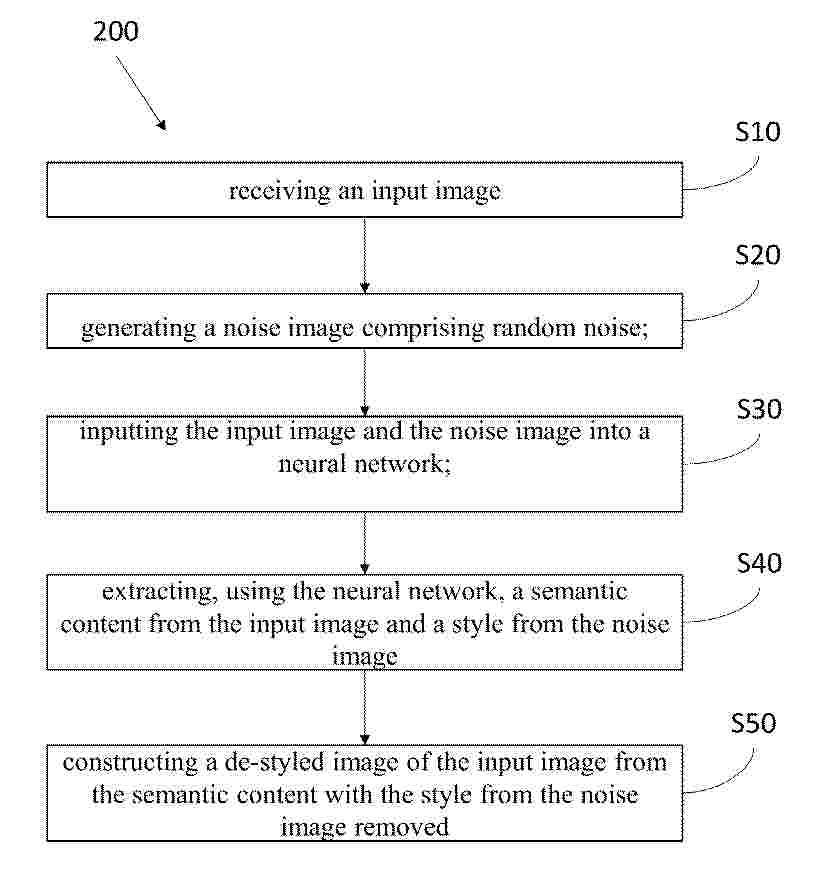
A computer-implemented method for removing an adversarial patch from an image, comprising, receiving an input image, generating a noise image comprising random noise, inputting the input image and the noise image into a neural network;, extracting, using the neural network, a semantic content from the input image and a style from the noise image and constructing a de-styled image of the input image from the semantic content with the style from the noise image removed.
Resumen de: EP4835835A1
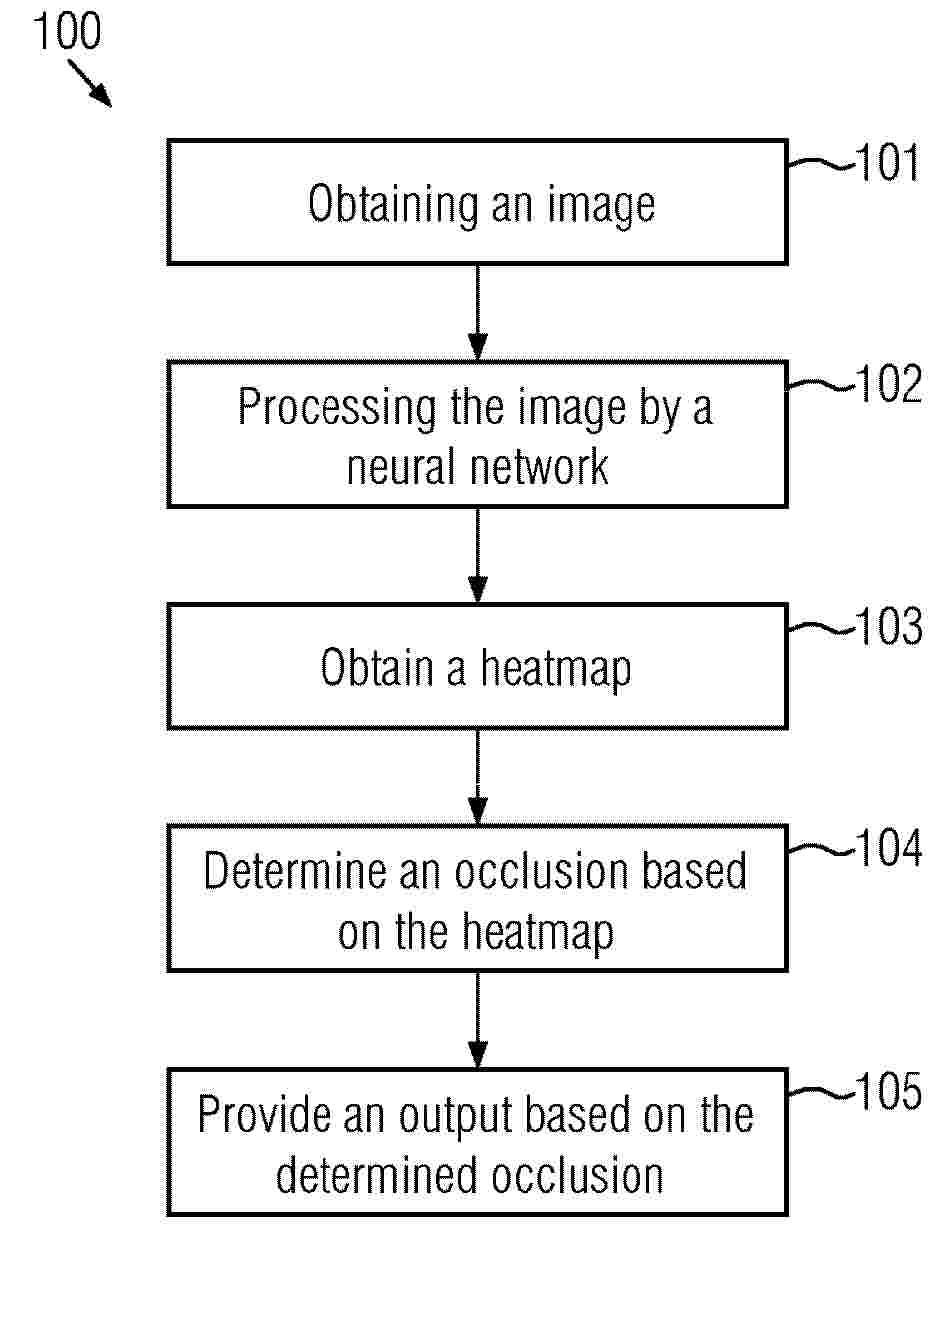
Computer-implemented method for determining an occlusion in an image, comprising the steps:Obtaining the image, wherein the image comprises a biometric feature;Processing the image by a neural network, wherein the neural network comprises a plurality of convolutional layers;Obtaining a heatmap from an intermediate output of the neural network, wherein the intermediate output is obtained after one of the convolutional layers;Determining an occlusion based on the heatmap;Providing an output based on the determined occlusion, wherein if the output indicates that at least part of the biometric feature is occluded, rejecting the image as invalid and/or providing information to a user that the image comprises occlusion.
Resumen de: EP4835907A2
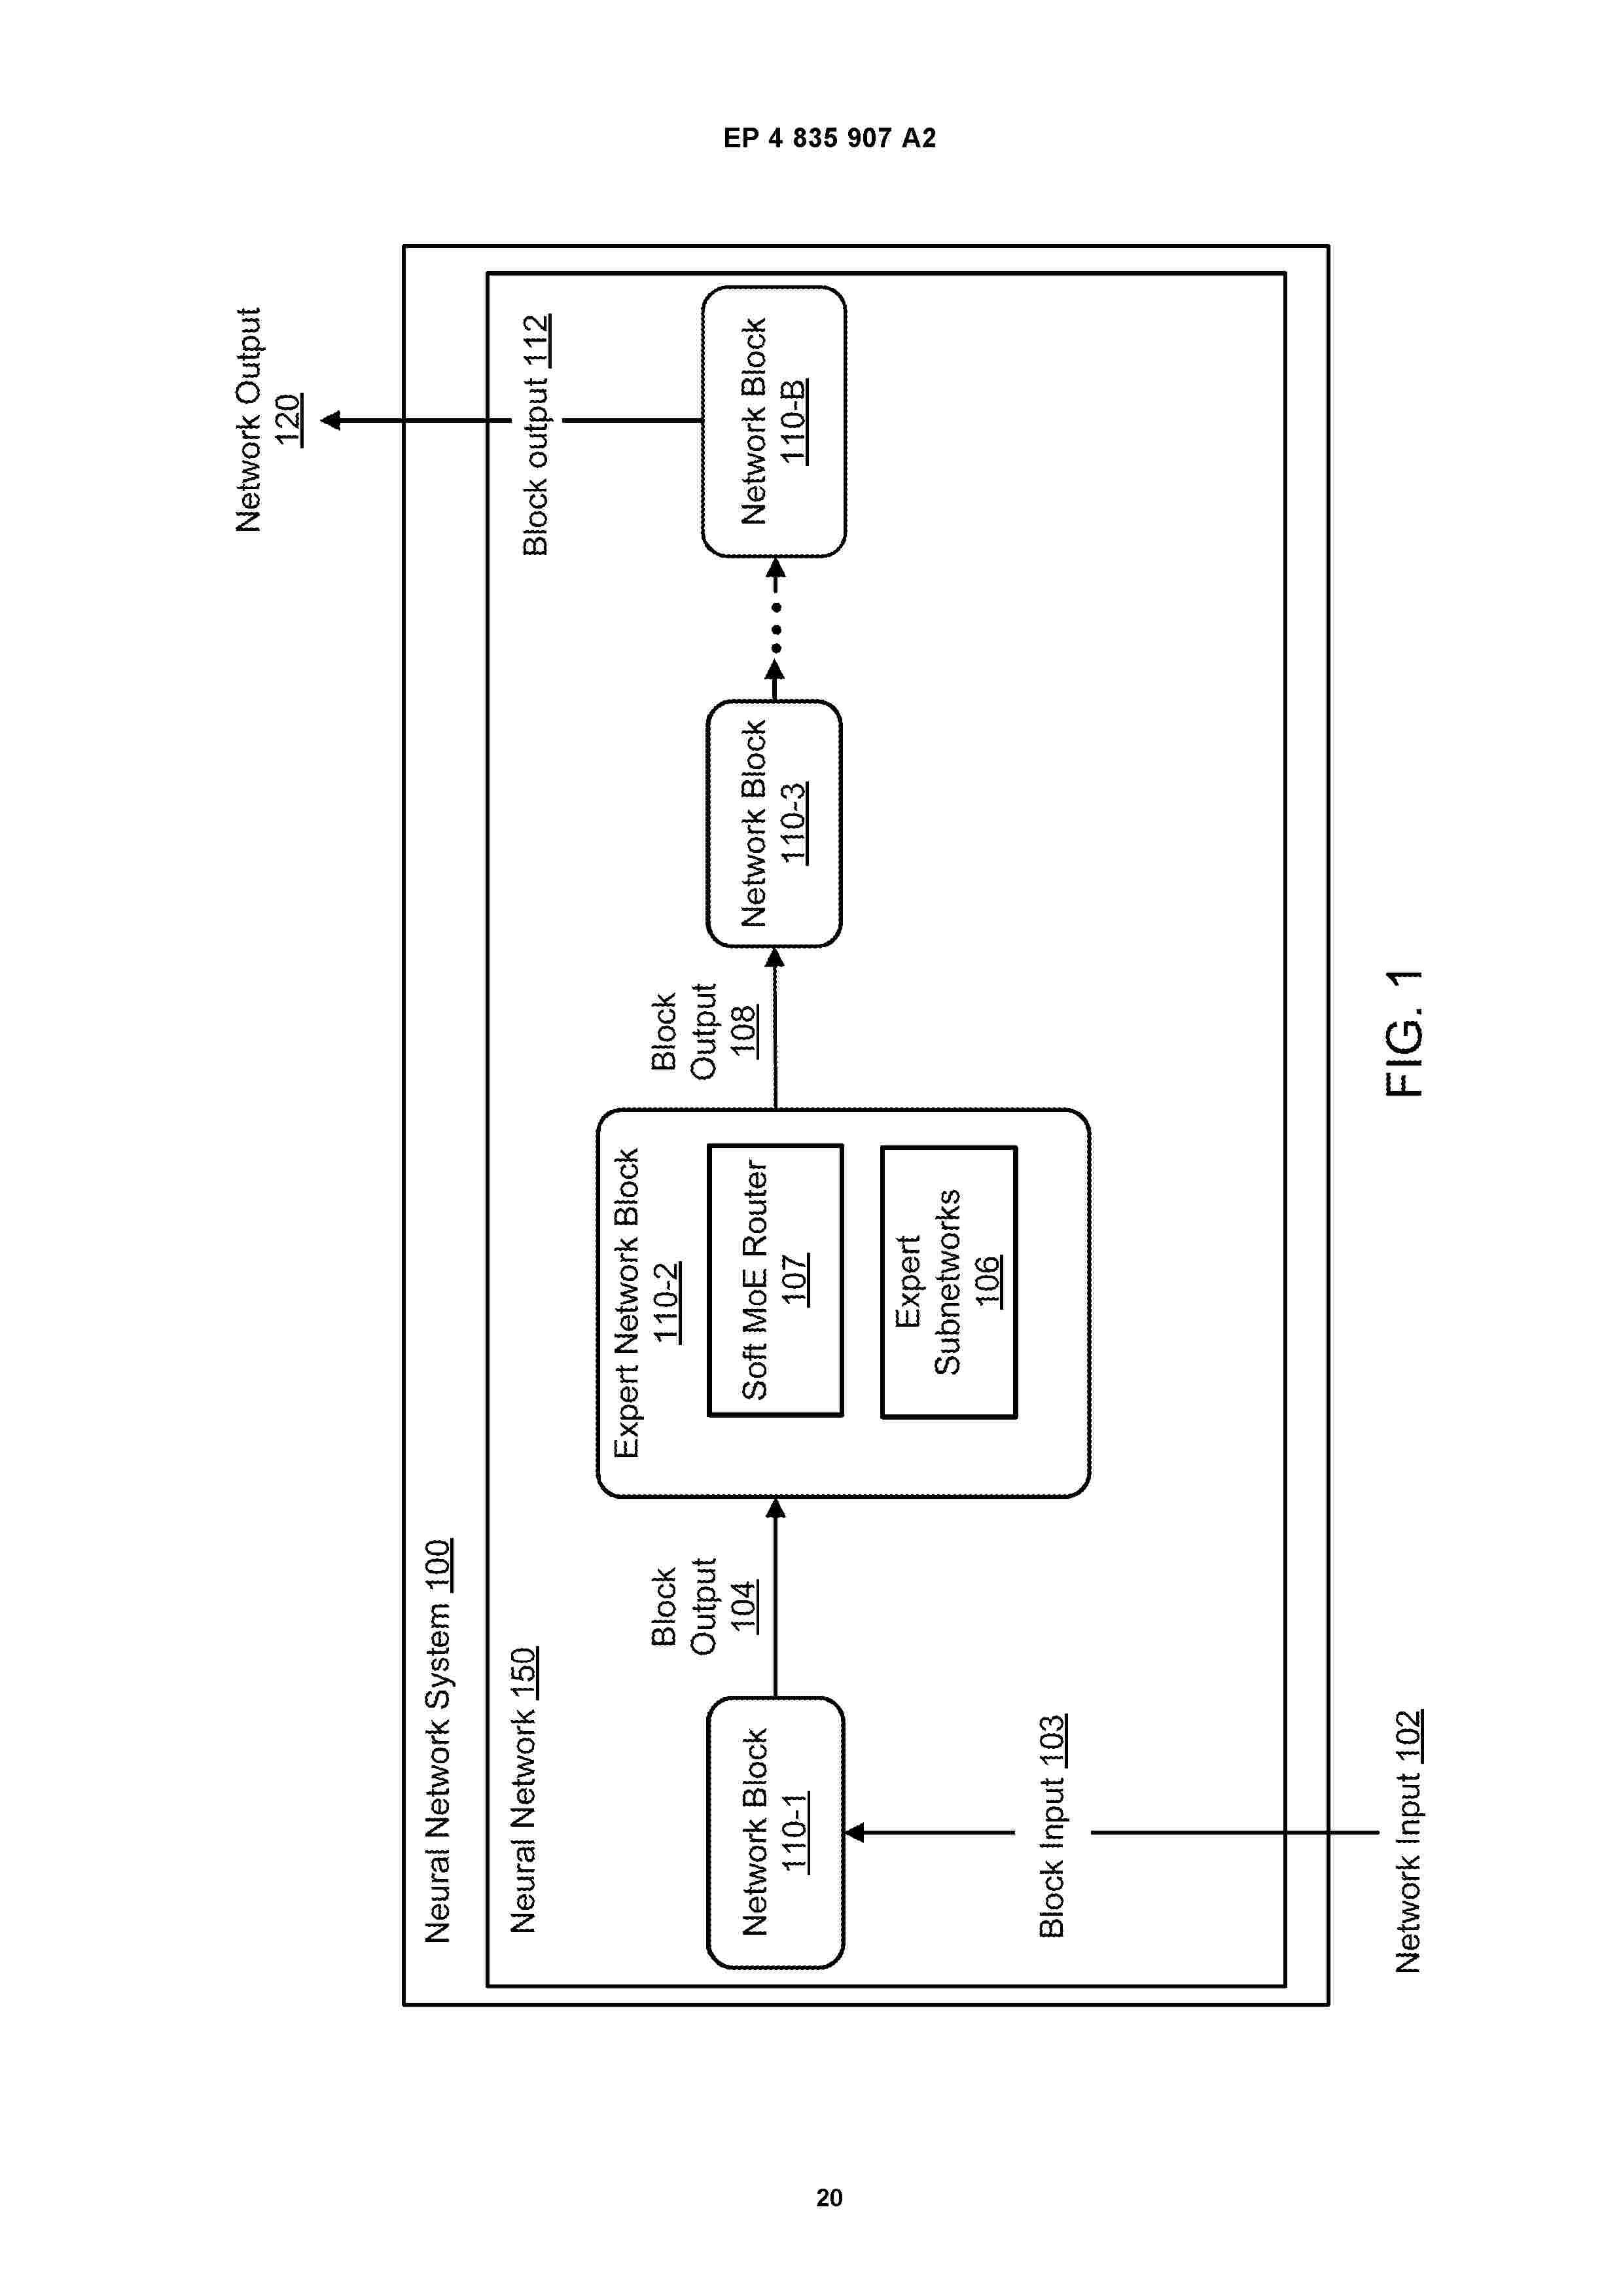
0001 A system including a neural network configured to process a network input and to generate a network output is described. The neural network includes a sequence of one or more network blocks, e.g., one or more expert network blocks. At least one expert network block is configured to perform operations including: obtaining a block input representing an intermediate representation of the network input and comprising multiple input tokens; generating a plurality of input slots from the input tokens; for each of multiple expert subnetworks of the at least one expert network block: processing a respective subset of the plurality of input slots using the expert subnetwork to generate, for each input slot in the respective subset, a respective output slot for the input slot; updating the plurality of input tokens using the output slots to generate multiple output tokens; and generating a block output from at least the output tokens.
Resumen de: WO2025141279A1
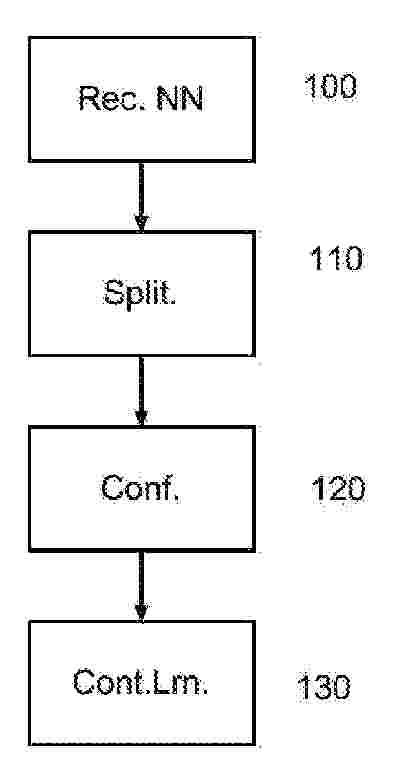
The invention relates to a continuous learning method for a facial comparison biometric neural network, wherein the method comprises the following operations: a) receiving an already-trained facial comparison biometric neural network; b) separating the neural network from operation a) into a characterisation block and an output block; c) separating the characterisation block into an extraction block and an adaptation block; d) receiving two separate sets of training data formatted as the inputs to the neural network from operation a); e) supplying the second set to the extraction block (230) and deriving a third set therefrom; and f) training the neural network from operation a) by freezing the extraction block (230) and using the first set of data with the extraction block (230) in its frozen state, and using the third set by supplying it directly to the adaptation block.
Resumen de: EP4835746A1
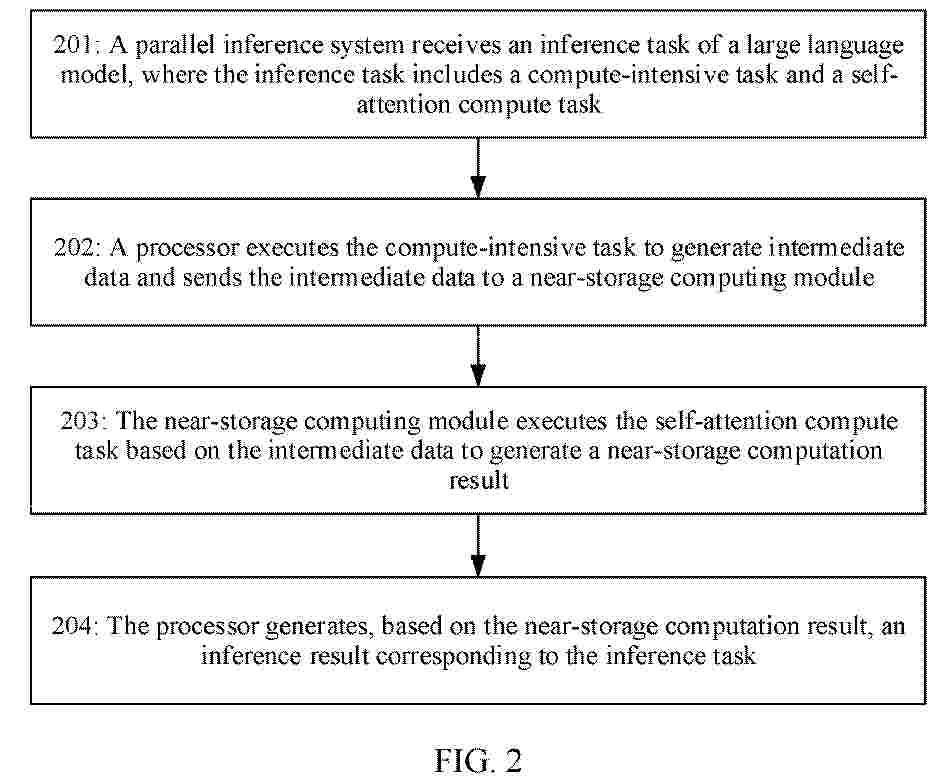
Embodiments of this application disclose a large language model inference method and apparatus to reduce bandwidth consumption of large language model inference. The method in embodiments of this application includes: A parallel inference system receives an inference task of a large language model, where the inference task includes a compute-intensive task and a self-attention compute task. A processor executes the compute-intensive task to generate intermediate data and sends the intermediate data to a near-storage computing module, where the compute-intensive task includes one or more of the following tasks of the large language model: a feed-forward neural network compute task, a projection task, and a layer normalization task. The near-storage computing module executes the self-attention compute task based on the intermediate data to generate a near-storage computation result. The processor generates, based on the near-storage computation result, an inference result corresponding to the inference task.
Resumen de: EP4835642A1
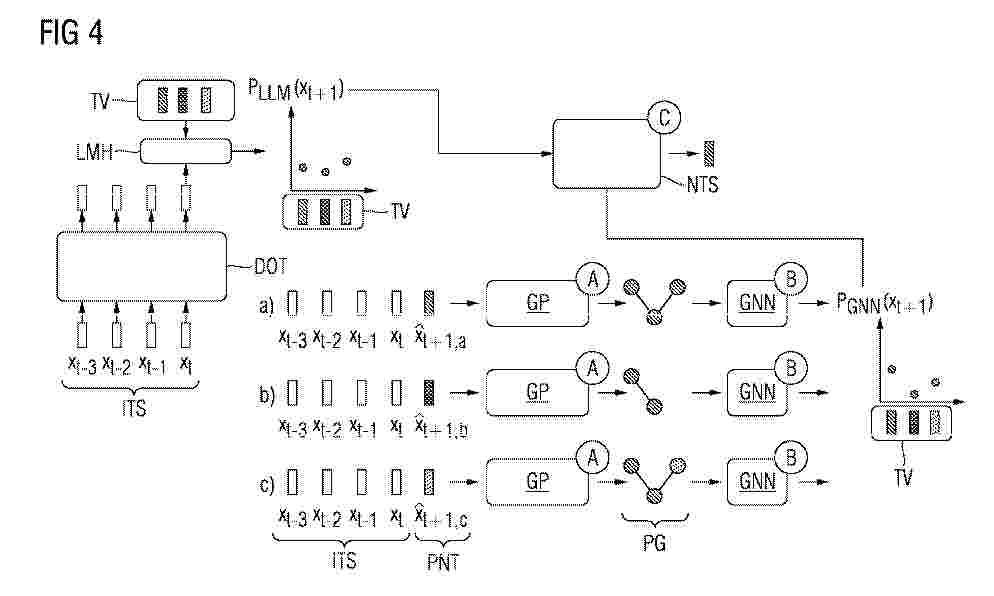
0001 The invention relates to generating a graph representing a technical system. A decoder iteratively constructs the graph as a graph token sequence in a structure-preserving graph serialization format, wherein each graph token represents a node of the graph or an aspect of the structure of the graph. In each iteration, the current state of the graph token sequence is used as an input token sequence (ITS). A decoder-only transformer (DOT) composed with a language model head (LMH) receives a textual prompt describing the technical system and the input token sequence (ITS) as input and computes a probability distribution over a token vocabulary (TV), which is a set of possible next tokens (PNT) that could be appended to the input token sequence (ITS). A graph parser (GP) receives partial token sequences as input and builds a partial graph (PG) for each partial token sequence. Each partial token sequence consists of the input token sequence (ITS) followed by one of the possible next tokens (PNT). A discriminator graph neural network (GNN) determines for each partial graph (PG) a probability score indicating how likely the partial graph (PG) is to occur in the real world. Finally, a next token sampler (NTS) receives as input the probability distribution and the probability scores, samples a next graph token from the token vocabulary (TV), and adds the next graph token to the graph token sequence. This multi-modal ensemble decoder outperforms traditional generation approaches
Resumen de: EP4836429A2
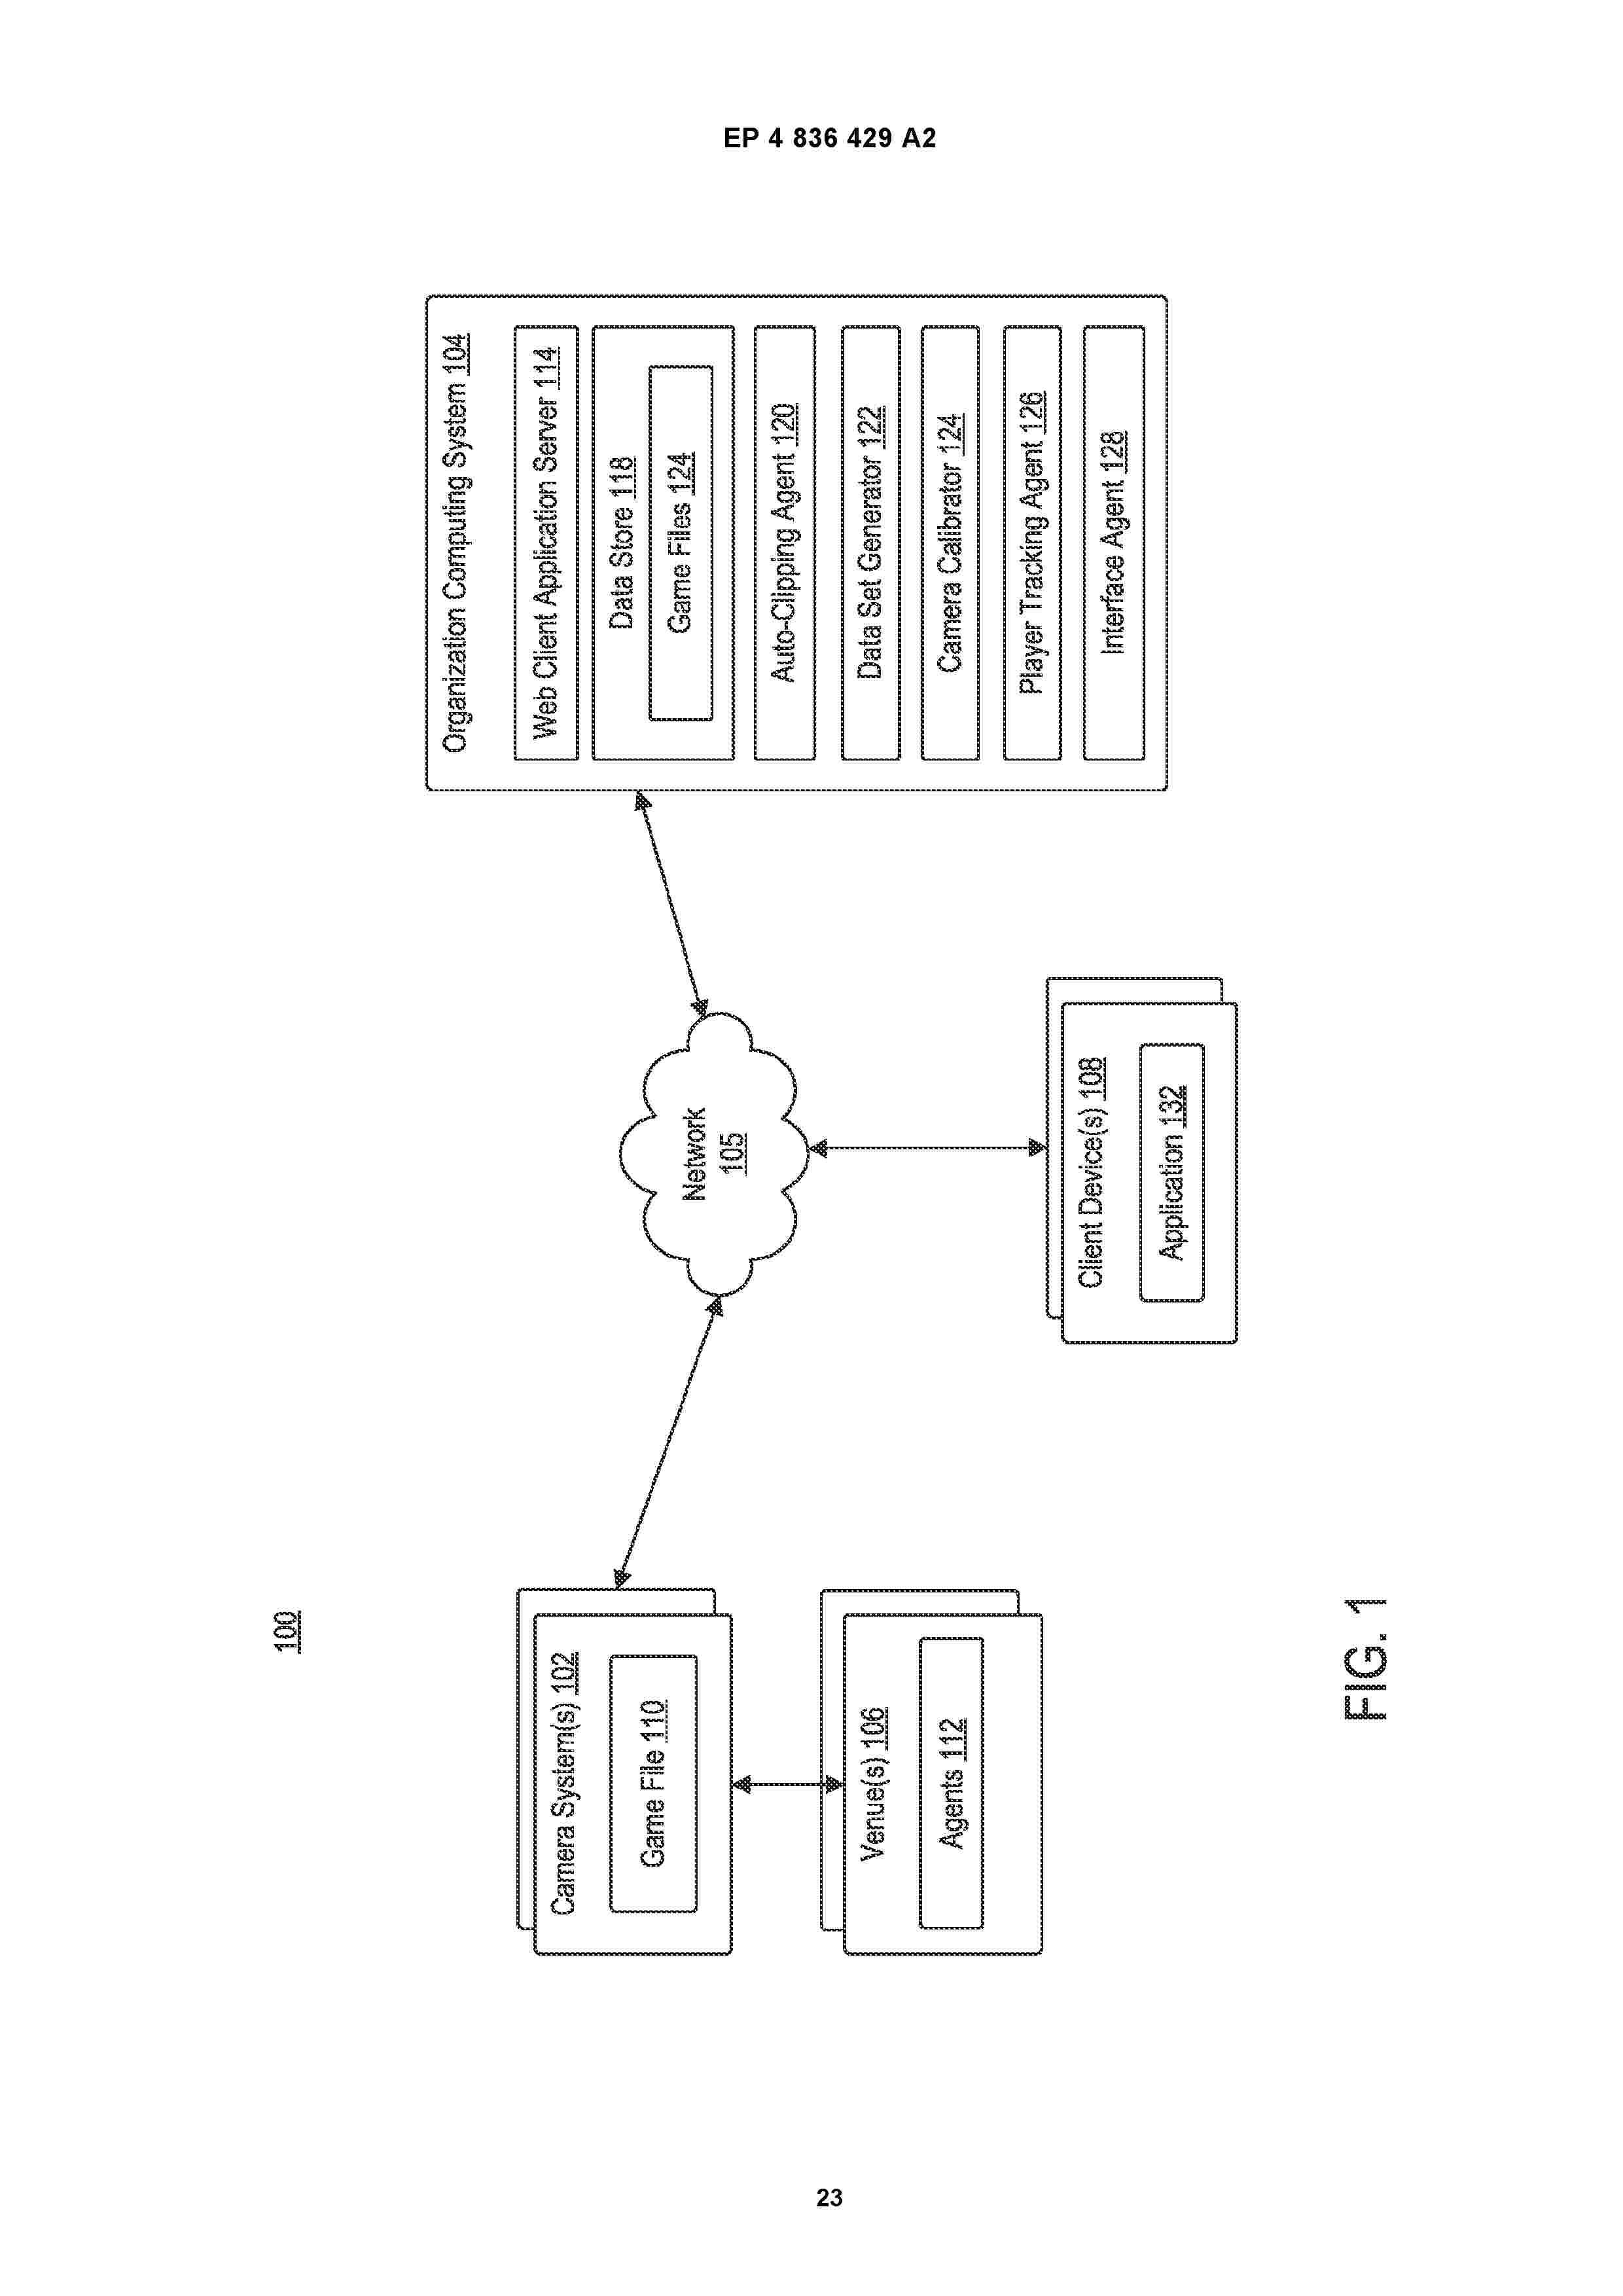
0001 A system and method of calibrating moving cameras capturing a sporting event is disclosed herein. A computing system retrieves a broadcast video feed for a sporting event. The broadcast video feed includes a plurality of video frames. The computing system labels, via a neural network, components of a playing surface captured in each video frame. The computing system matches a subset of labeled video frames to a set of templates with various camera perspectives. The computing system fits a playing surface model to the set of labeled video frames that were matched to the set of templates. The computing system identifies camera motion in each video frame using an optical flow model. The computing system generates a homography matrix for each video frame based on the fitted playing surface model and camera motion. The computing system calibrates each camera based on the homography matrix generated for each video frame.
Resumen de: EP4835737A2
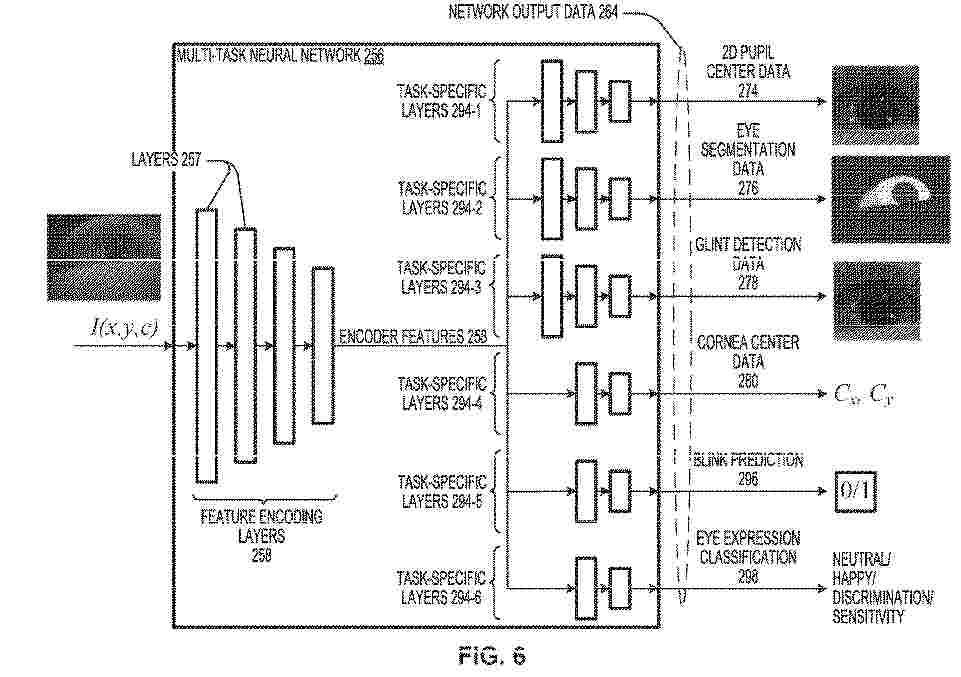
Techniques related to the computation of gaze vectors of users of wearable devices are disclosed. A neural network may be trained through first and second training steps. The neural network may include a set of feature encoding layers and a plurality of sets of task-specific layers that each operate on an output of the set of feature encoding layers. During the first training step, a first image of a first eye may be provided to the neural network, eye segmentation data may be generated using the neural network, and the set of feature encoding layers may be trained. During the second training step, a second image of a second eye may be provided to the neural network, network output data may be generated using the neural network, and the plurality of sets of task-specific layers may be trained.
Resumen de: MA71290A1
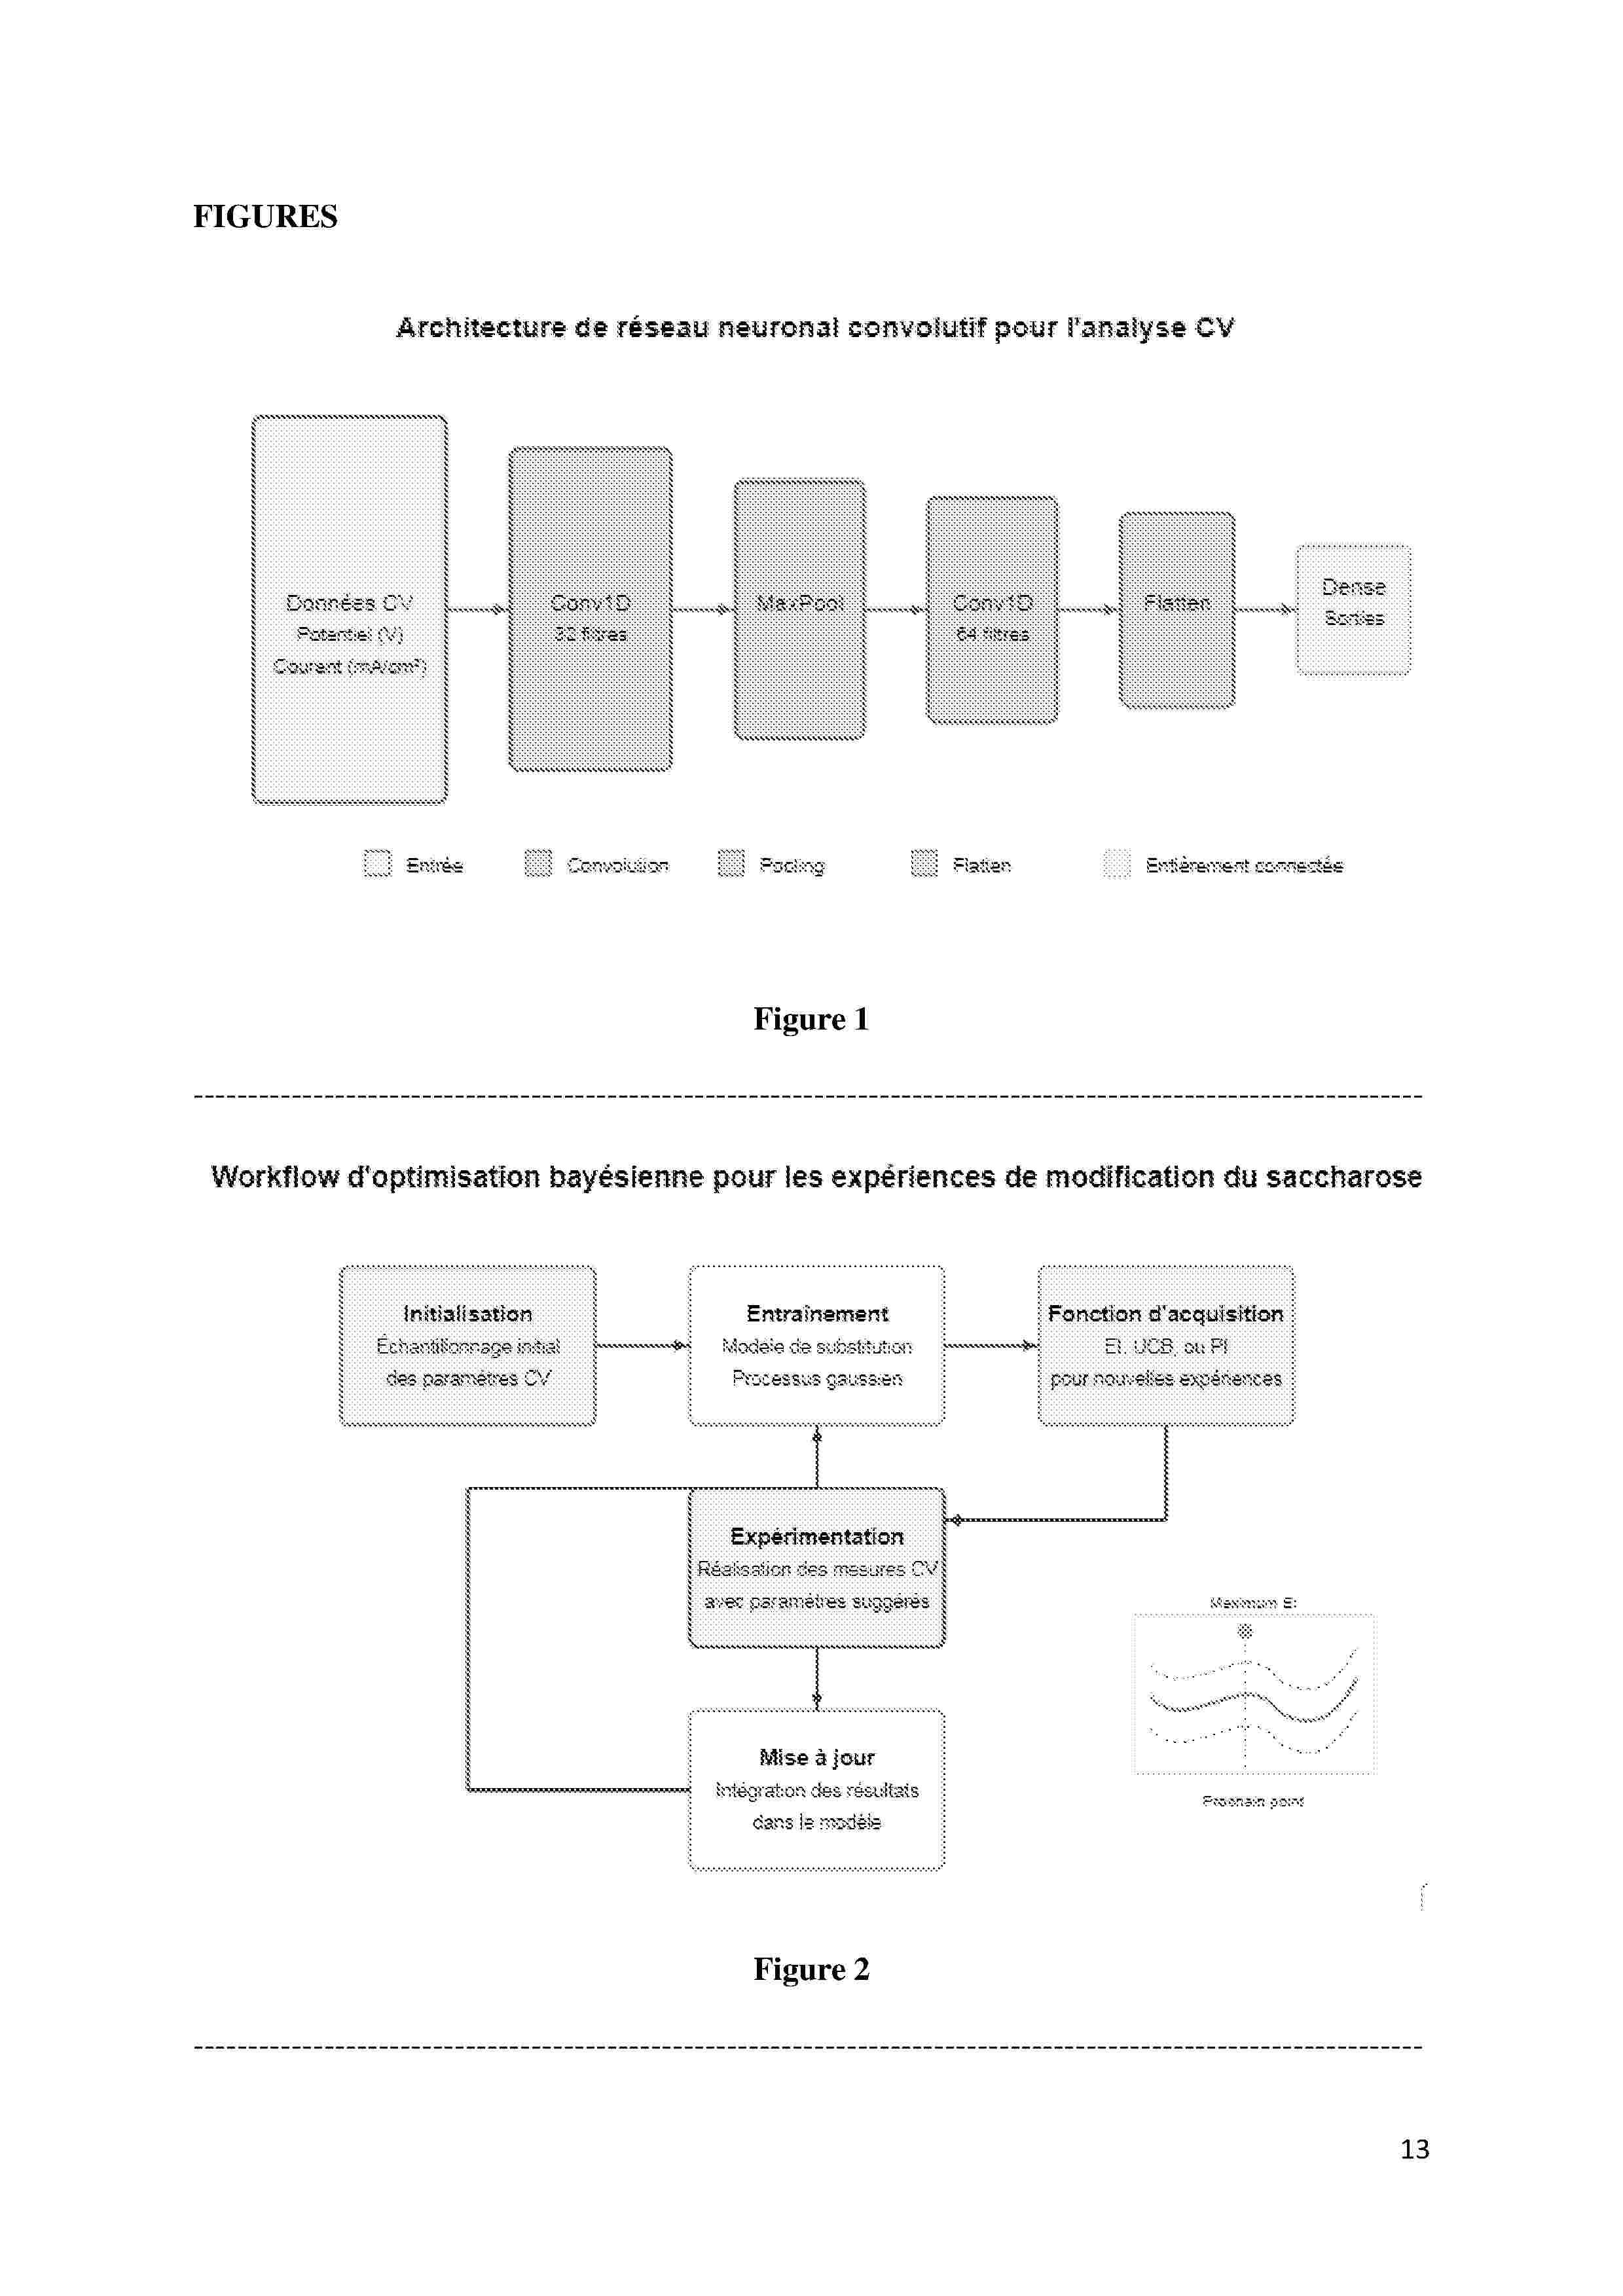
The invention relates to a method for applying artificial intelligence to the analysis and optimization of the electrochemical modification of sucrose, with the aim of developing sugar alternatives with improved health-related properties. The method comprises the use of convolutional neural networks to analyze cyclic voltammetry data, Bayesian optimization to determine optimal experimental conditions, and deep generative models to design sucrose derivatives. In particular, the invention makes it possible to identify the synergistic effects of Mg²⁺ and Cr²⁺ metal ions as catalysts in the controlled transformation of sucrose using titanium dioxide-modified carbon paste electrodes.
Resumen de: KR20260157268A
본 발명은 객체 검출 장치에 의해 수행되는 방법에 있어서, 사용자 단말로부터 데이터를 로드하는 단계, 로드된 데이터를 전처리 하는 단계, 전처리 된 데이터를 기초로, 딥 러닝 알고리즘을 학습하는 단계, 학습된 딥 러닝 알고리즘으로 입력 데이터를 입력하는 단계, 딥 러닝 알고리즘에서 출력된 출력 데이터를 기초로, 사용자 단말로 제공하는 객체 검출에 관한 제공 데이터를 생성하는 단계, 및 제공 데이터를 사용자 단말로 제공하는 단계를 포함하며, 상기 딥 러닝 알고리즘은 NAS-FPN (Neural Architecture Search - Feature Pyramid Network)과 Cascade RPN을 하나의 네트워크로 통합한 것인 객체 검출을 위한 신경망 구조 탐색 기반 다단계 후보 영역 제안 방법 및 장치일 수 있다.
Nº publicación: US20260340979A1 29/10/2026
Solicitante:
INTEL CORP [US]
Intel Corporation
Resumen de: US20260340979A1
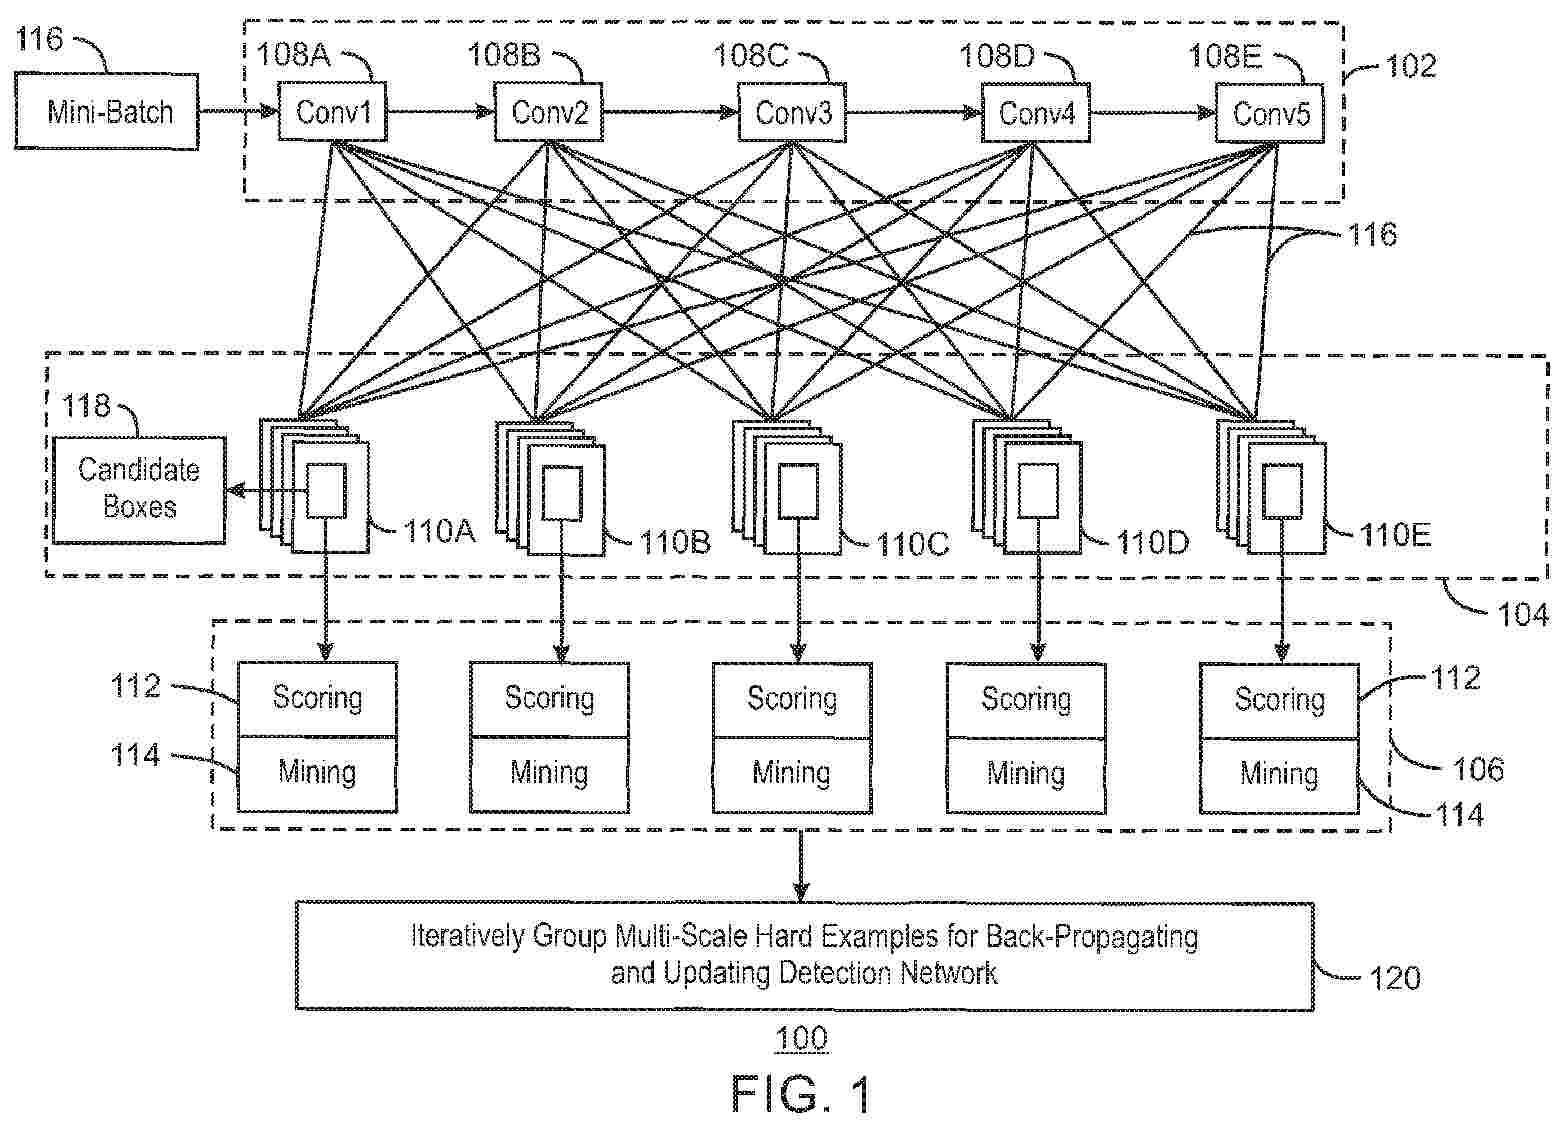
An example apparatus for mining multi-scale hard examples includes a convolutional neural network to receive a mini-batch of sample candidates and generate basic feature maps. The apparatus also includes a feature extractor and combiner to generate concatenated feature maps based on the basic feature maps and extract the concatenated feature maps for each of a plurality of received candidate boxes. The apparatus further includes a sample scorer and miner to score the candidate samples with multi-task loss scores and select candidate samples with multi-task loss scores exceeding a threshold score.
 BOPI
 Sede Electrónica