Si deseas distinguir tus productos, servicios o ambos de los de otra empresa, es posible que necesites una marca o nombre comercial. Descubre qué son, en qué consiste su procedimiento de registro y qué implica.

Información sobre los plazos de presentación de solicitudes de transformación de marcas de la Unión Europea en marca nacional española. Más información


Si tienes un nuevo dispositivo, producto o procedimiento que resuelva un problema técnico o tenga una ventaja práctica, existen distintas formas de protegerlo en España y en otros países. Descubre cómo hacerlo.

¿Tu innovación reside en la estética, la ornamentación o la apariencia de tu producto? Protégela mediante un diseño industrial. Descubre qué derechos confiere el registro y cómo realizar la tramitación.

Las indicaciones geográficas protegen el nombre de un producto originario de una zona geográfica, a la cual le debe una determinada calidad, reputación u otra característica. Descubre qué son, en qué consiste su procedimiento de registro y qué beneficios conceden.

Las patentes publicadas en todo el mundo son una valiosa fuente de información científica, técnica y comercial.

Si eres emprendedor/a o una empresa y quieres potenciar y mejorar la rentabilidad de tu negocio protegiendo de forma adecuada los activos intangibles de tu organización, en este espacio encontrarás lo necesario.


 175
resultados
 Última actualización
22/10/2026 [09:51:00]


 Resultados 50 a 75 de 175

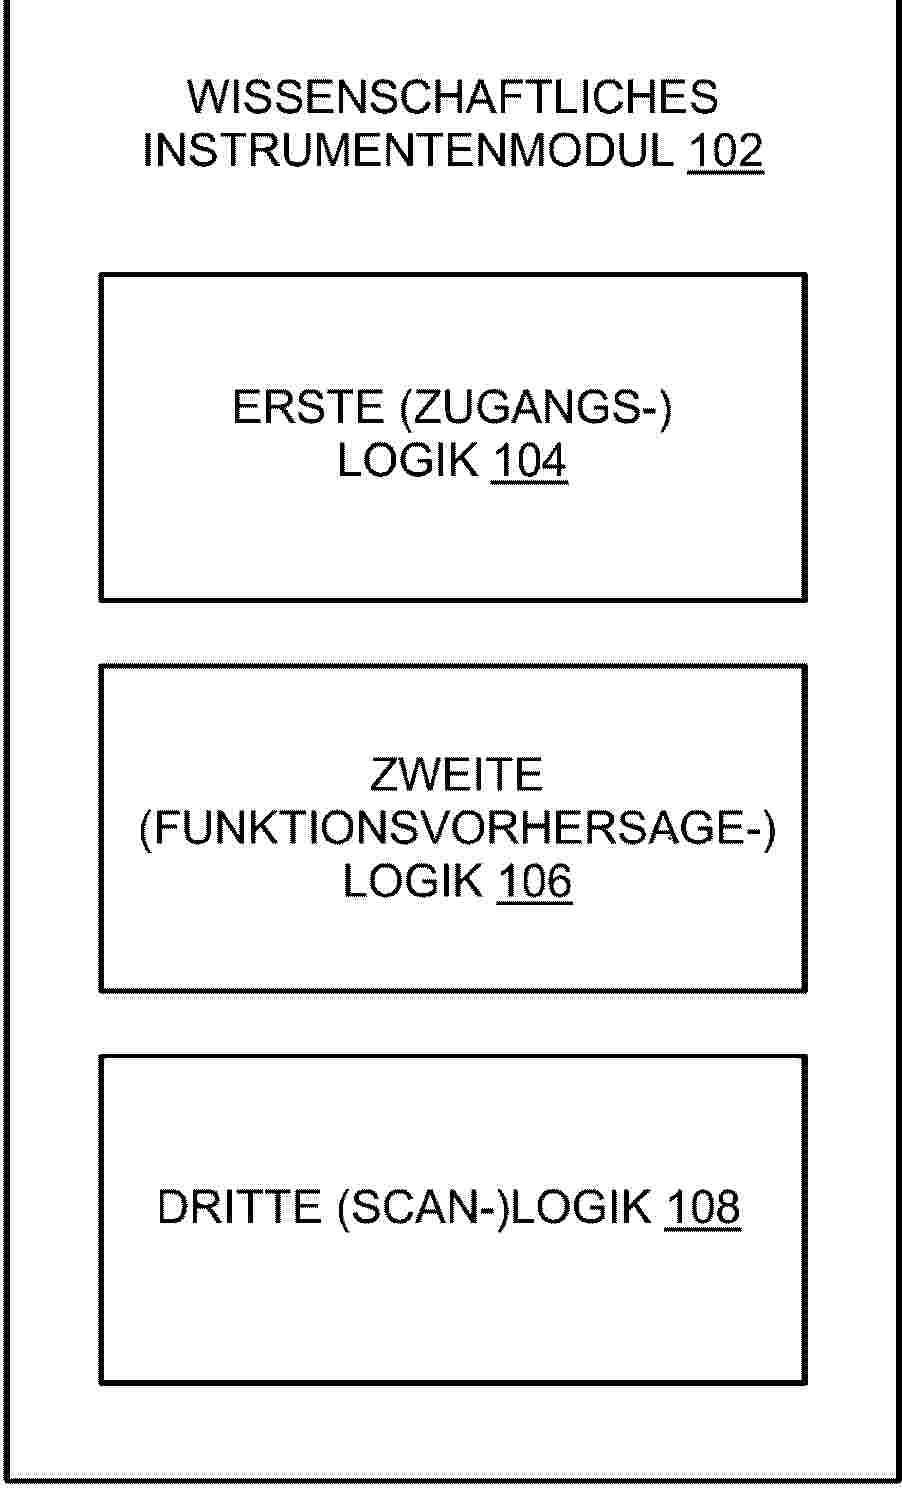
Resumen de: GB2705175A
A method for facilitating machine learning prediction of ion trap filling functions is disclosed. The method comprises causing a mass analyser to perform a scan using an injection or accumulation time. The injection time is correlated to a requested or desired ion population size by an ion trap filling function, which may be non-linear. The coefficients of the ion trap filling function are predicted by a machine learning model based on current operational parameters of the mass analyser, e.g. the scan range or width of the mass analyser, pass range or width of an ion trap of the mass analyser, or the number of ion guide injections. The injection time may be scaled using a pre-scan ion flux estimate or an ion species distribution. The machine learning model may be trained in a supervised fashion and updated via backpropagation based on an error between the actual ion population size and the requested ion population size. The machine learning model may be a random forest regressor or a deep learning neural network. A system and a computer program are also claimed. Figure 15

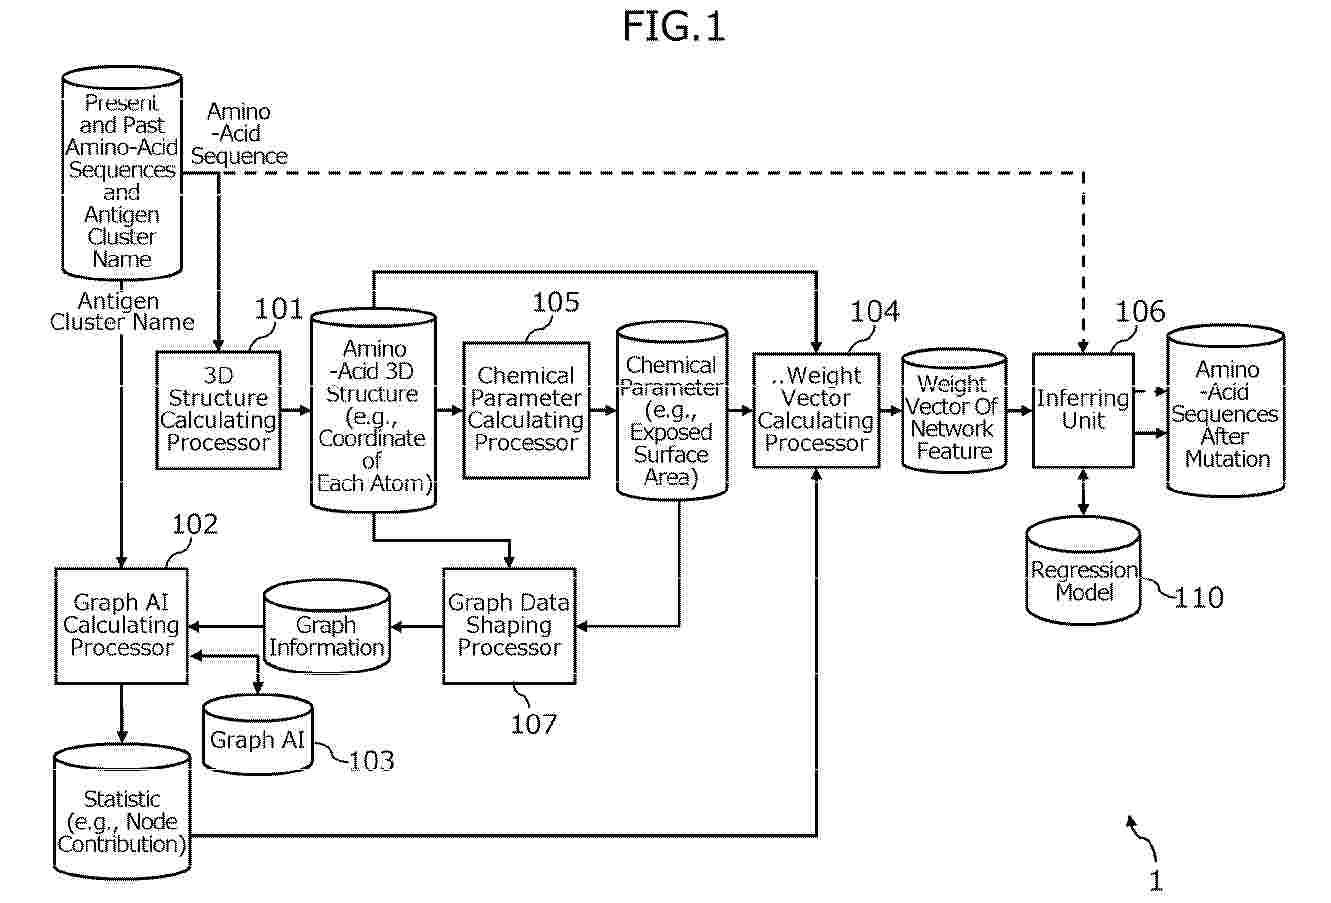
Resumen de: EP4819147A1
An information processing program causes a computer to execute a process including: determining a weight of an input feature in a regression model, the regression model predicting an amino-acid sequence of a virus after mutation using an amino-acid sequence of the virus as the input feature, the determining being based on a first feature related to a three-dimensional (3D) structure of a protein of the virus and a second feature related to a contribution to prediction of a machine learning model, the contribution being obtained based on the first feature.
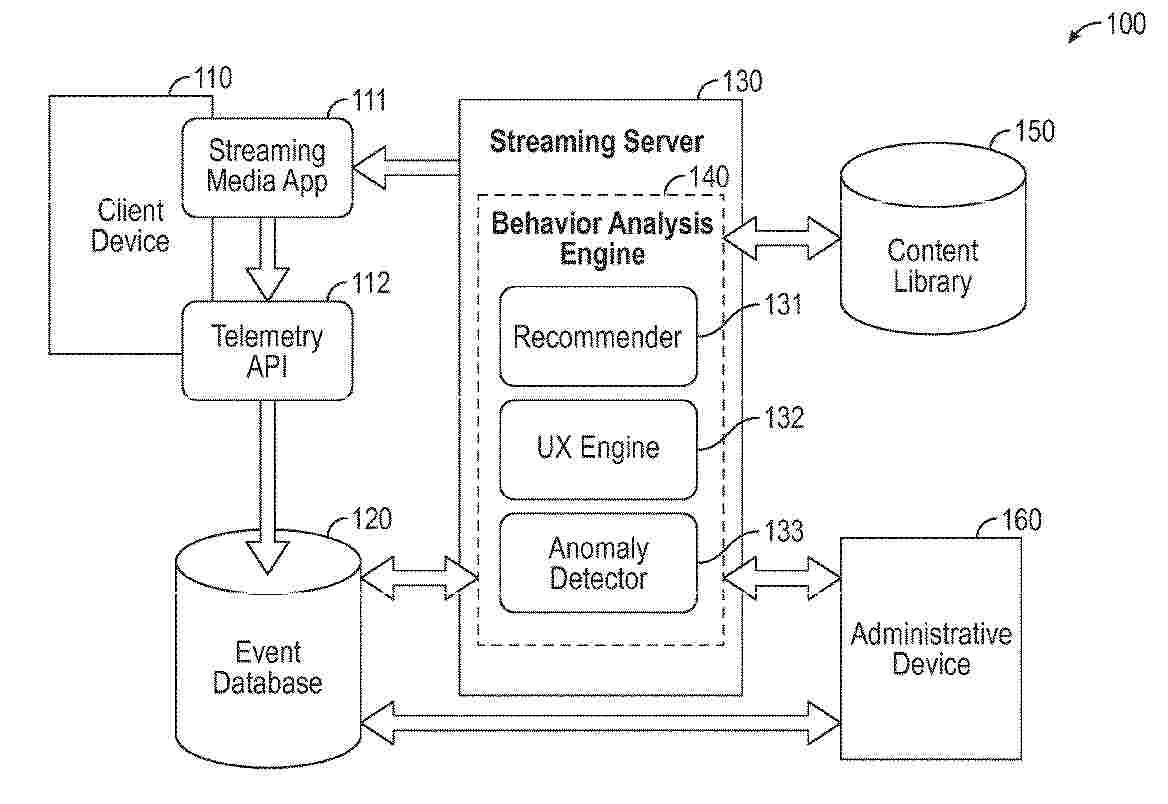
Resumen de: EP4819625A2
Systems, methods and articles of manufacture for are provided for analyzing user behavior in real time by ingesting telemetry data related to a streaming media application; feeding the telemetry data to a machine learning model (MLM) that produces a User Experience (UX) command based on the telemetry data and prior telemetry data received from the content streaming application; selecting content items to provide to the client device based on the telemetry data; determining, based on the telemetry data, whether the client device has sufficient free resources to receive the UX command and the content items in a current time window while providing a predefined level of service; when client device has sufficient free resources to receive the UX command and the content items, encapsulating the UX command with the content items in a content stream; and transmitting the content stream to the client device.
Resumen de: EP4818906A1
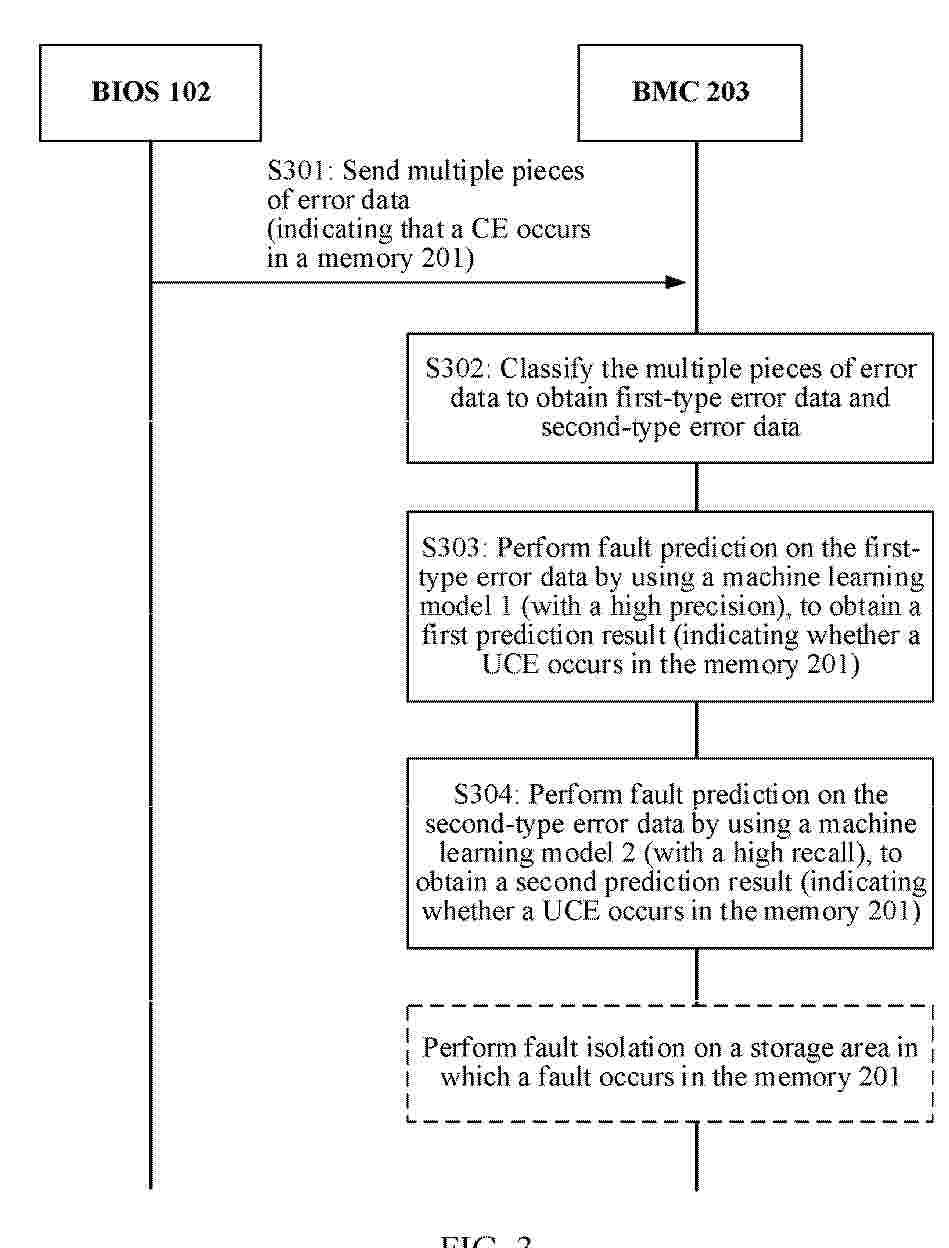
0001 A fault prediction method and apparatus, and a related device are provided, relating to the field of computer technologies. Multiple pieces of error data are obtained, where each piece of error data indicates that a CE occurs in a storage medium. The multiple pieces of error data are classified. Fault prediction is performed, by using a first machine learning model, on first-type error data obtained through classification, and fault prediction is performed, by using a second machine learning model, on second-type error data obtained through classification, to obtain corresponding prediction results indicating whether a UCE occurs in the storage medium. A precision of the first machine learning model in predicting a UCE is greater than a first threshold, and a recall of predicting of the second machine learning model in predicting a UCE is greater than a second threshold. In this way, fault prediction is performed on different types of error data by using the machine learning model with a high prediction precision and the machine learning model with a high recall, so that both a precision and a recall of fault prediction can be considered, thereby effectively improving an overall prediction effect for the multiple pieces of error data.
Resumen de: EP4818981A2
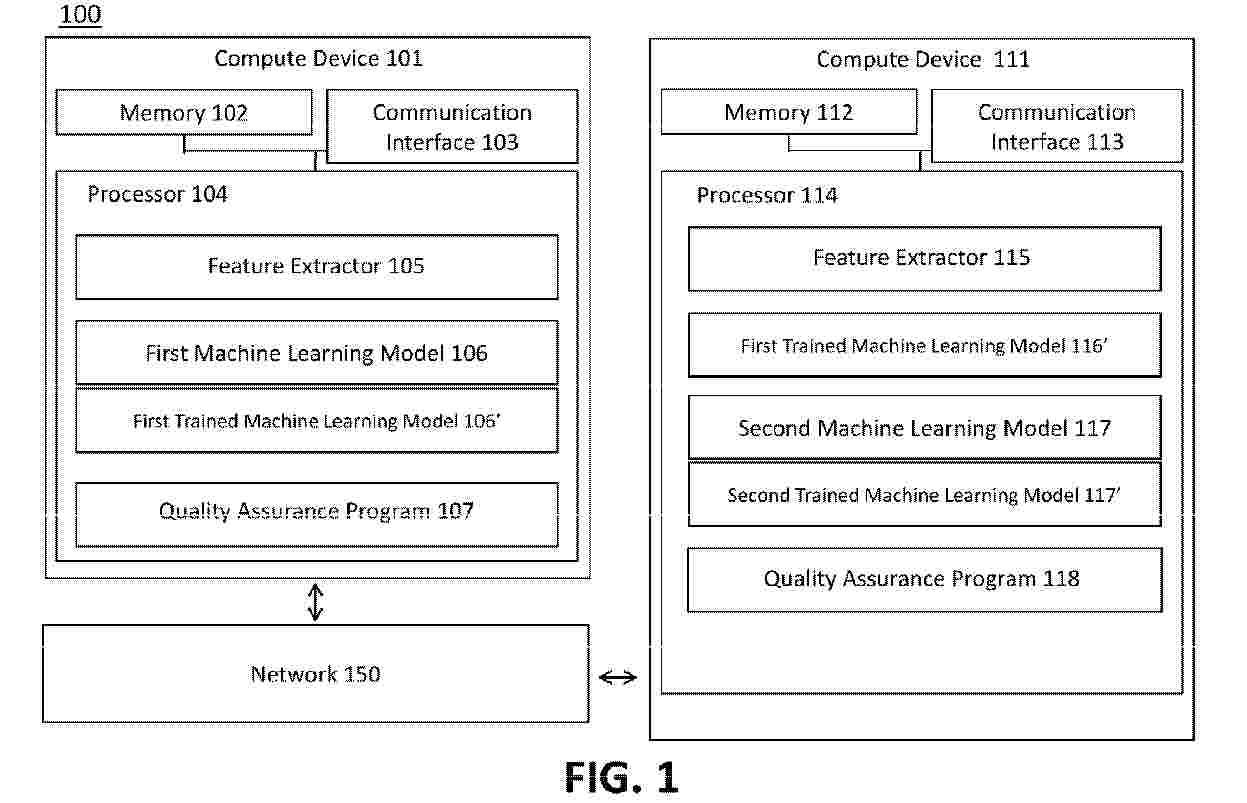
A non-transitory processor-readable medium stores instructions to be executed by a processor. The instructions cause the processor to receive a first trained machine learning model that generates a transcription based on a document. The instructions cause the processor to execute the first trained machine learning model and a second trained machine learning model to generate a refined transcription based on the transcription. The instructions cause the processor to execute a quality assurance program to generate a transcription score based on the document and the transcription. The instructions cause the processor to execute the quality assurance program to generate a refined transcription score based on the refined transcription and at least one of the document or the transcription. The at least one refined transcription score indicates an automation performance better than an automation performance for the at least one transcription score.
Resumen de: MX2026010422A
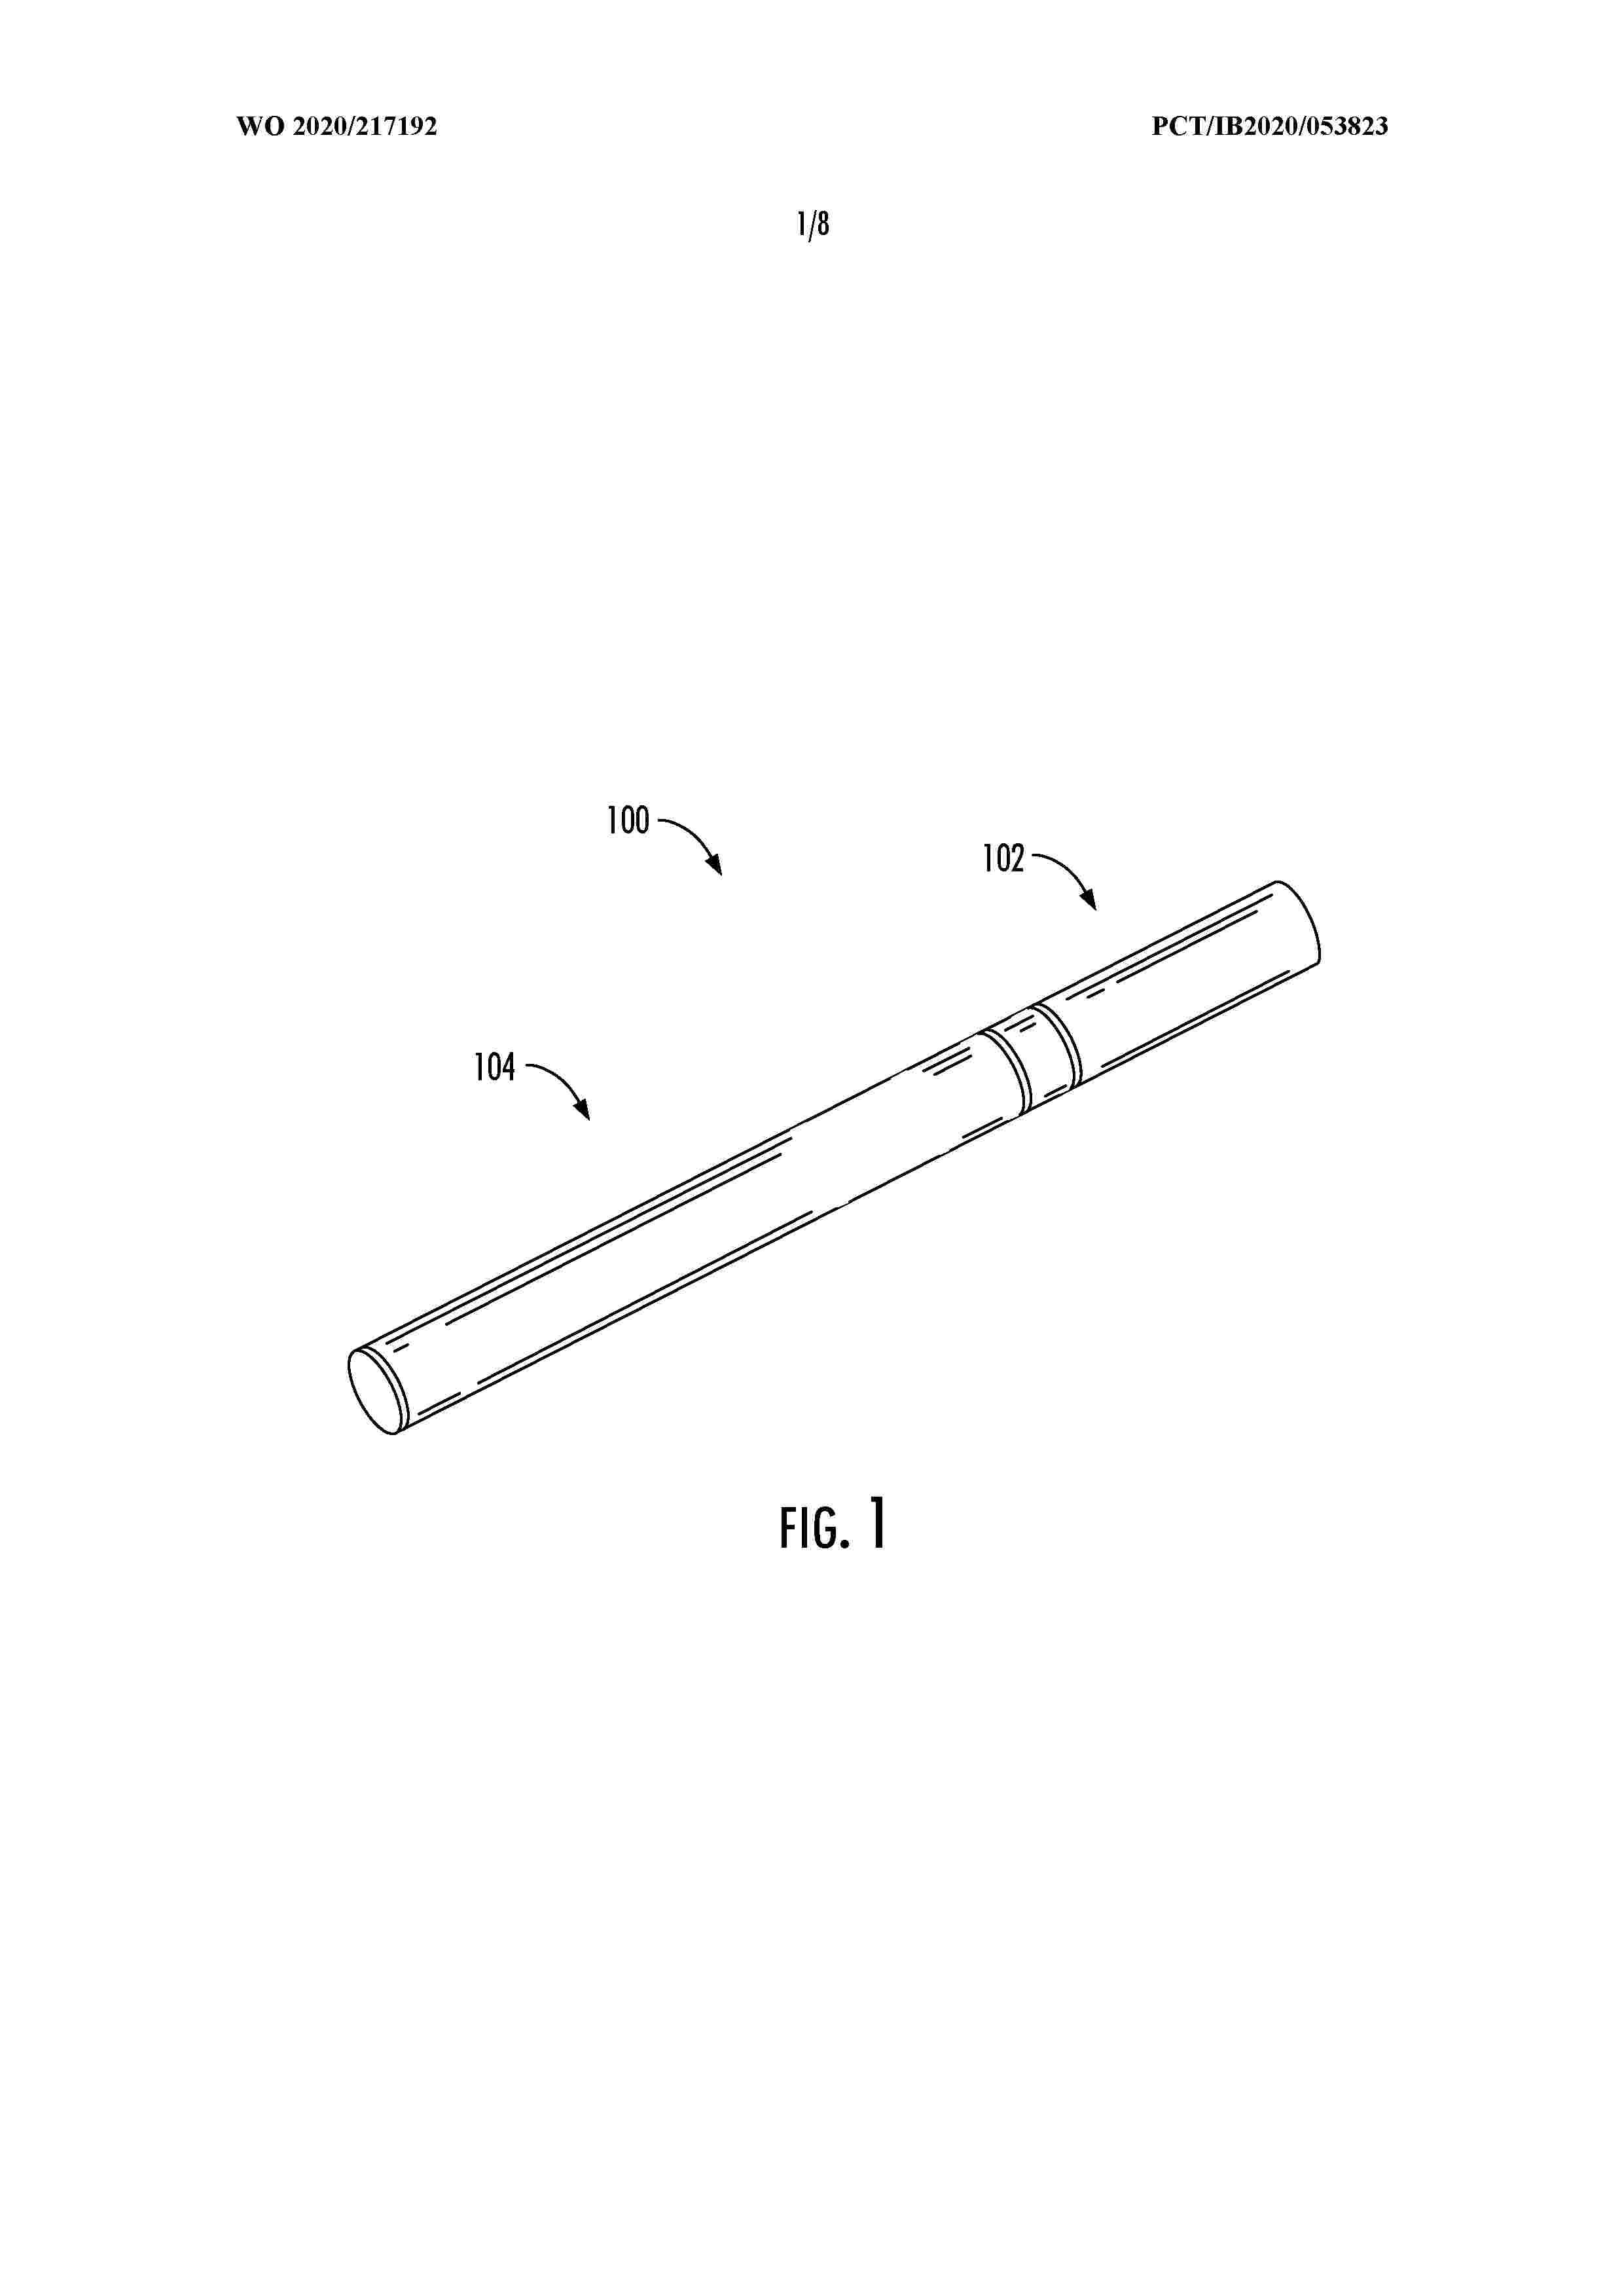
An aerosol delivery device is provided that includes sensor(s) to produce measurements of properties during use of the device, and processing circuitry to record data for a plurality of uses of the device, for each use of which the data includes the measurements of the properties. The processing circuitry is configured to build a machine learning model to predict a target variable, using a machine learning algorithm, at least one feature selected from the properties, and a training set produced from the measurements of the properties. The processing circuitry is configured to then deploy the machine learning model to predict the target variable, and control at least one functional element of the device based thereon. The device may also include a digital camera to capture an image of a face of an attempted user to enable facial recognition to alter a locked state of the device.
Resumen de: MX2026010538A
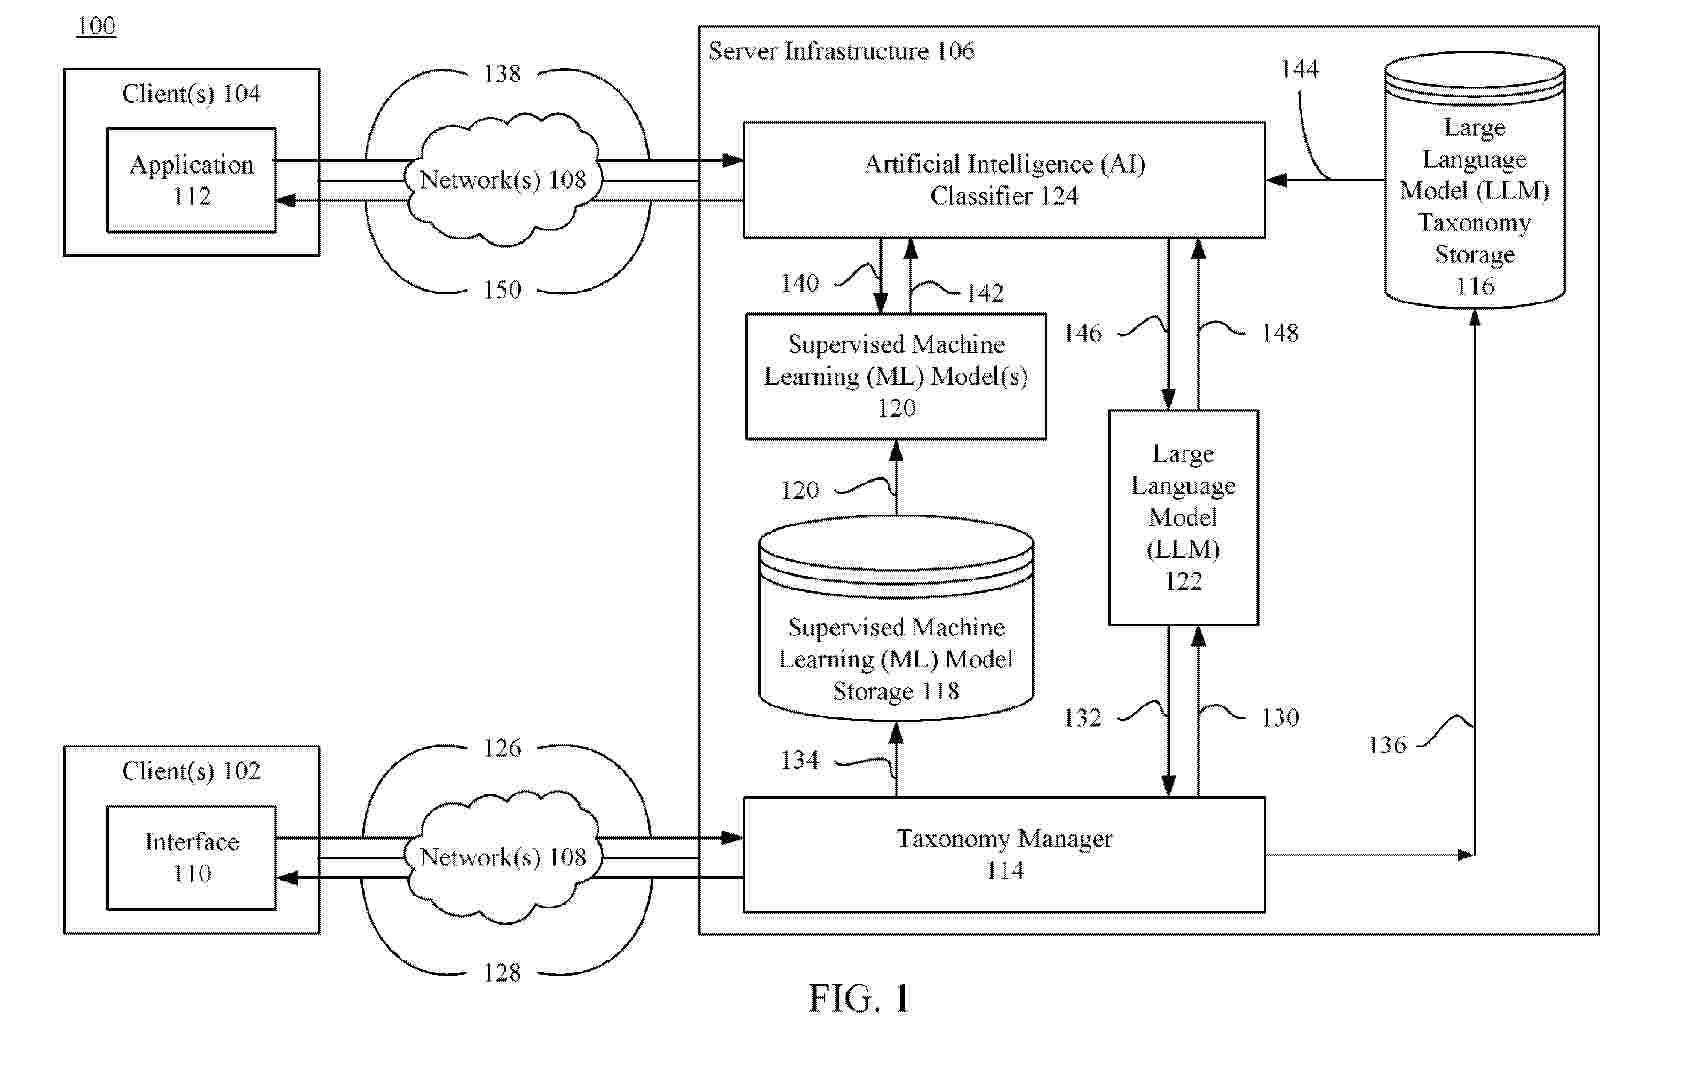
System, methods, apparatuses, and computer program products are disclosed for generating and using a hybrid artificial intelligence classifier for classifying input into one or more nodes of a taxonomy. Training data is received for at least a first portion of the taxonomy and used to train a supervised machine learning (ML) model to classify input into the first portion of the taxonomy having training data. A large language model (LLM) taxonomy is determined for at least a second portion of the taxonomy. The hybrid AI classifier classifies input based on a first classification obtained by providing the input to the supervised ML, and a second classification obtained by providing at least the input and the LLM taxonomy to a pre-trained LLM.
Resumen de: MX2026010476A
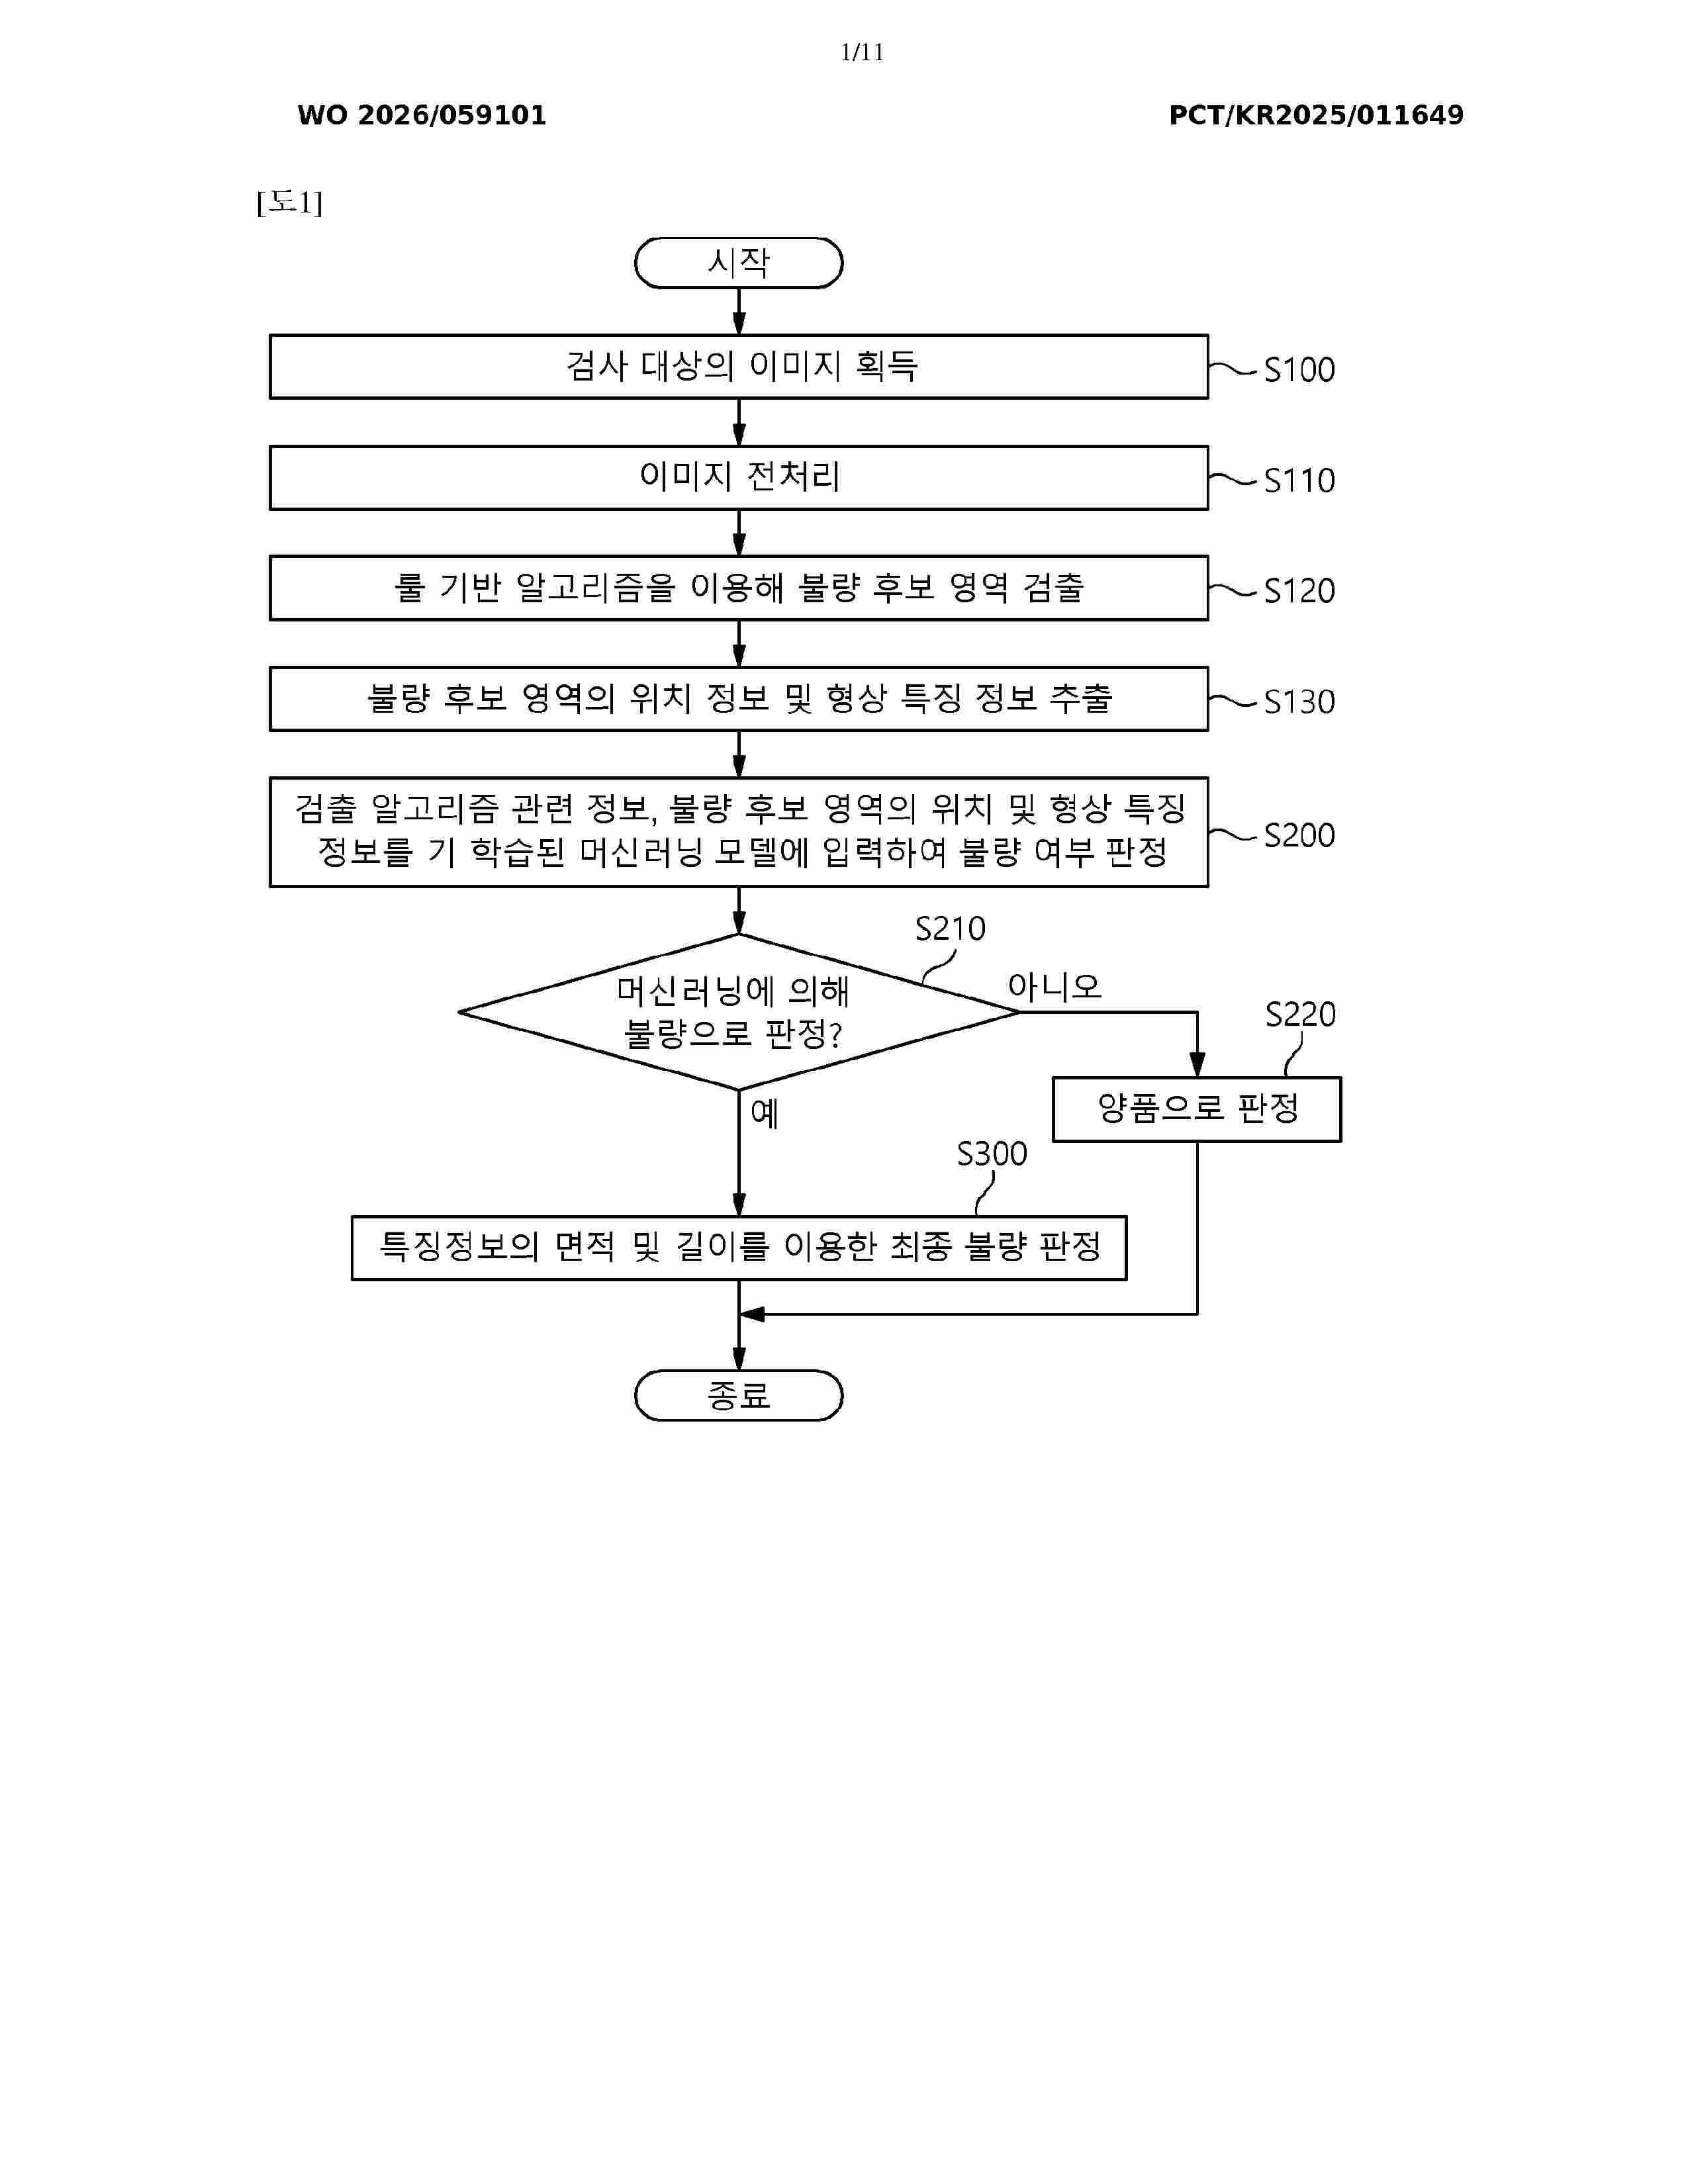
A method for inspecting a battery, according to an embodiment of the present invention, relates to a method for inspecting the quality of a battery in a manufacturing process, the method comprising the steps of: acquiring an image capturing at least a portion of the exterior of the battery to preprocess the image; detecting one or more defect candidate regions in the preprocessed image by using one or more detection algorithms; extracting position information of the defect candidate regions and shape feature information of the defect candidate regions; and inputting, into a pre-trained machine learning model, information related to the detection algorithms, the position information of the defect candidate regions, and the shape feature information of the defect candidate regions, to determine whether corresponding defect candidate shapes are defective.
Resumen de: US20260294235A1
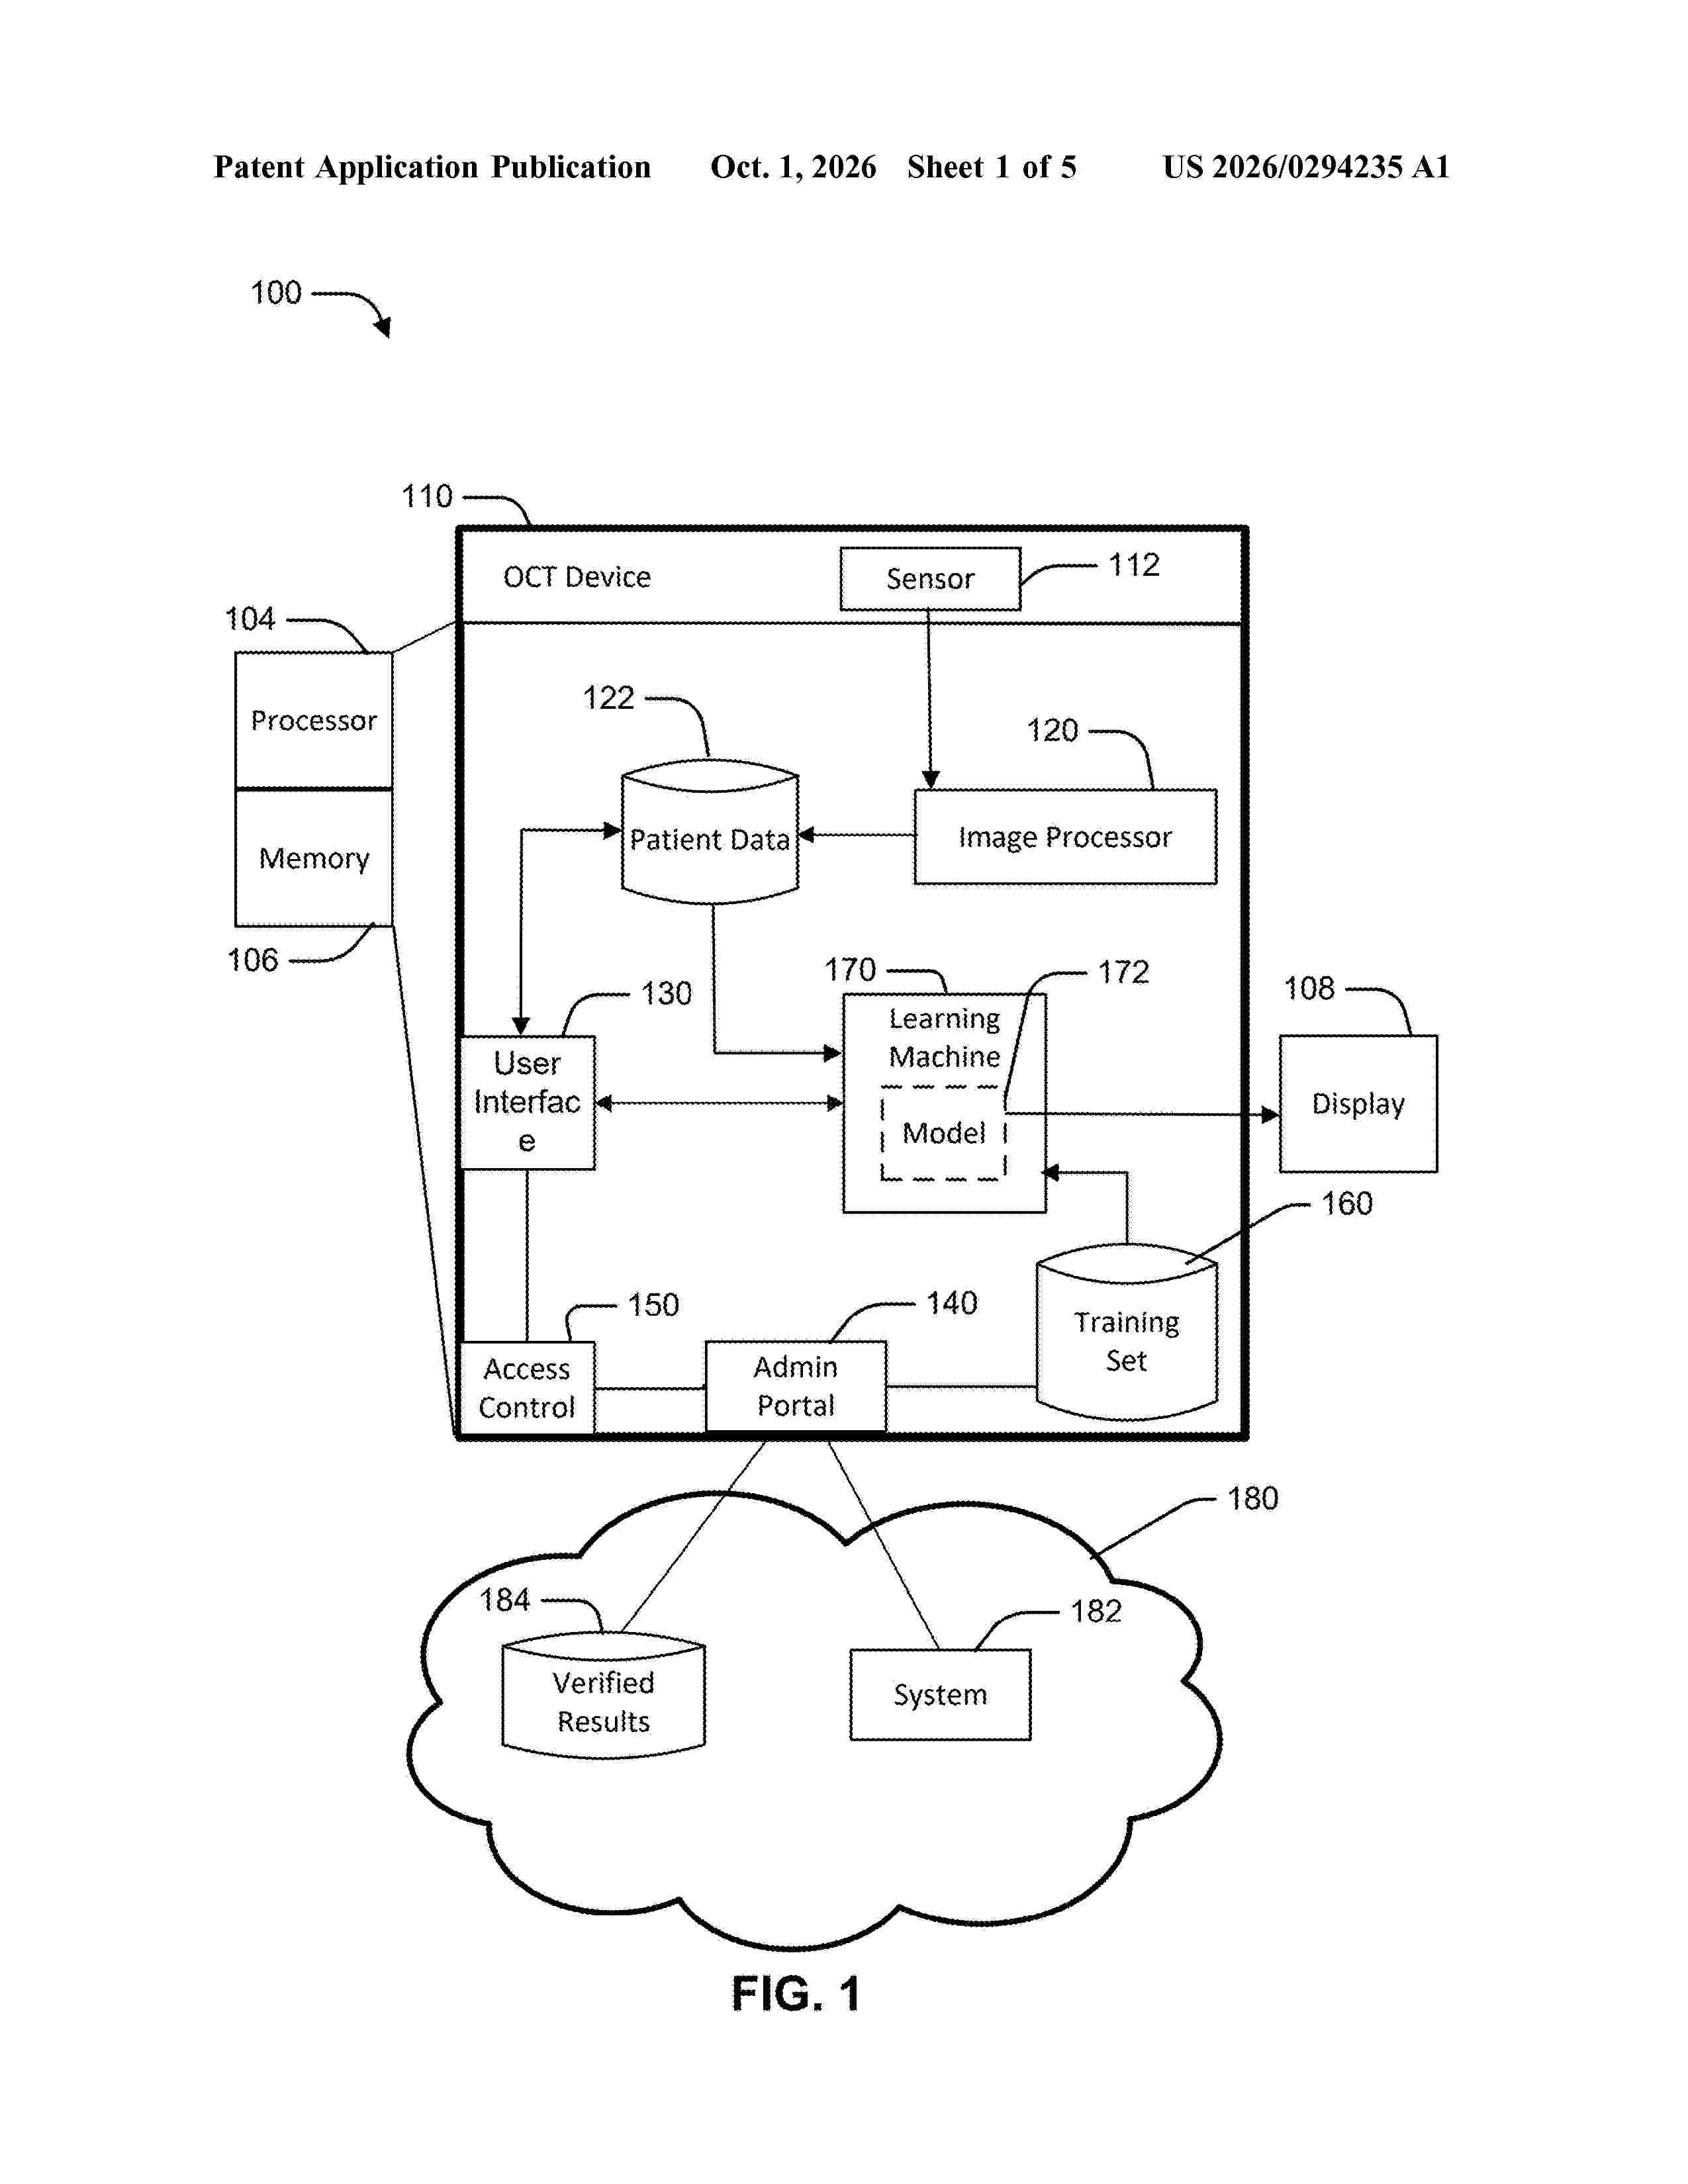
An optical coherence tomography (OCT) device includes artificial intelligence for recommending a treatment plan for a patient with a retinal or macular disease such as age-related macular degeneration (AMD). The OCT device includes a sensor configured to quantify an initial level of macular edema or retinal exudation. The OCT device receives treatment information for a series of anti-vascular endothelial growth factor (anti-VEGF) injections to the patient. The OCT device performs OCT on the patient subsequent to each anti-VEGF injection to determine subsequent levels of edema or retinal exudation. The OCT device collects a set of training data including: the initial and subsequent levels of edema or exudation, patient information, and treatment information. The OCT device applies the training data to a machine-learning model trained on training data for a plurality of patients to determine a treatment plan for the retinal or macular disease of the patient.
Resumen de: US20260301015A1
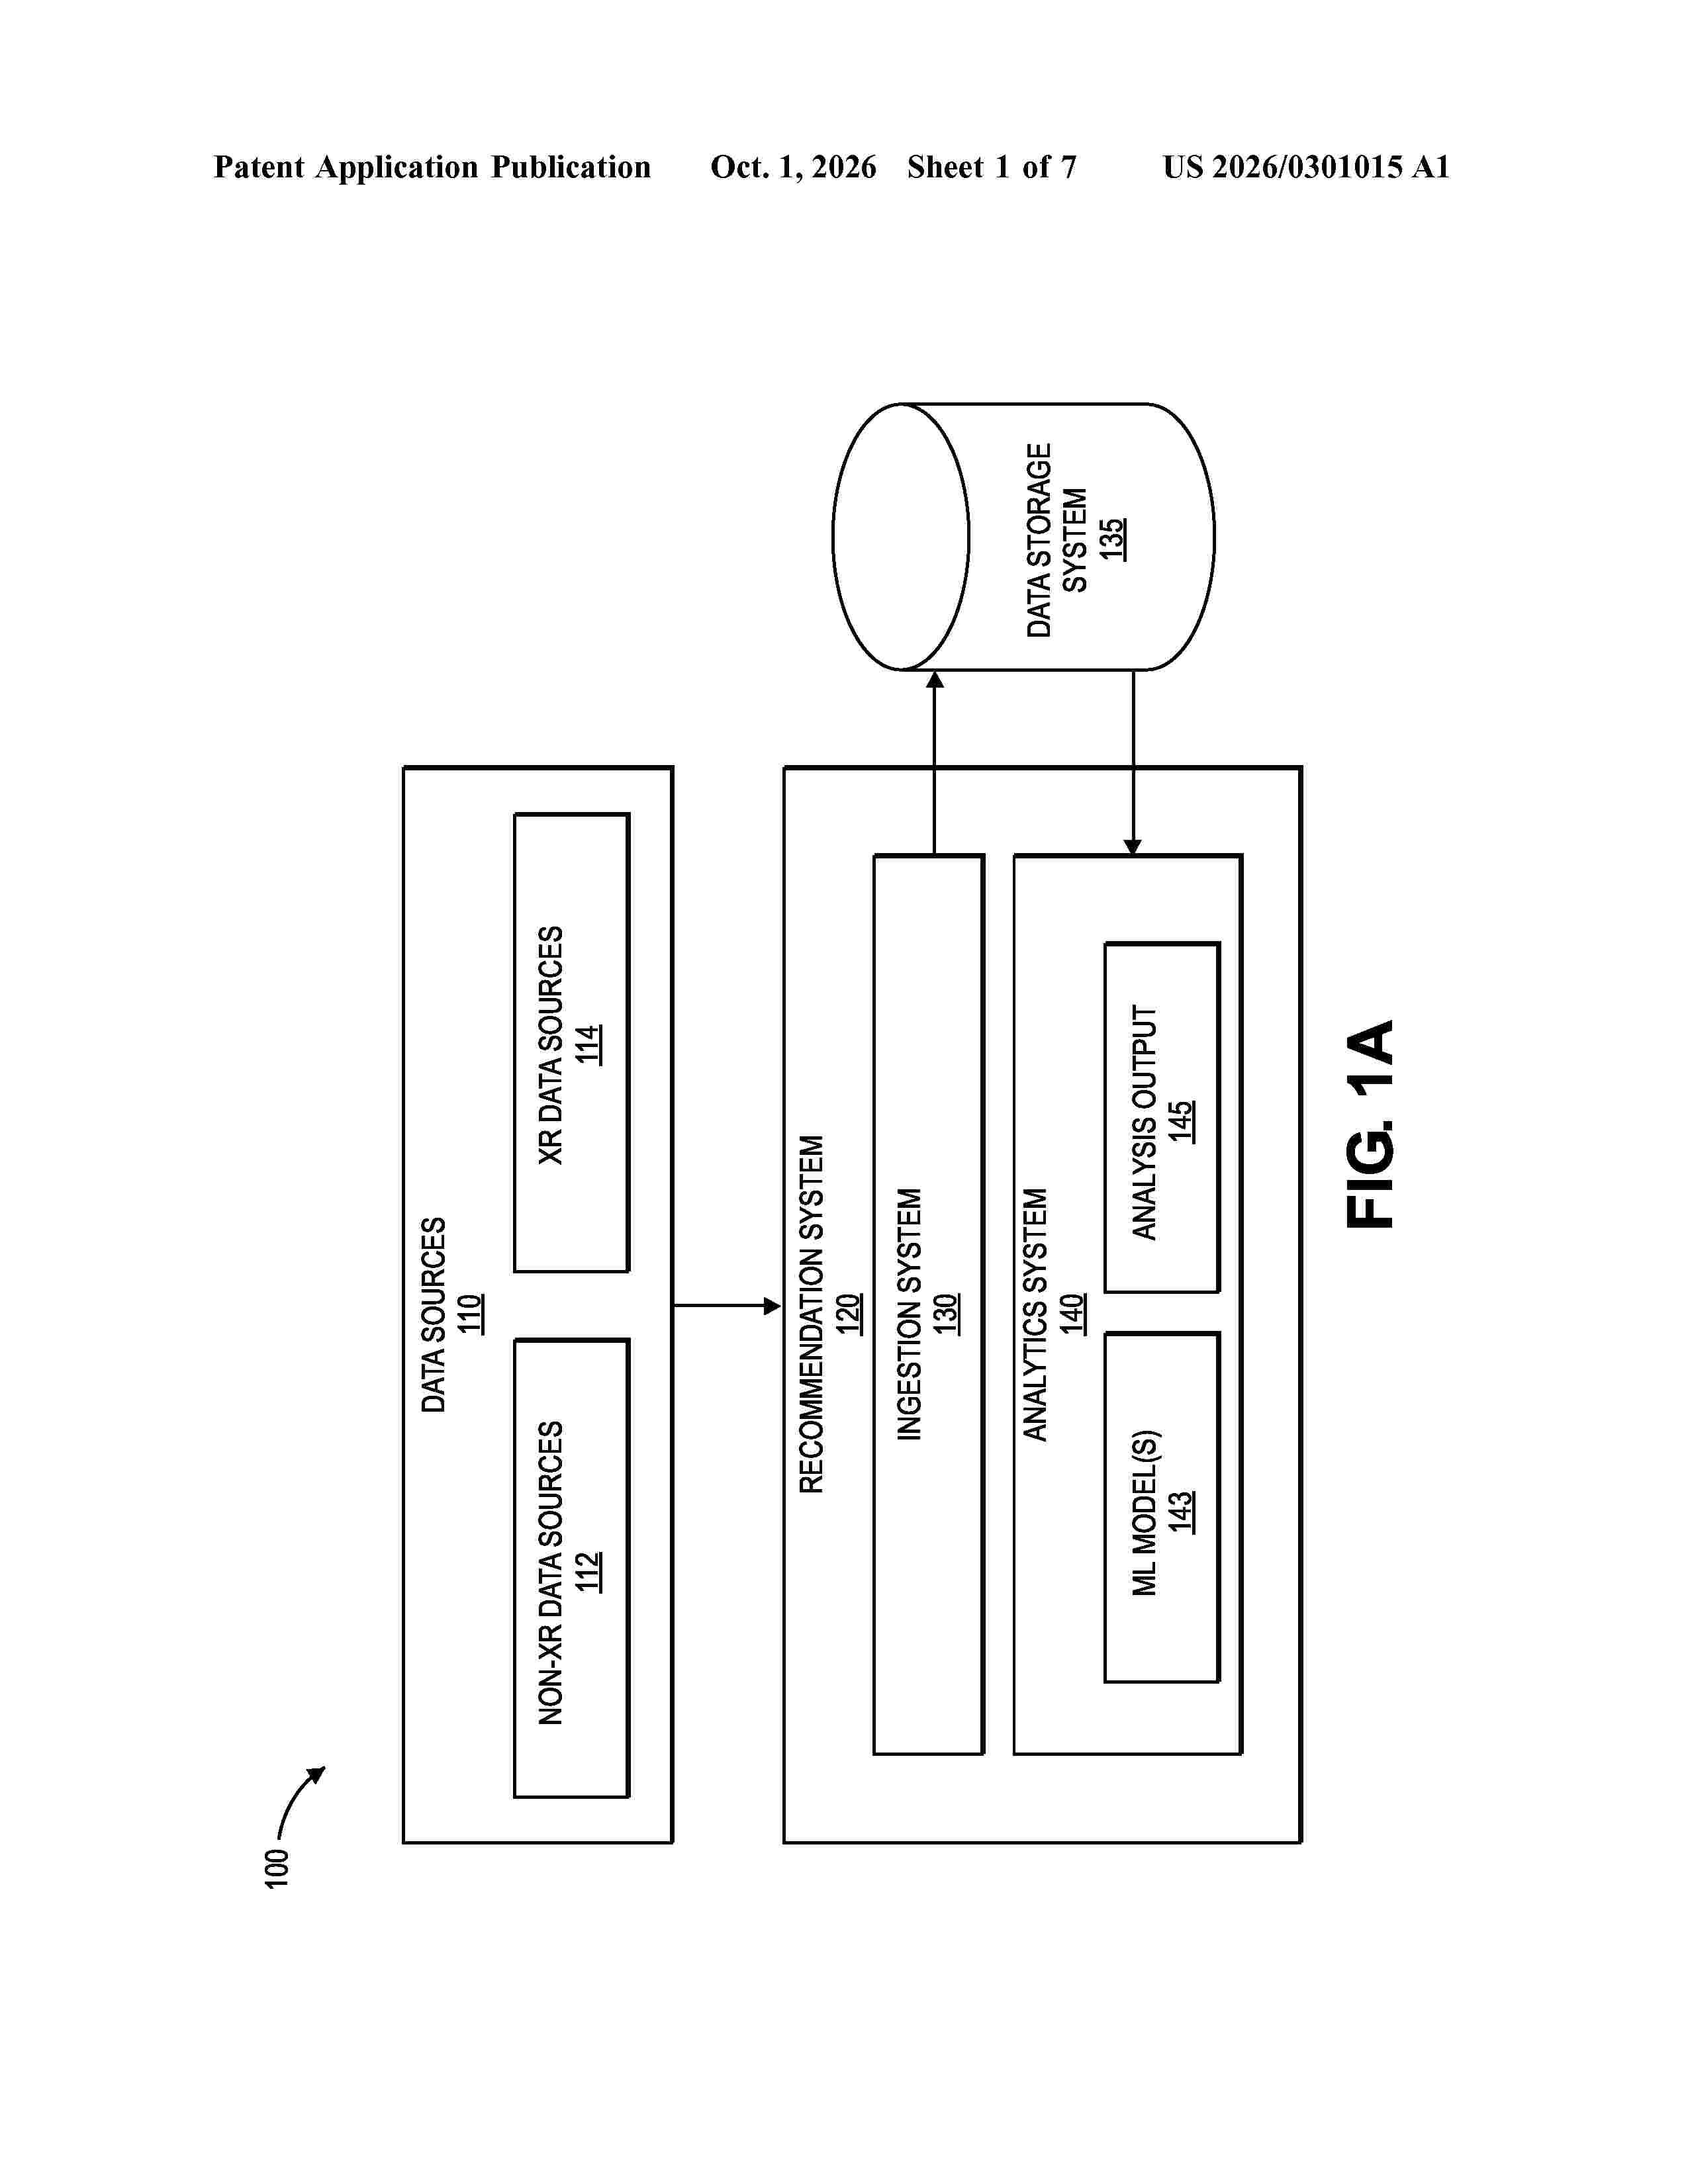
0000 A method for generating predictive and event-based action recommendations includes receiving, from at least one data source, input data representative of a user; generating, using a first machine learning model, a user behavior pattern for the user based on the input data representative of the user; classifying the user behavior pattern based on one or more personas representative of user characteristics; identifying, based on at least the input data and the one or more personas, an inefficiency in the user behavior pattern impacting a goal of the user; and generating, using a second machine learning model, a personalized recommendation for the user to remediate the inefficiency.
Resumen de: US20260303554A1
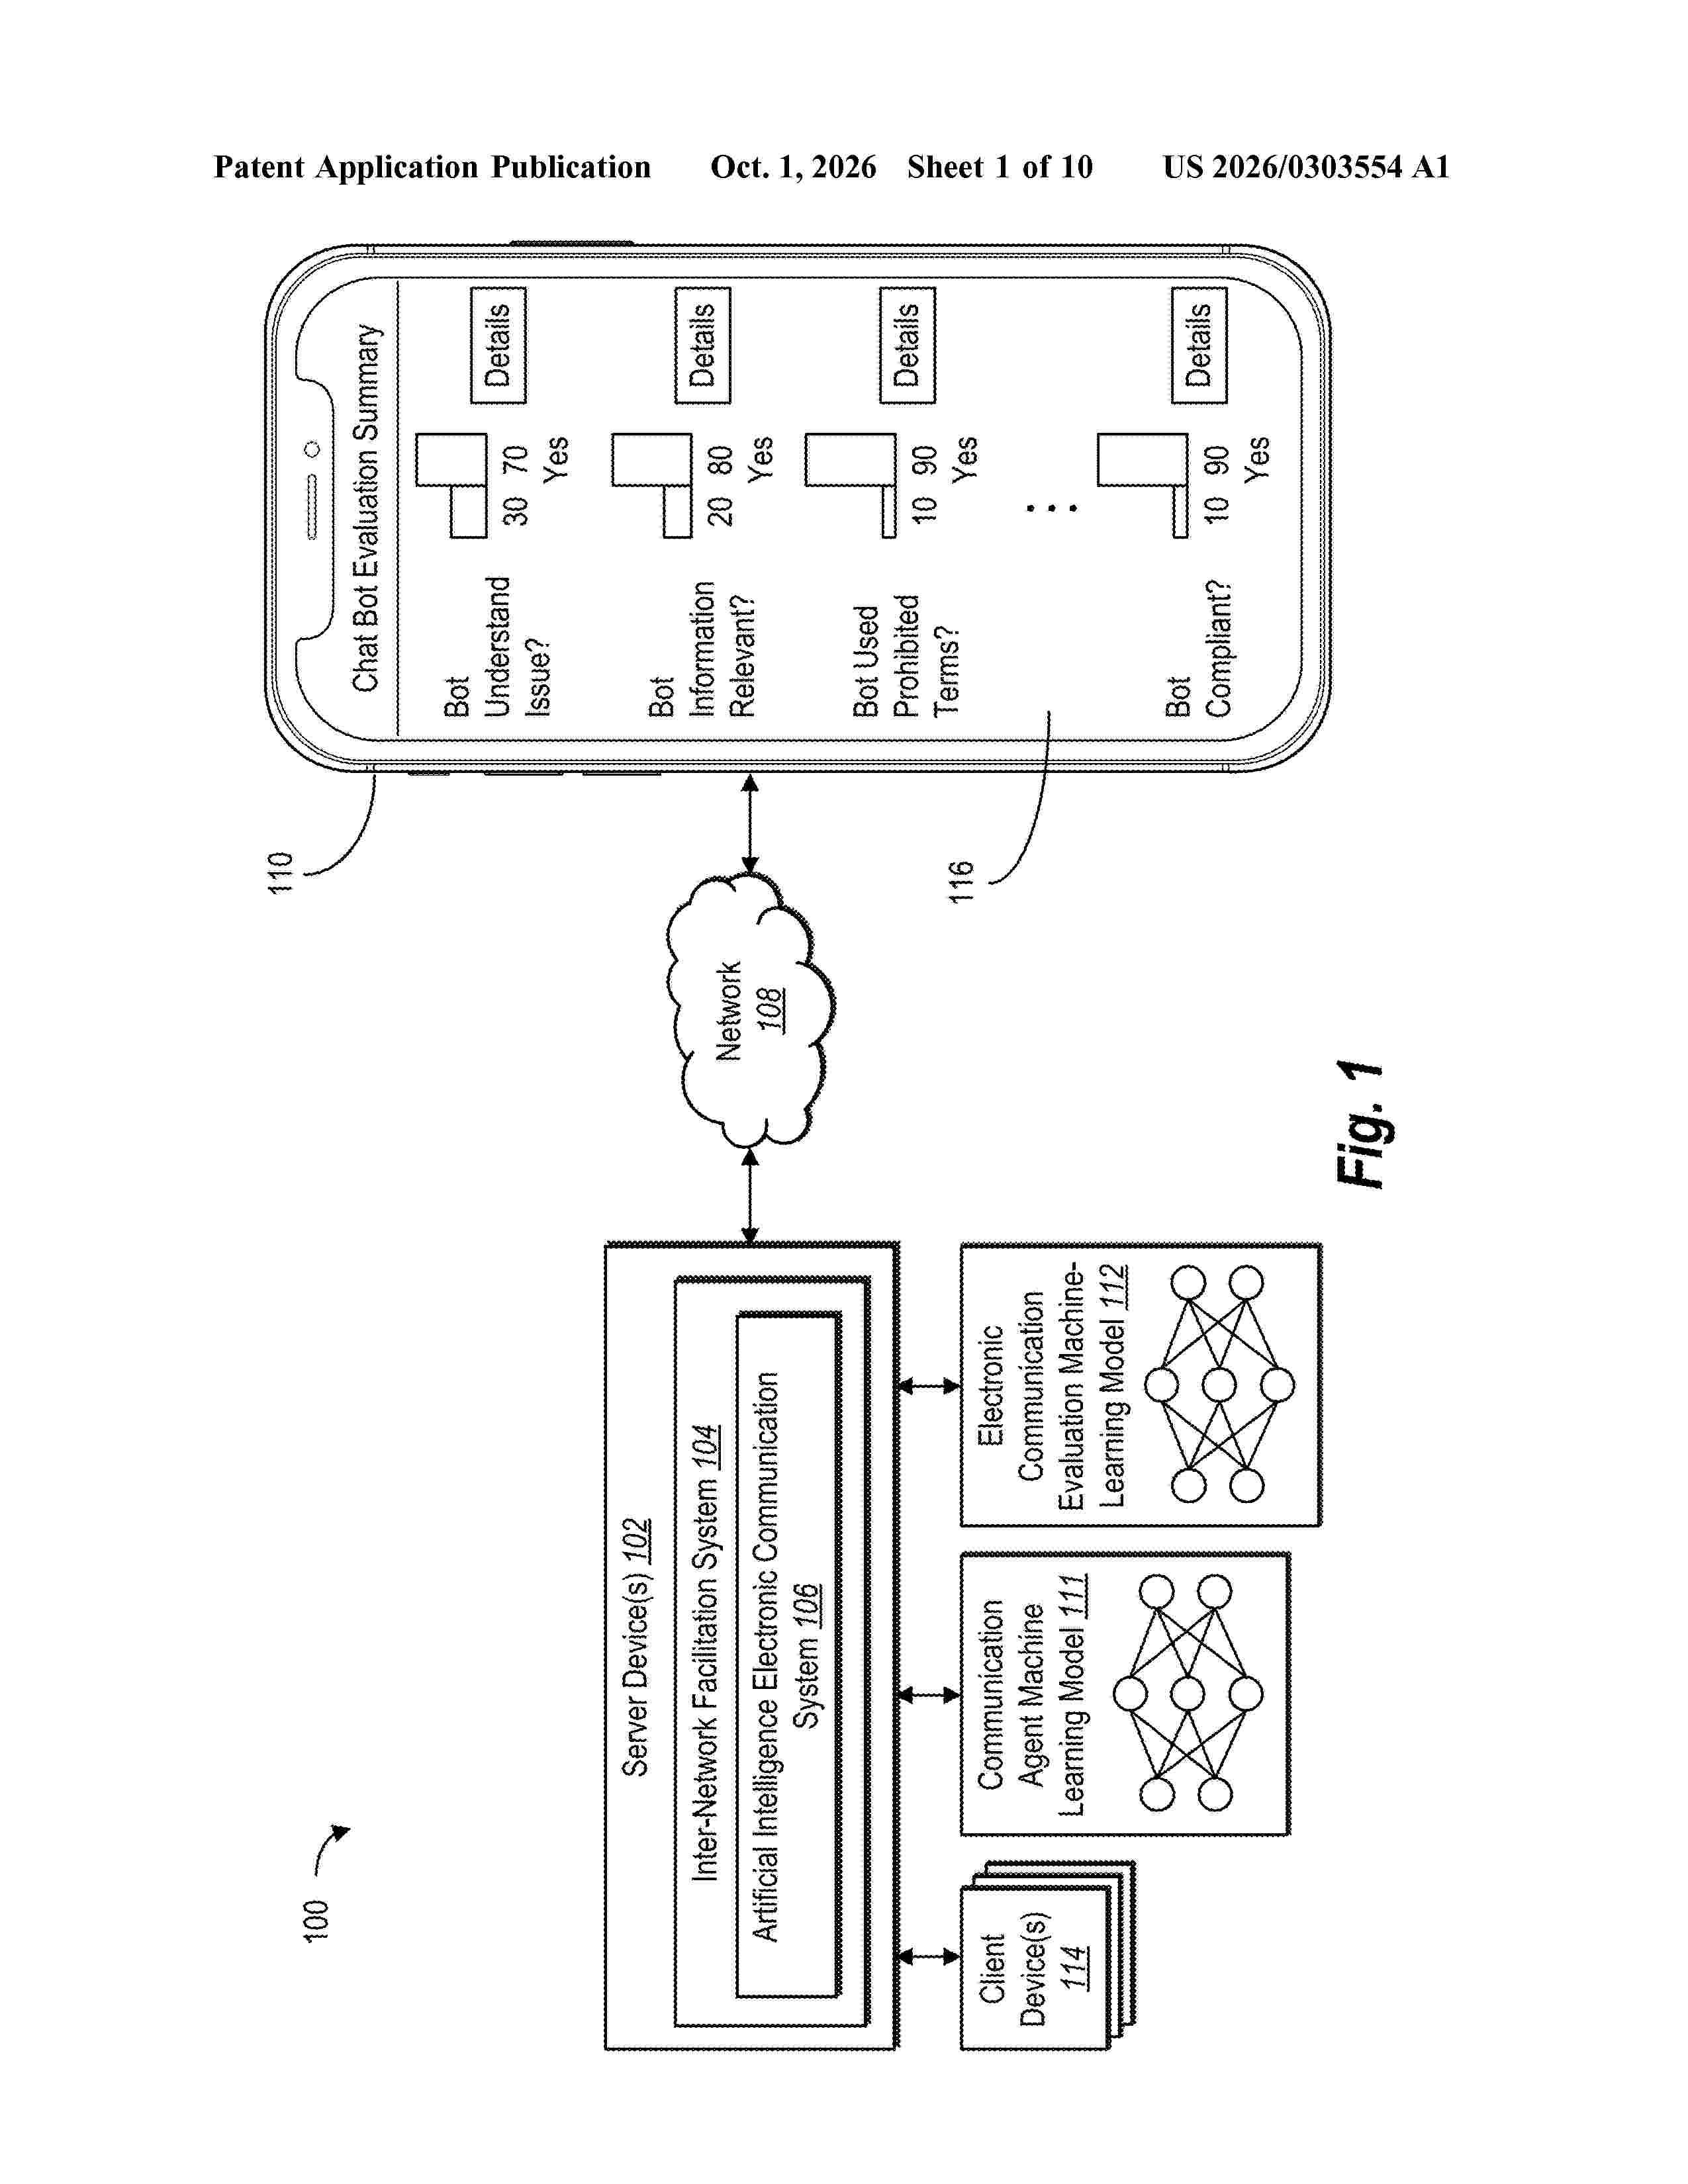
The disclosure describes embodiments of systems, methods, and non-transitory computer readable storage media that utilize machine learning to evaluate an electronic communication interaction between an artificial intelligence communication bot and a user. For example, the disclosed systems can utilize a configurable machine learning model that enables easy addition, deletion, or editing of evaluation prompts that guide the machine learning model in evaluating the electronic communication interaction from the AI communications bot. In particular, the disclosed systems can utilize the evaluation prompts with an electronic communication transcript from the AI communications bot to generate communication analysis objects that represent statistics and/or data on the behavior and/or operation of the AI communications bot. In addition, the disclosed systems can utilize the evaluation prompts with an electronic communication transcript from the AI communications bot to trigger digital actions determined from the electronic communication interaction.
Resumen de: US20260300137A1
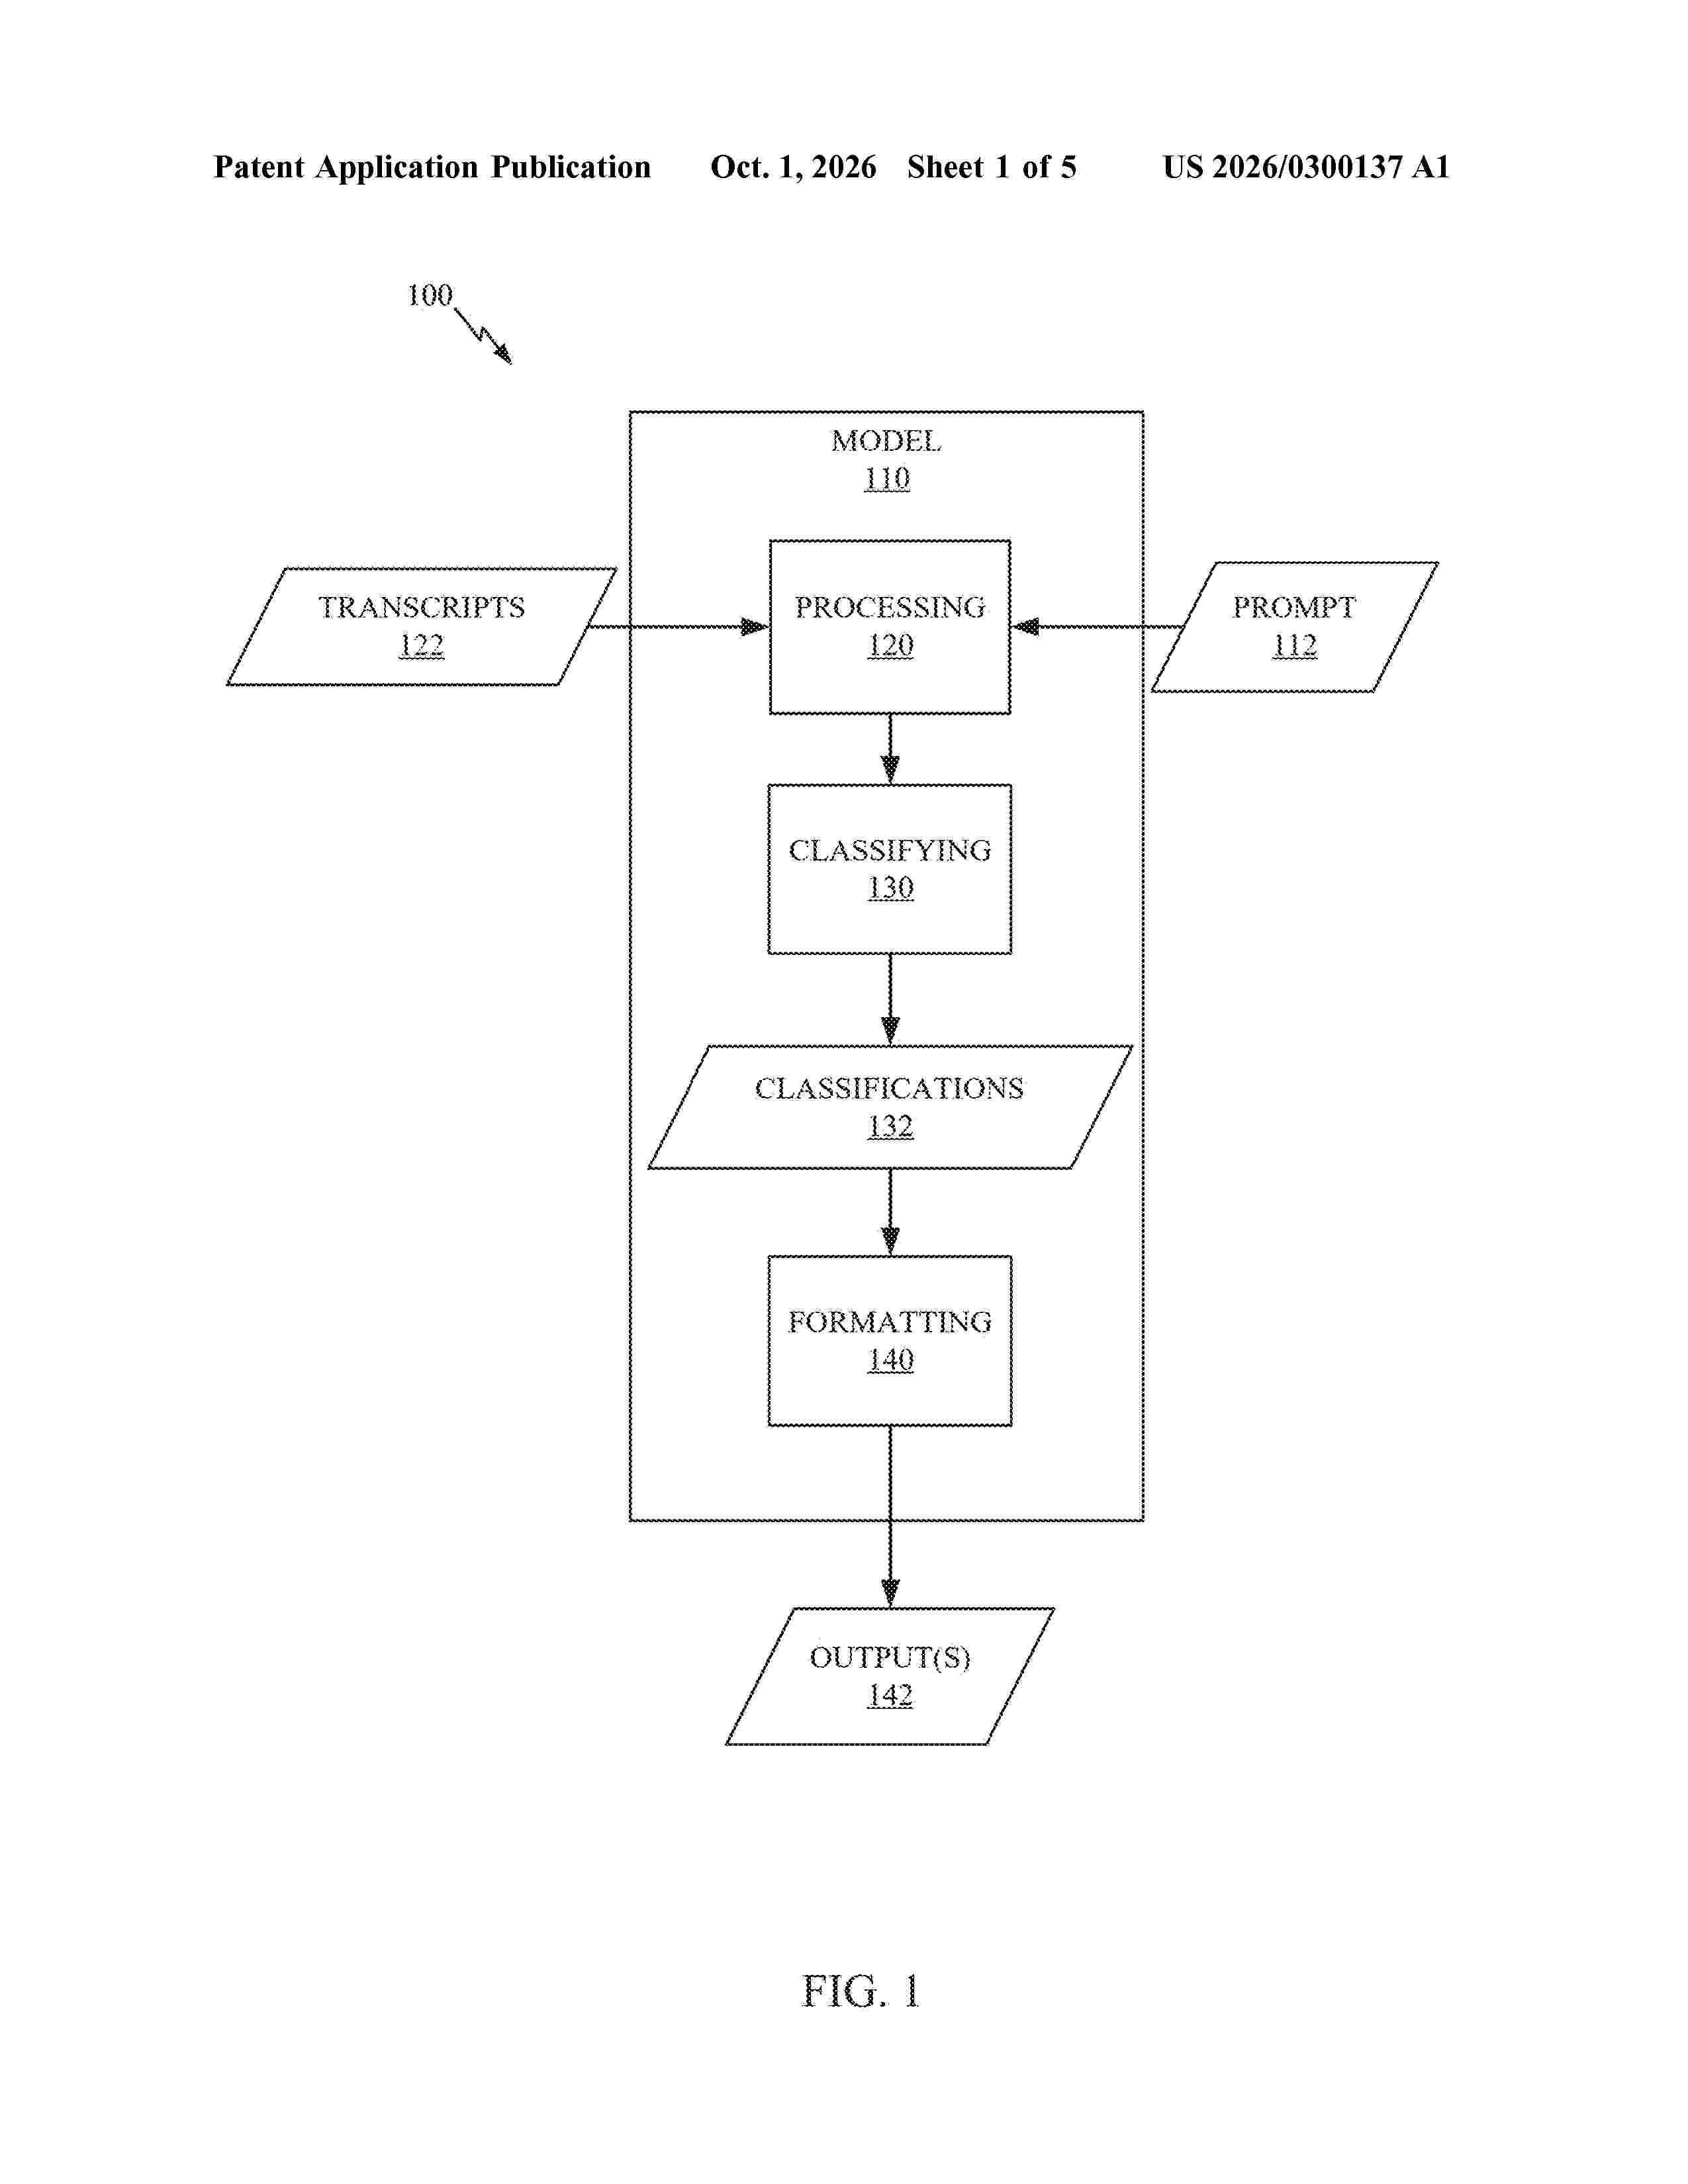
0000 Aspects of the present disclosure relate to automated bug identification using machine learning models. Embodiments include instructing a machine learning model, via a prompt, to generate an output according to instructions in the prompt. Embodiments include providing the machine learning model, via the prompt, one or more transcripts, wherein each transcript is associated with a set of user communication data. Embodiments include instructing the machine learning model, via the prompt, to parse the one or more transcripts and create a classification for each given transcript of the one or more transcripts based on one or more attributes of the given transcript. Embodiments include instructing the machine learning model, via the prompt, to provide the classification for each given transcript as the output in a structured object format. Embodiments include receiving the output from the machine learning model in response to the prompt and performing an action based on the output.
Resumen de: US20260300818A1
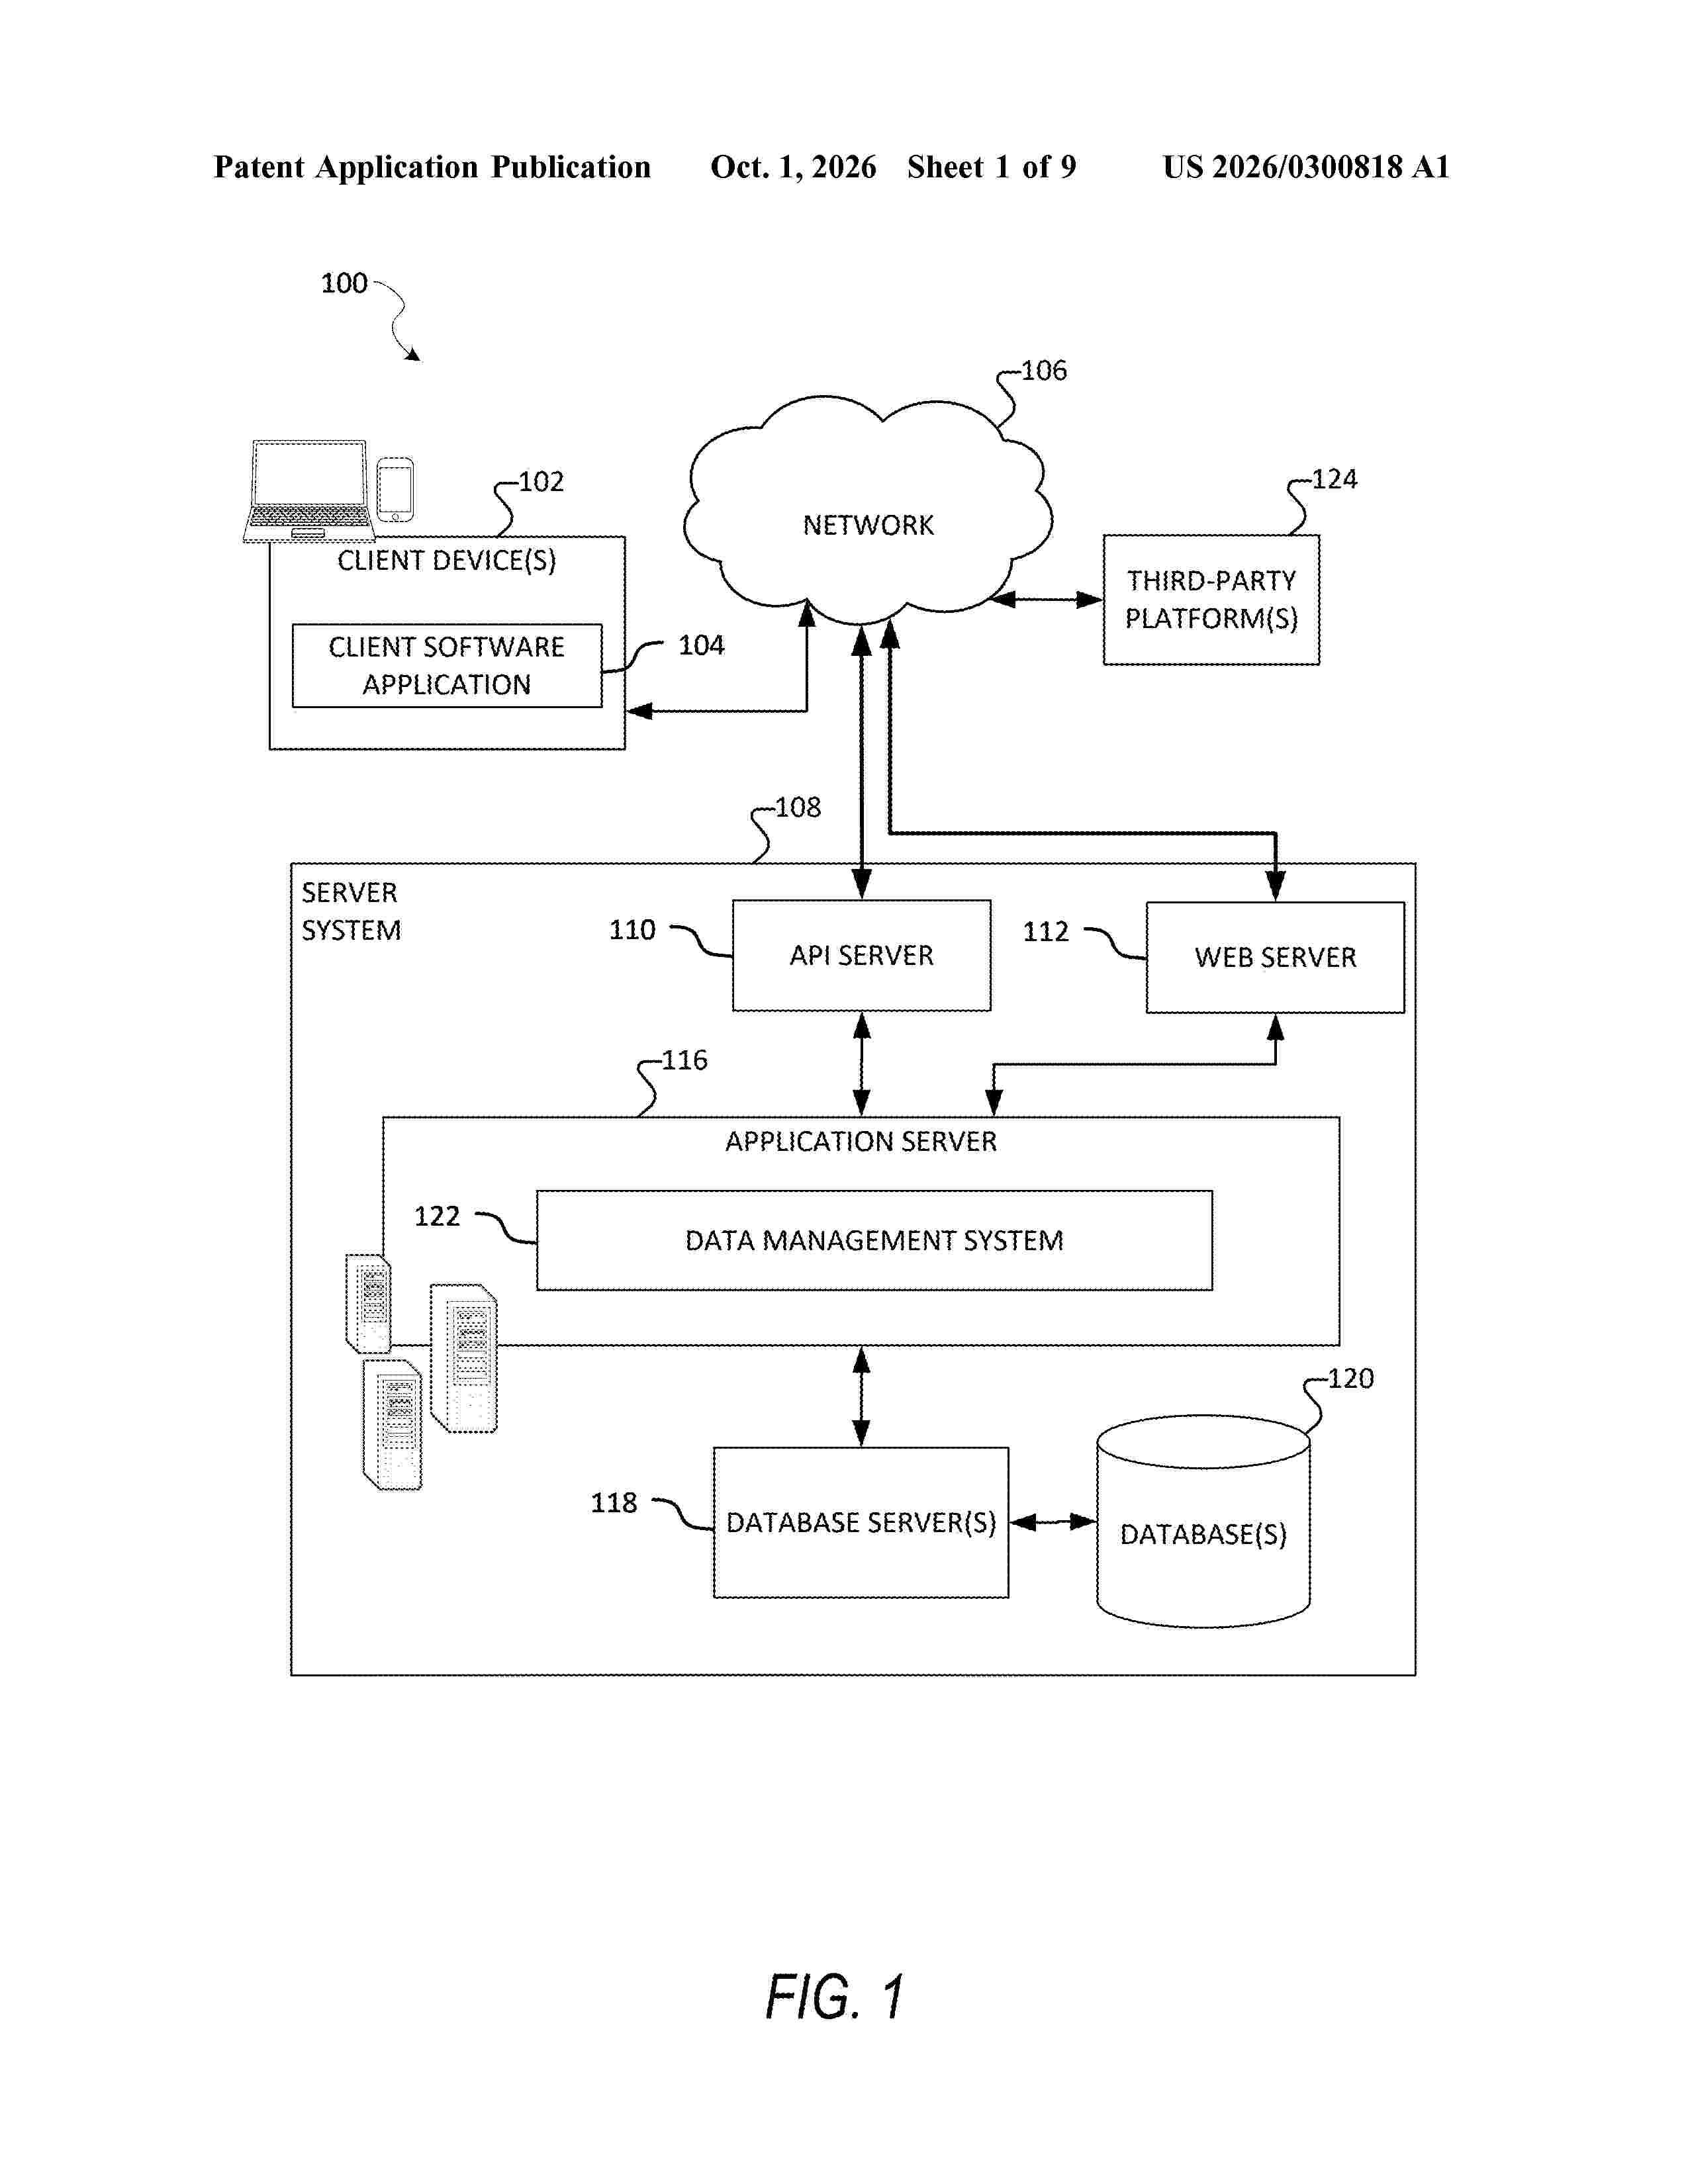
0000 Example embodiments are directed to a system that facilitates machine learning model inference simulation. A model inference simulation request is received. A model specification is identified based on the model inference simulation request. A job workflow is generated based on the model specification and the model inference simulation request. A model inference simulation result is generated using a machine learning model associated with the model specification. The model inference simulation result is then caused to be displayed on a user interface.
Resumen de: US20260300781A1
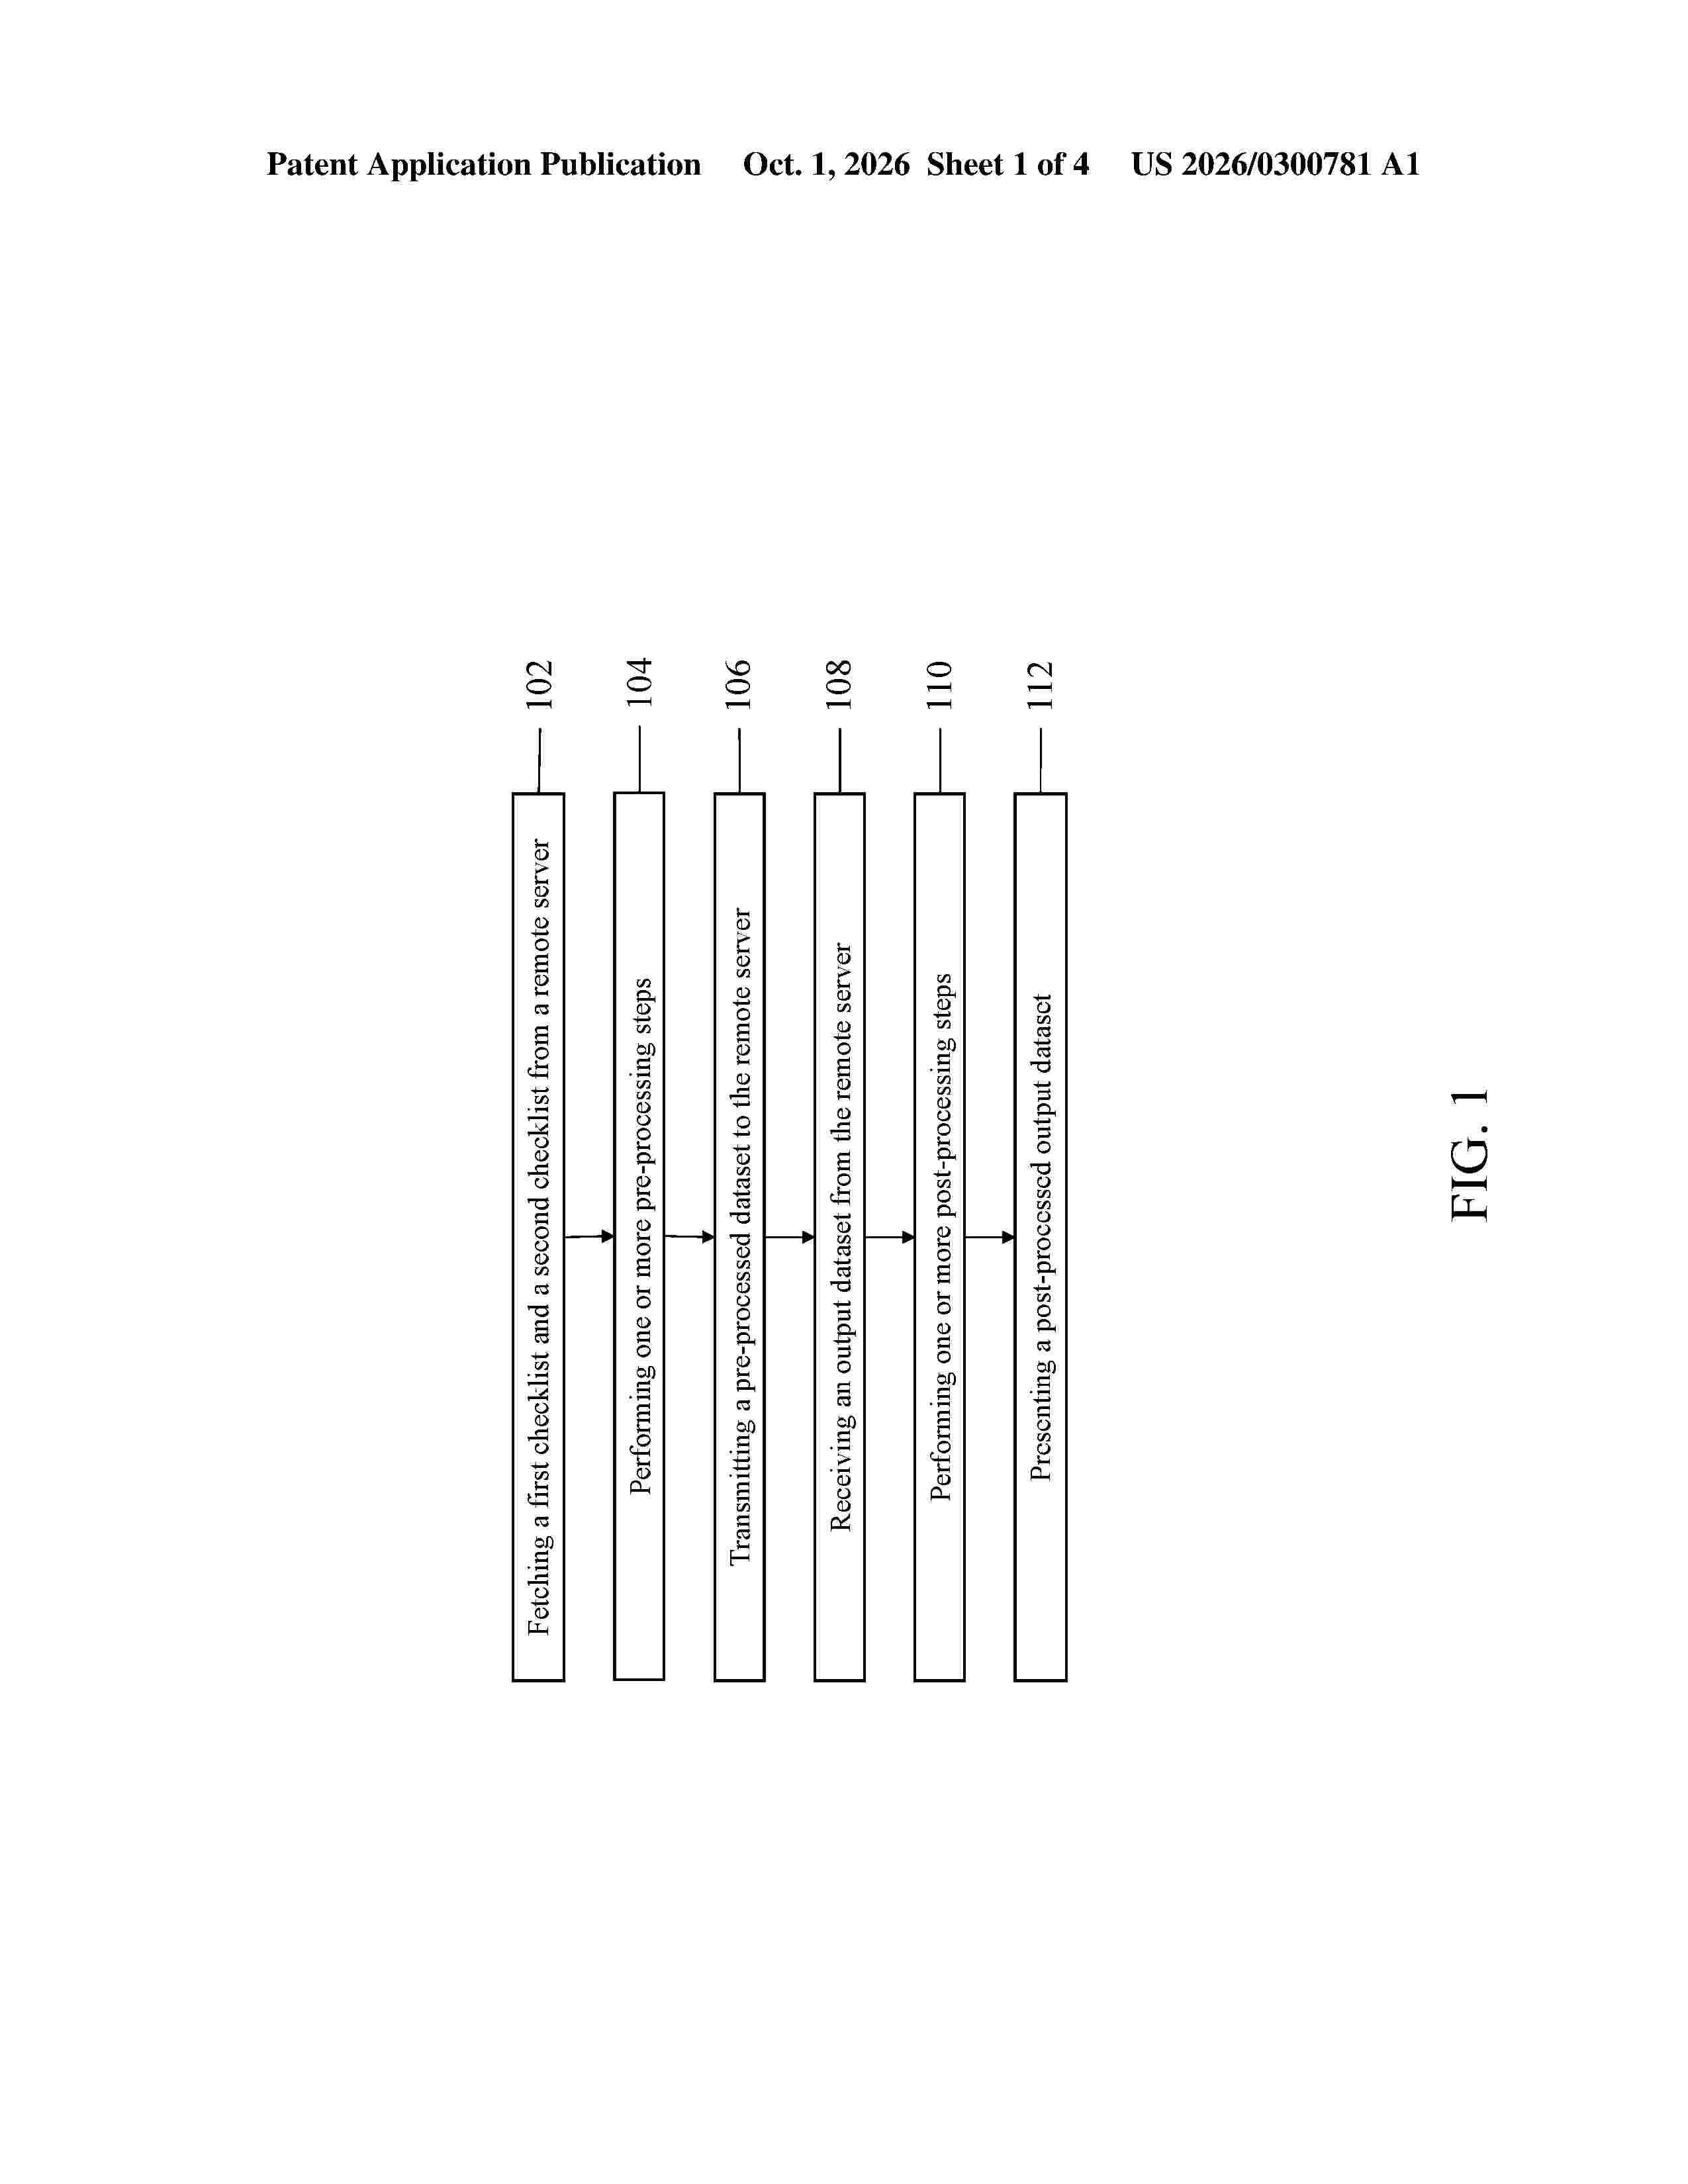
0000 Systems, methods, and computer program products for distributed generation of inferences using hosted machine learning models are disclosed. A method may comprise fetching, from a remote server, a first checklist comprising one or more pre-processing steps and a second checklist comprising one or more post-processing steps; performing the one or more pre-processing steps at a client on an input dataset to generate a pre-processed input dataset; transmitting, from the client to the remote server, the pre-processed input dataset to be processed by the machine learning model; receiving, at the client from the remote server, an output dataset; performing the one or more post-processing steps at the client on the output dataset to generate a post-processed output dataset; and presenting the post-processed output dataset via a client computing platform at the client..
Resumen de: US20260300780A1
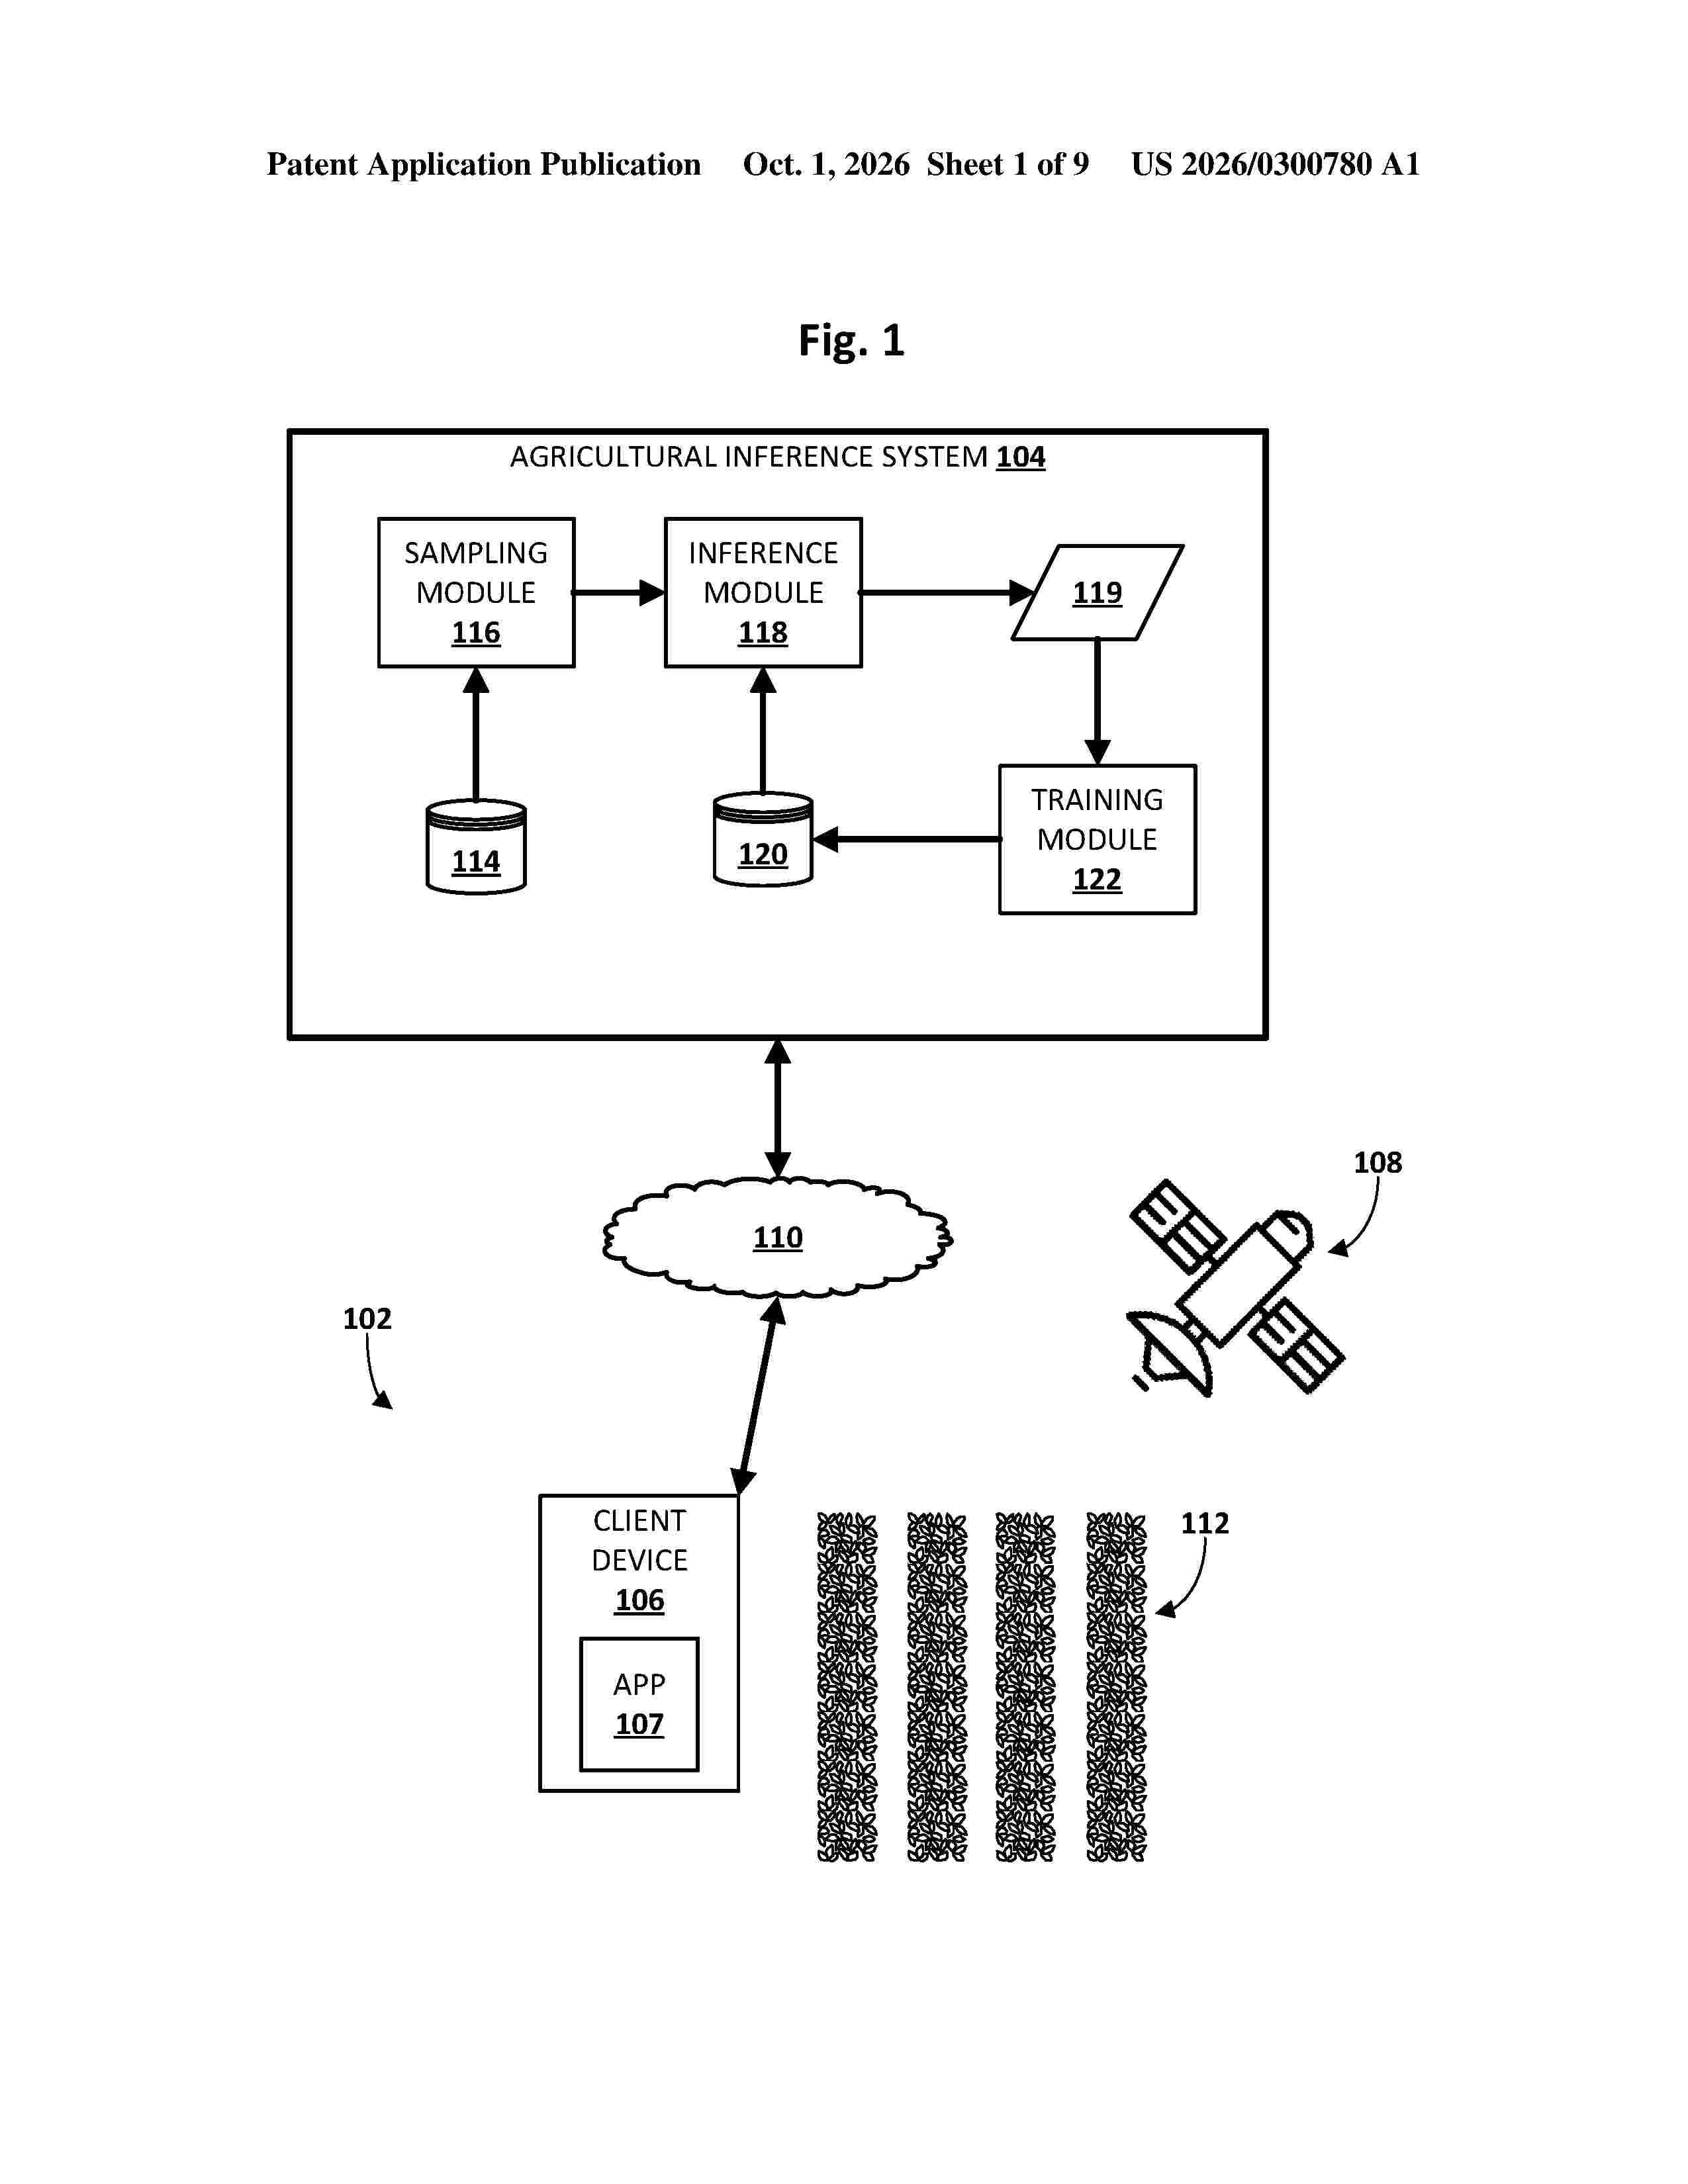
0000 Implementations are disclosed for training and/or applying a single machine learning model to generate mid-cycle inferences based on variable length time series inputs. In some implementations, a time series of satellite imagery samples that depict an agricultural area over all or part of a crop cycle may be obtained. During training, ground truth agricultural classifications may be obtained for geographic units of the agricultural area represented by individual pixels of the satellite imagery samples. During training, sample(s) of the time series may be masked to generate a partially masked satellite imagery samples, which in tum may be used to generate input embedding(s). The input embedding(s) may be applied across a machine learning model to generate output(s) representing in-season agricultural prediction(s). During training, the in-season agricultural prediction(s) may be compared with the ground truth agricultural classifications to train the machine learning model.
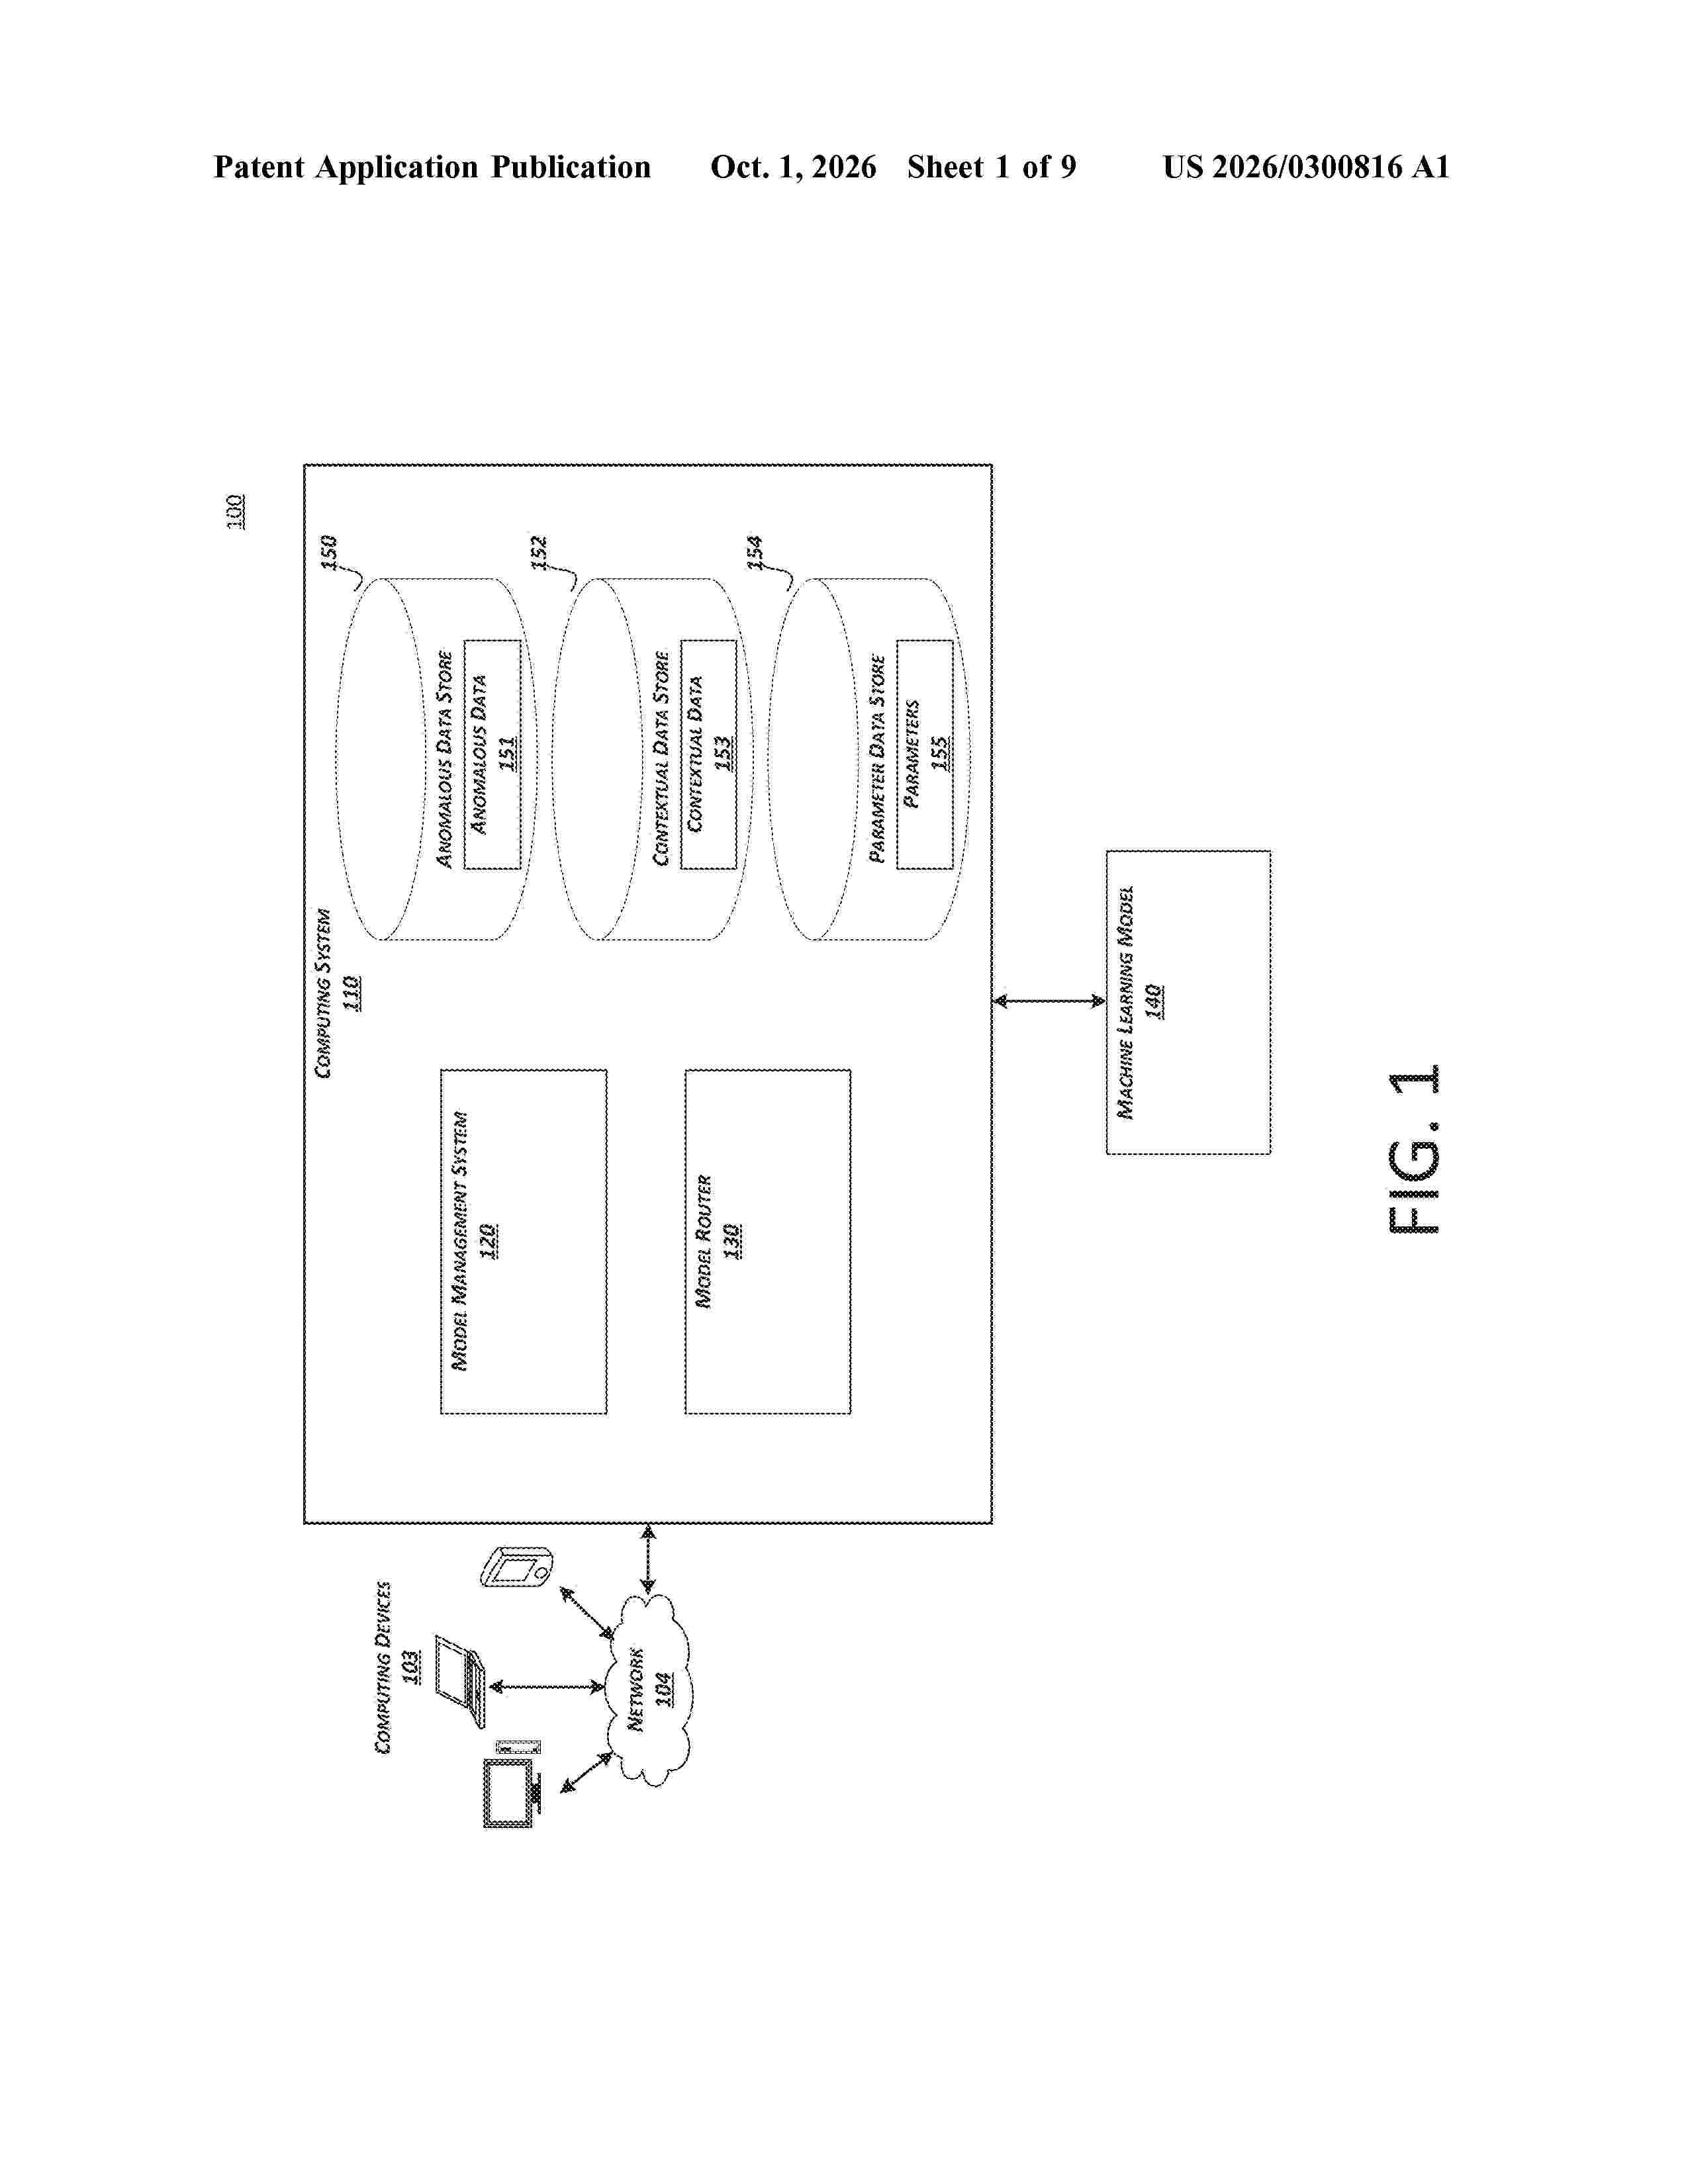
Resumen de: US20260300816A1
Systems and methods are provided to dynamically adjust contextual data of a machine learning model during an inference process of the machine learning model. A system can identify one or more tokens generated by the machine learning model. The machine learning model may, during an inference process, generate the one or more tokens based on first contextual data. The system can determine that the one or more tokens satisfy one or more first parameters. The system can obtain second contextual data associated with the one or more tokens based on determining that the one or more tokens satisfy the one or more first parameters and can provide the second contextual data to the machine learning model. The machine learning model may generate an output based on the second contextual data and at least a portion of the first contextual data.
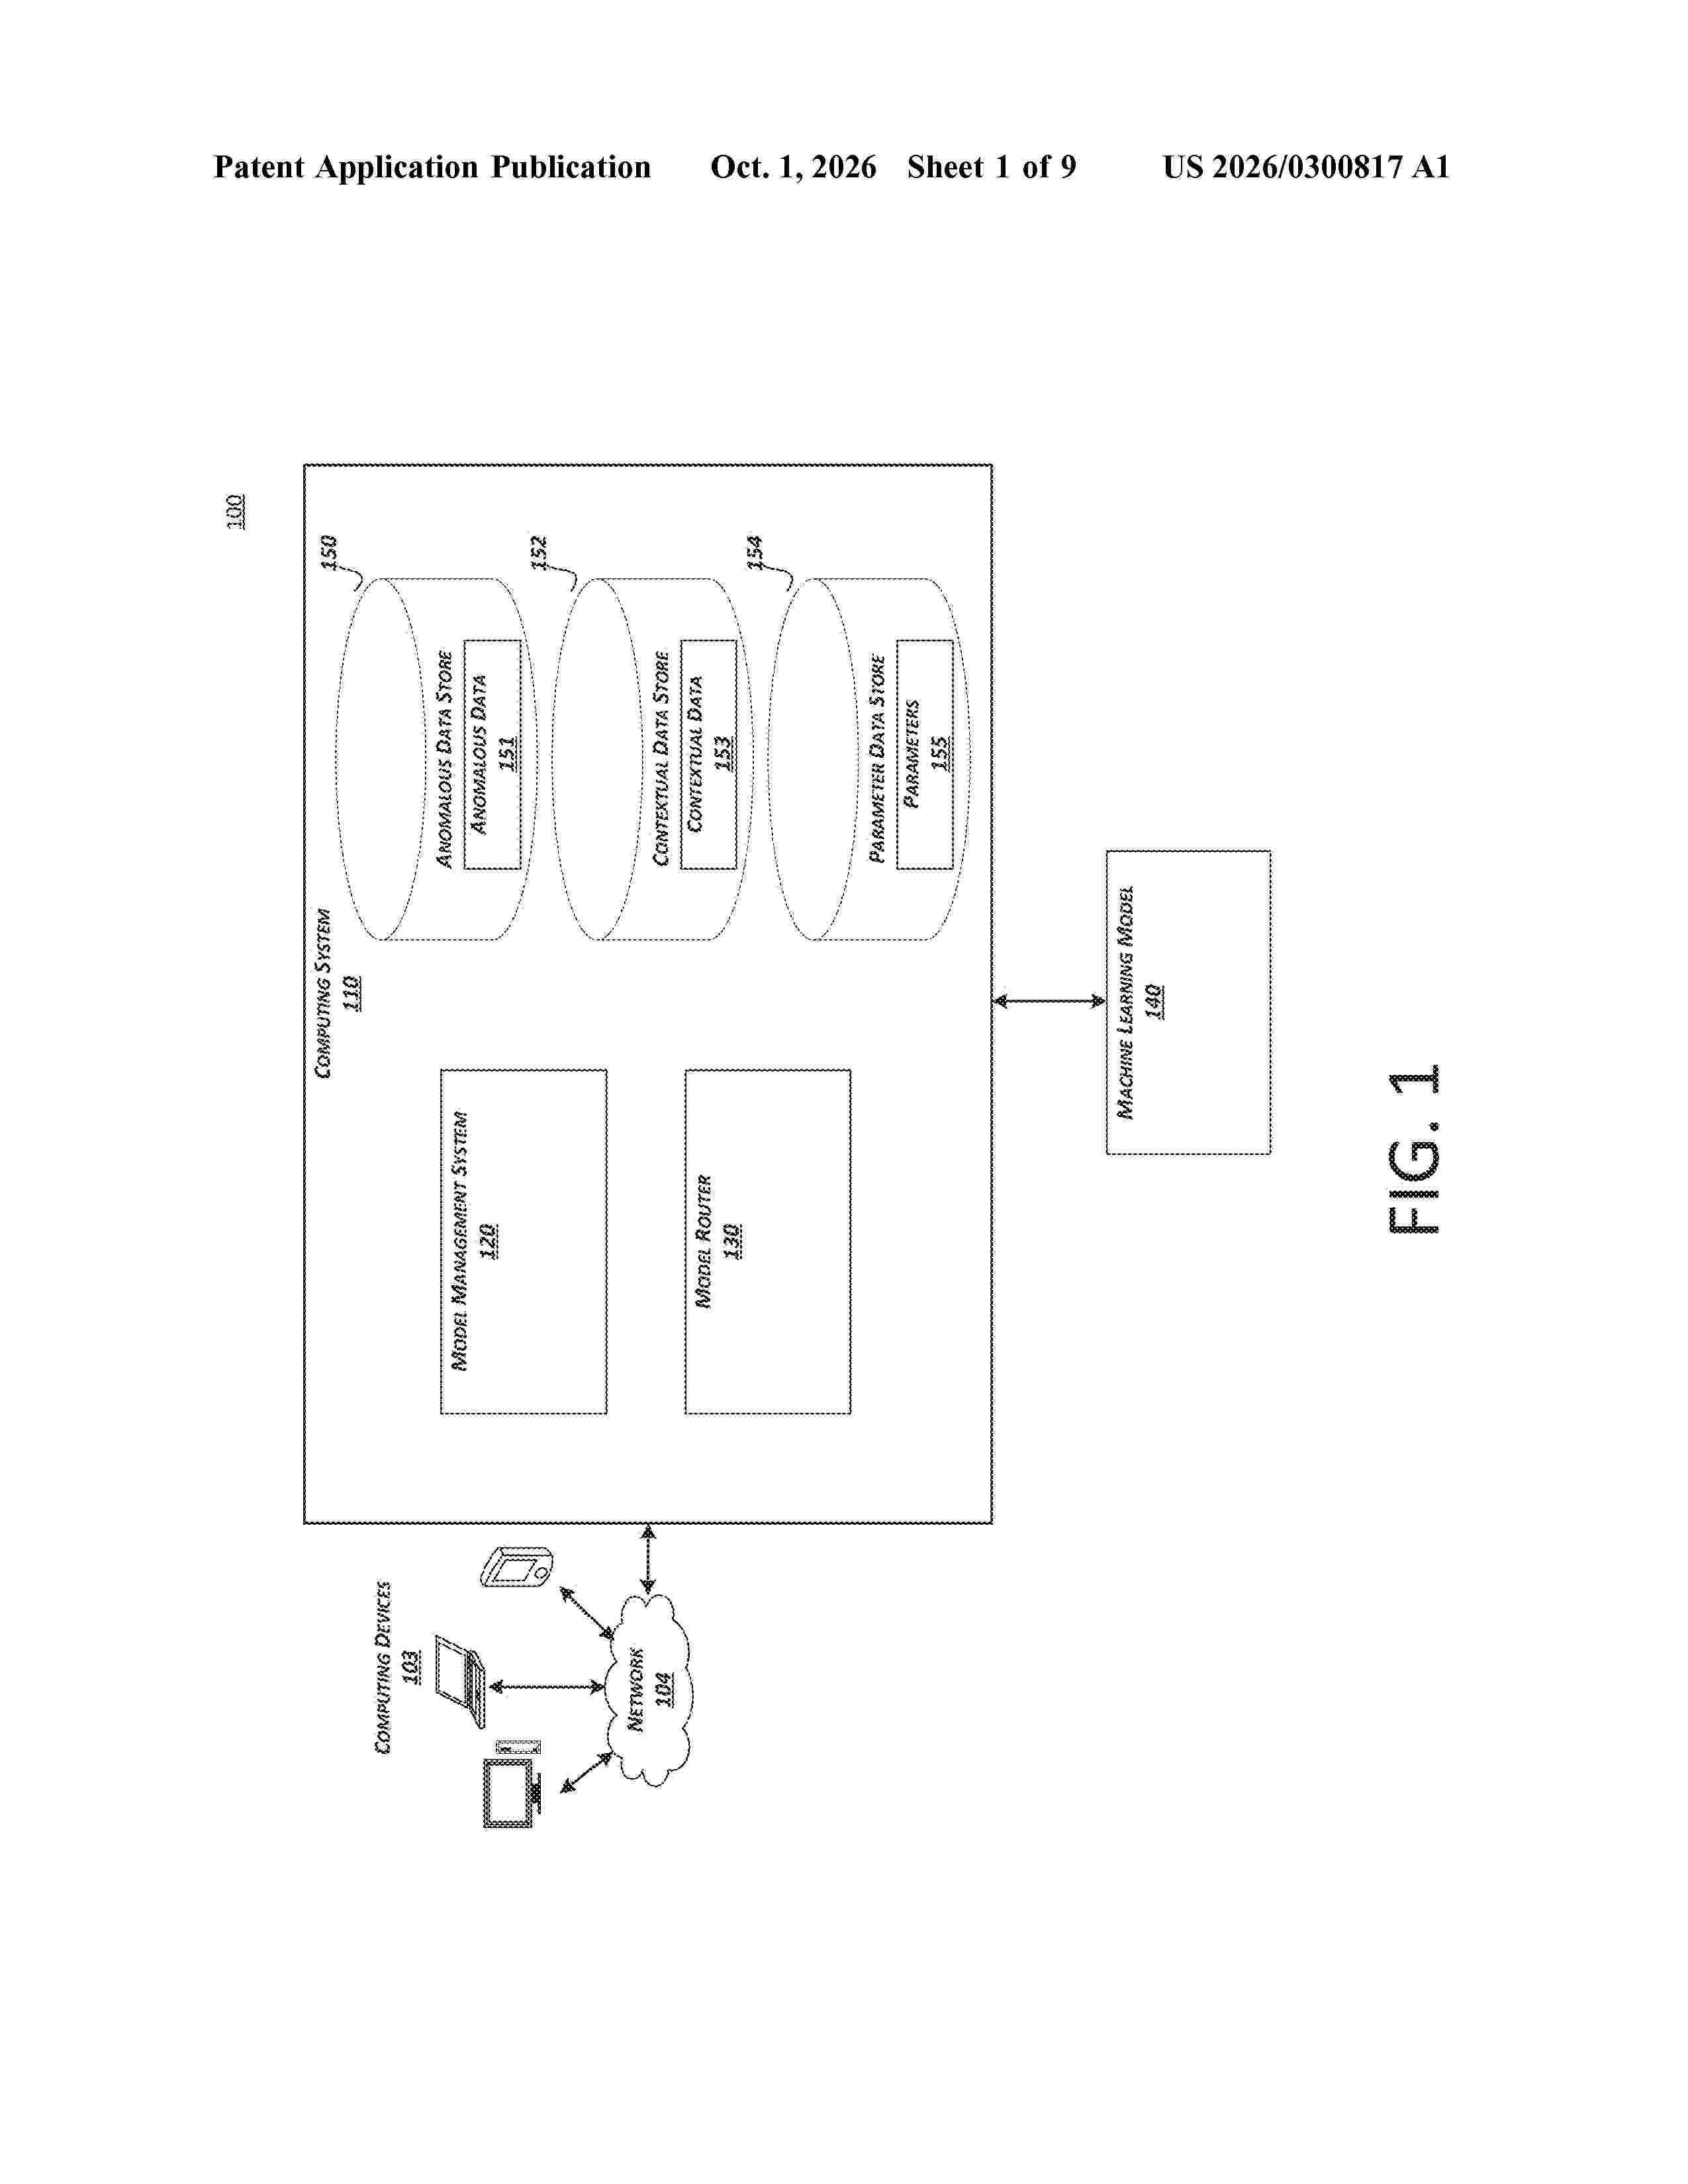
Resumen de: US20260300817A1
Systems and methods are provided to detect anomalous data obtained from and/or to be routed to a machine learning model. A system can identify a first embedding generated by a machine learning model. The system can obtain a first set of data associated with the machine learning model and can compare the first embedding generated by the machine learning model with the first set of data. Based on comparing the first embedding generated by the machine learning model with the first set of data, the system can determine a manner of processing a second set of data (e.g., an input to and/or an output of the machine learning model). The system can process the second set of data according to the manner of processing the second set of data.
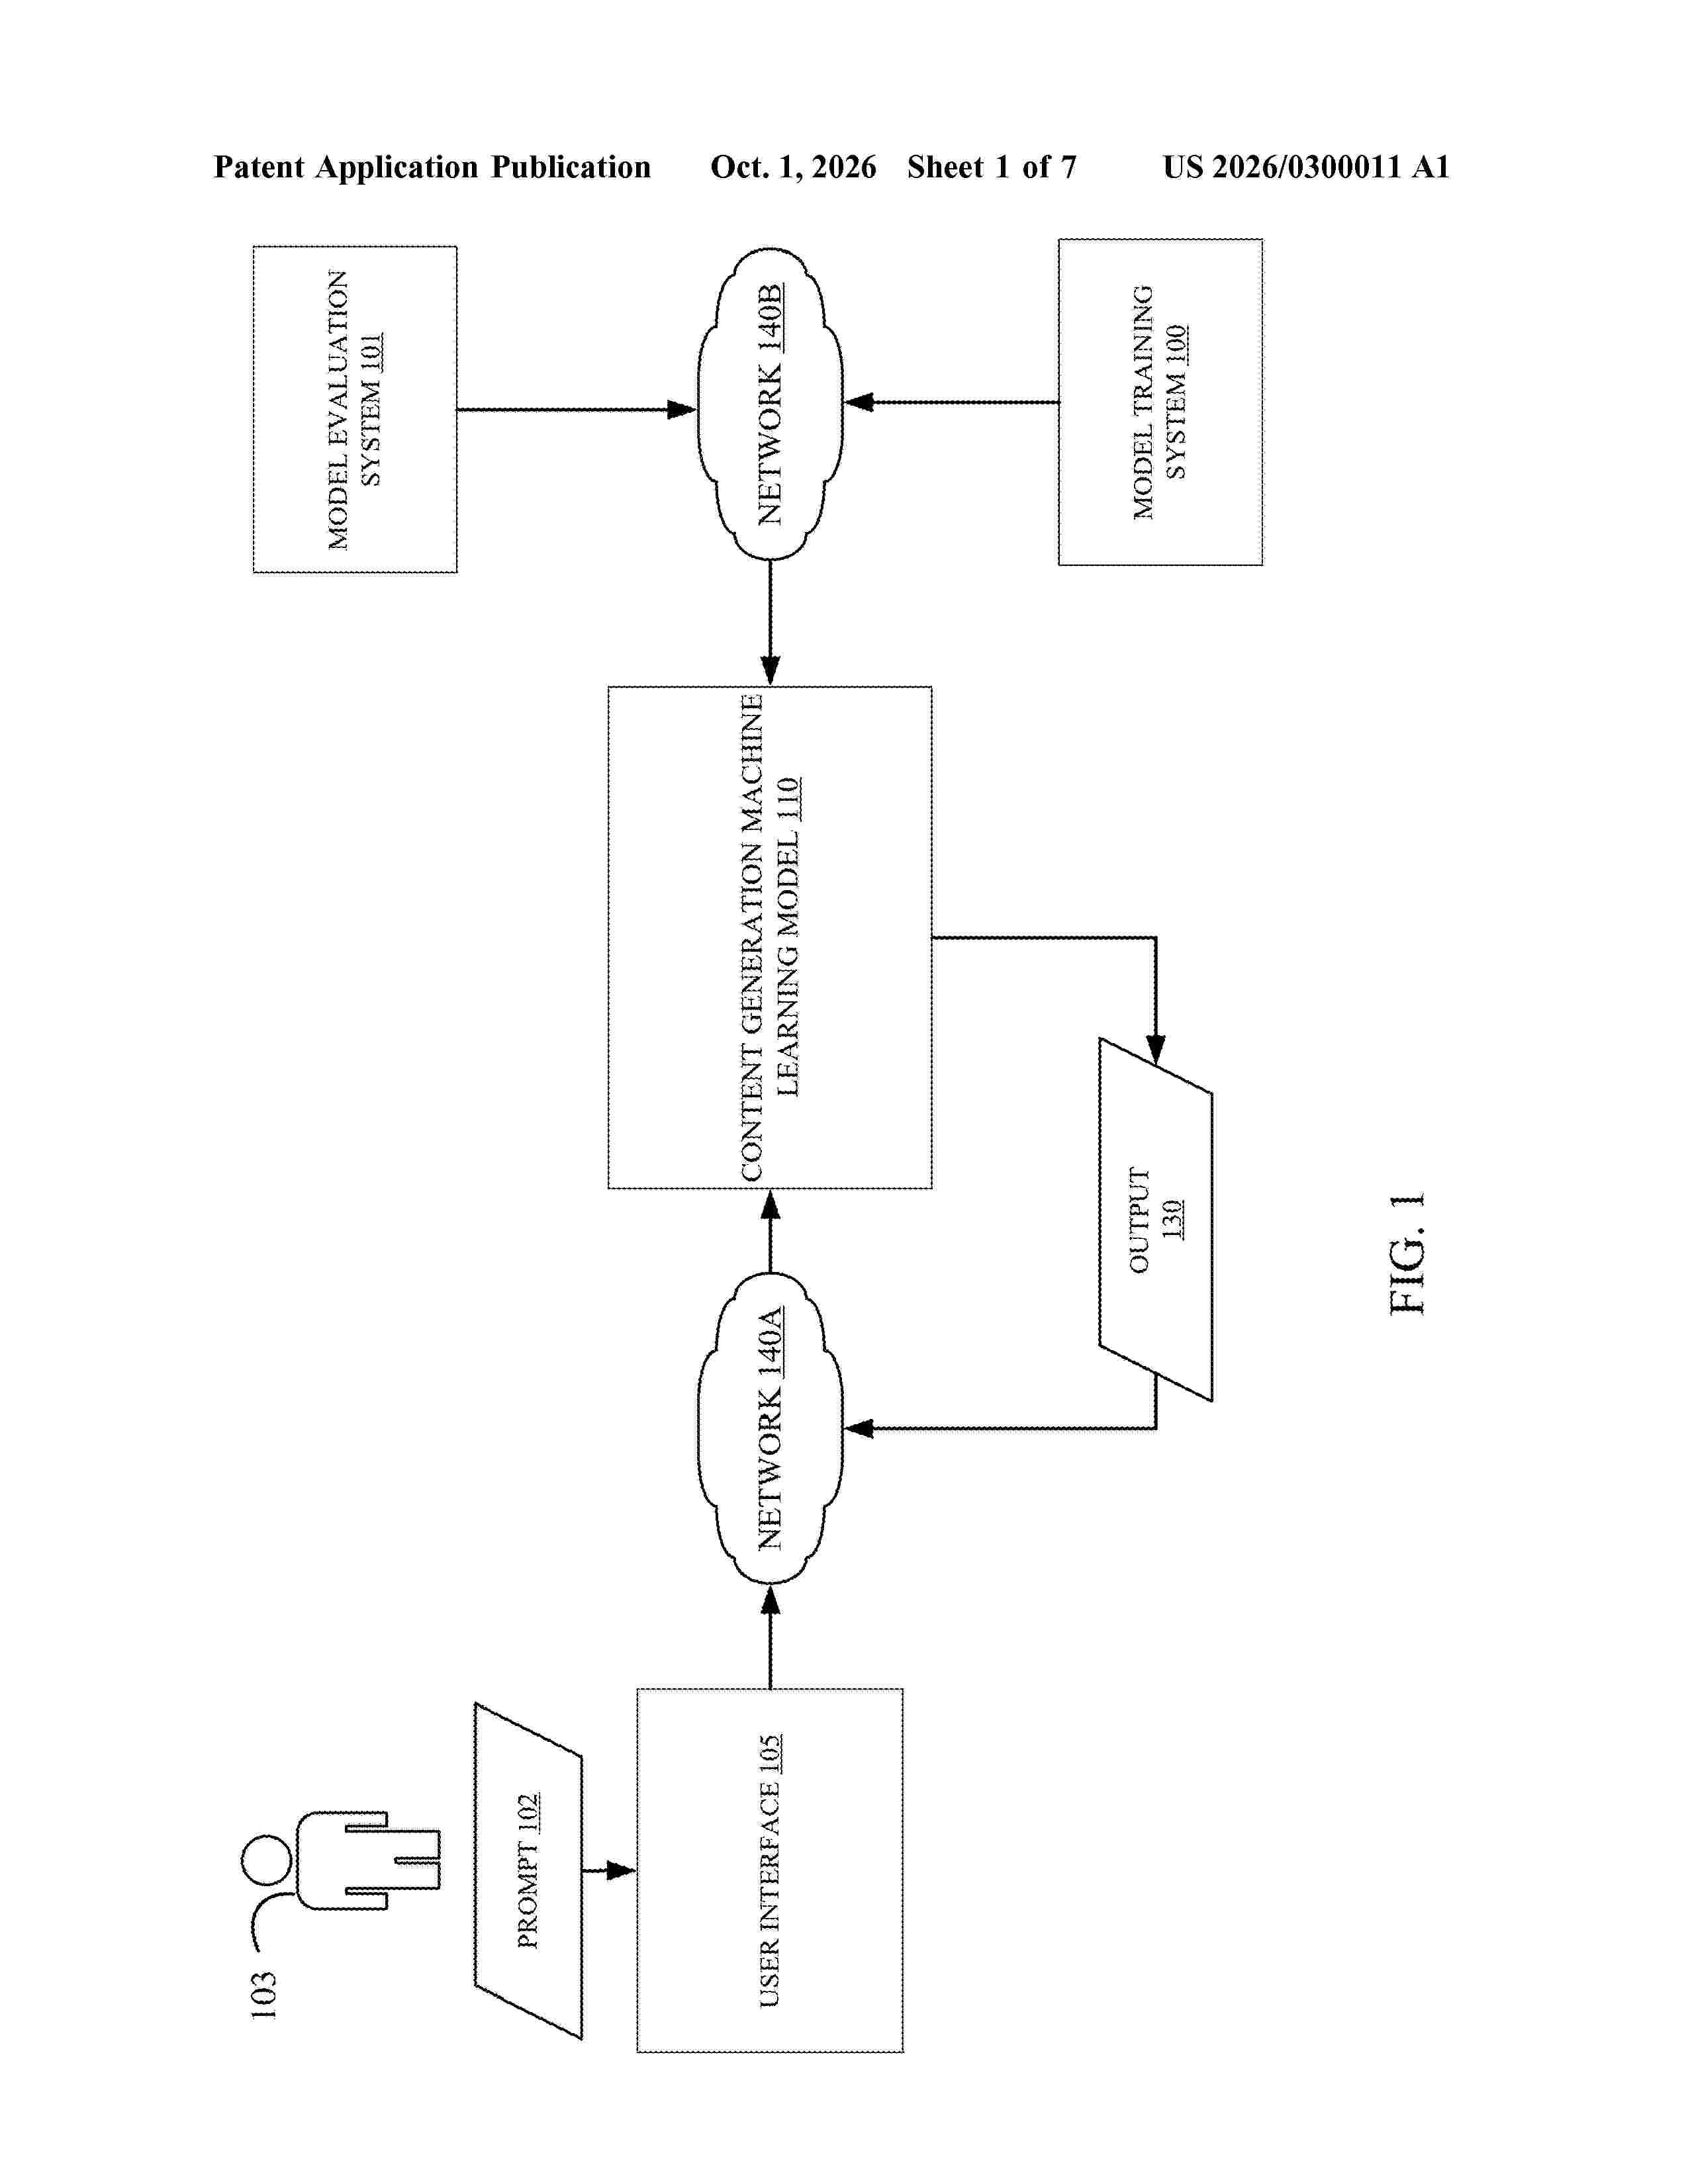
Resumen de: US20260300011A1
0000 Aspects of the present disclosure relate to machine learning based automated content generation systems. Certain embodiments relate to a specific training data generation and supervised learning process for training a content generation model. In some embodiments, training data for a content generation machine learning model may be generated by routing training prompts to generative models that are optimized for a particular prompt type. The optimized models, which may each be optimized for a different type of prompt, may be used to generate ground truth outputs for each of the training prompts. The ground truth outputs and the training prompts may then be used as training data for training the content generation machine learning model. Thus, the training of each of the optimized models may be transferred to the content generation machine learning model.
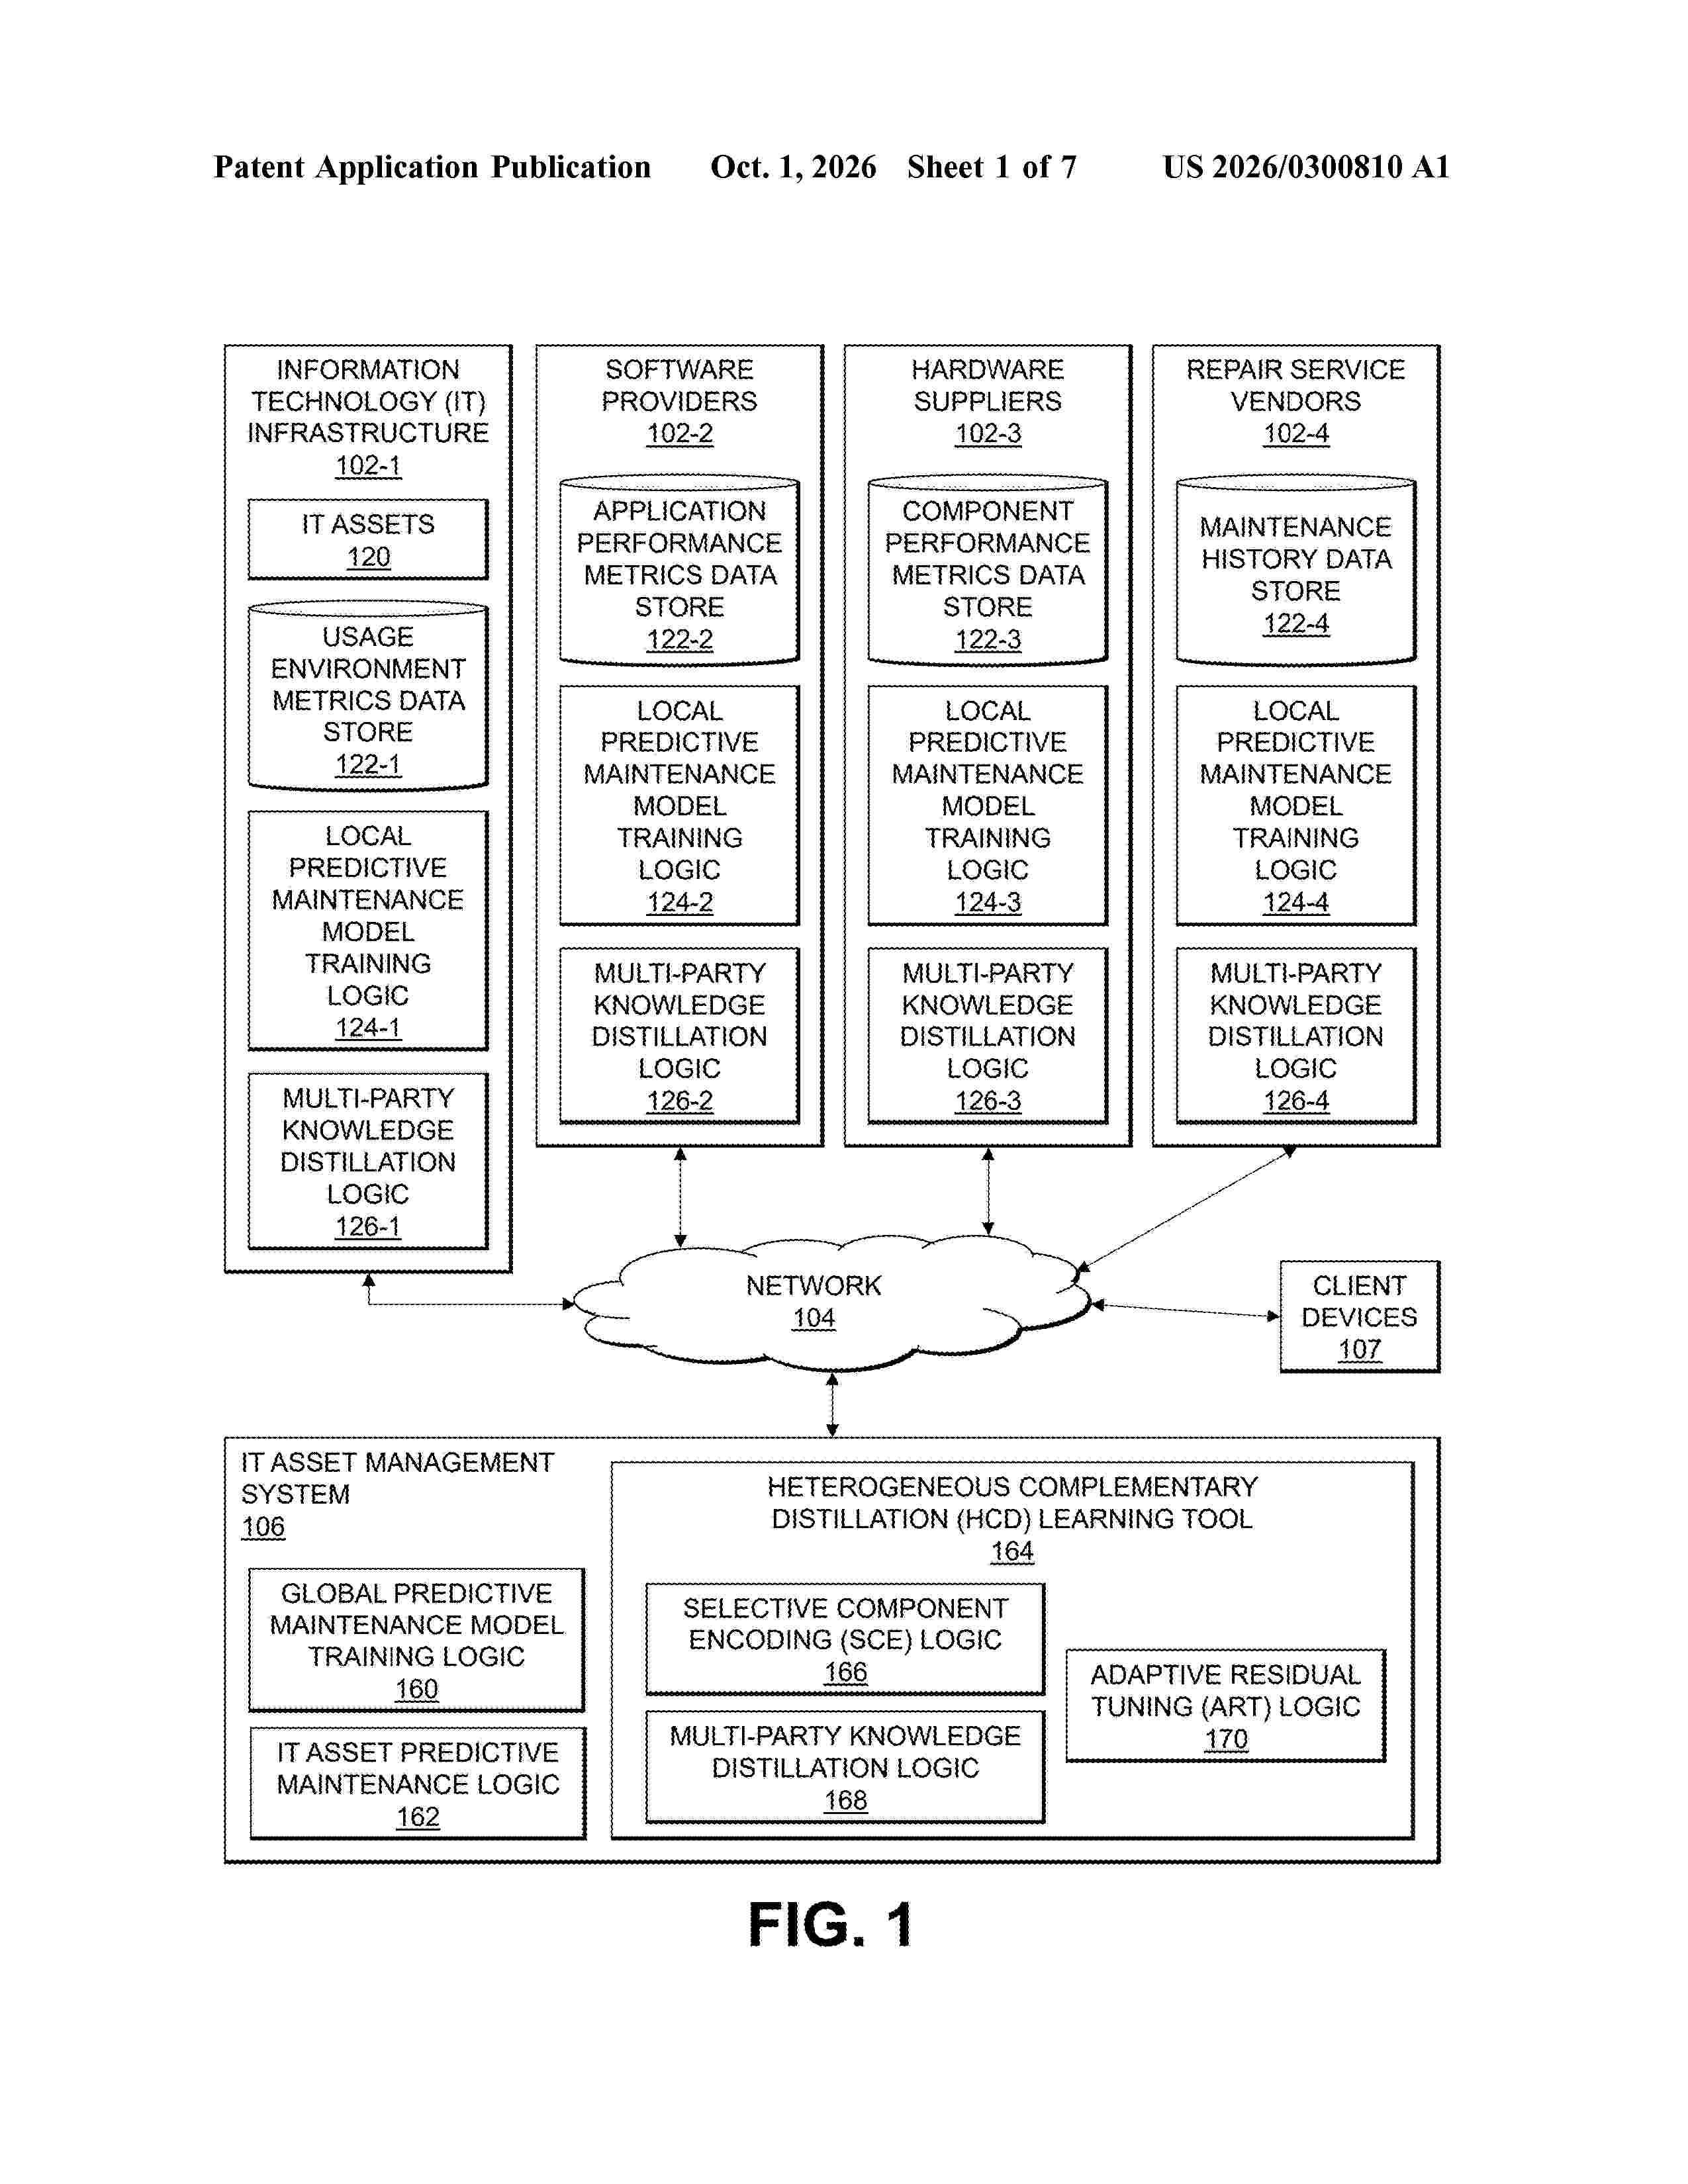
Resumen de: US20260300810A1
0000 An apparatus comprises at least one processing device configured to maintain, by a first entity, a first machine learning model associated with a label distribution of classifications for features characterizing operation of information technology assets running in an information technology infrastructure. The at least one processing device is also configured to generate residual labels characterizing portions of the label distribution not captured by the first machine learning model, to provide the residual labels to additional entities, and to receive from the additional entities partial predictions characterizing predicted classifications for the residual labels based on subsets of the features characterizing the operation of the information technology assets locally available at the additional entities. The at least one processing device is further configured to update one or more parameters of the first machine learning model based at least in part on an aggregation of the partial predictions received from the additional entities.
Resumen de: US20260303557A1
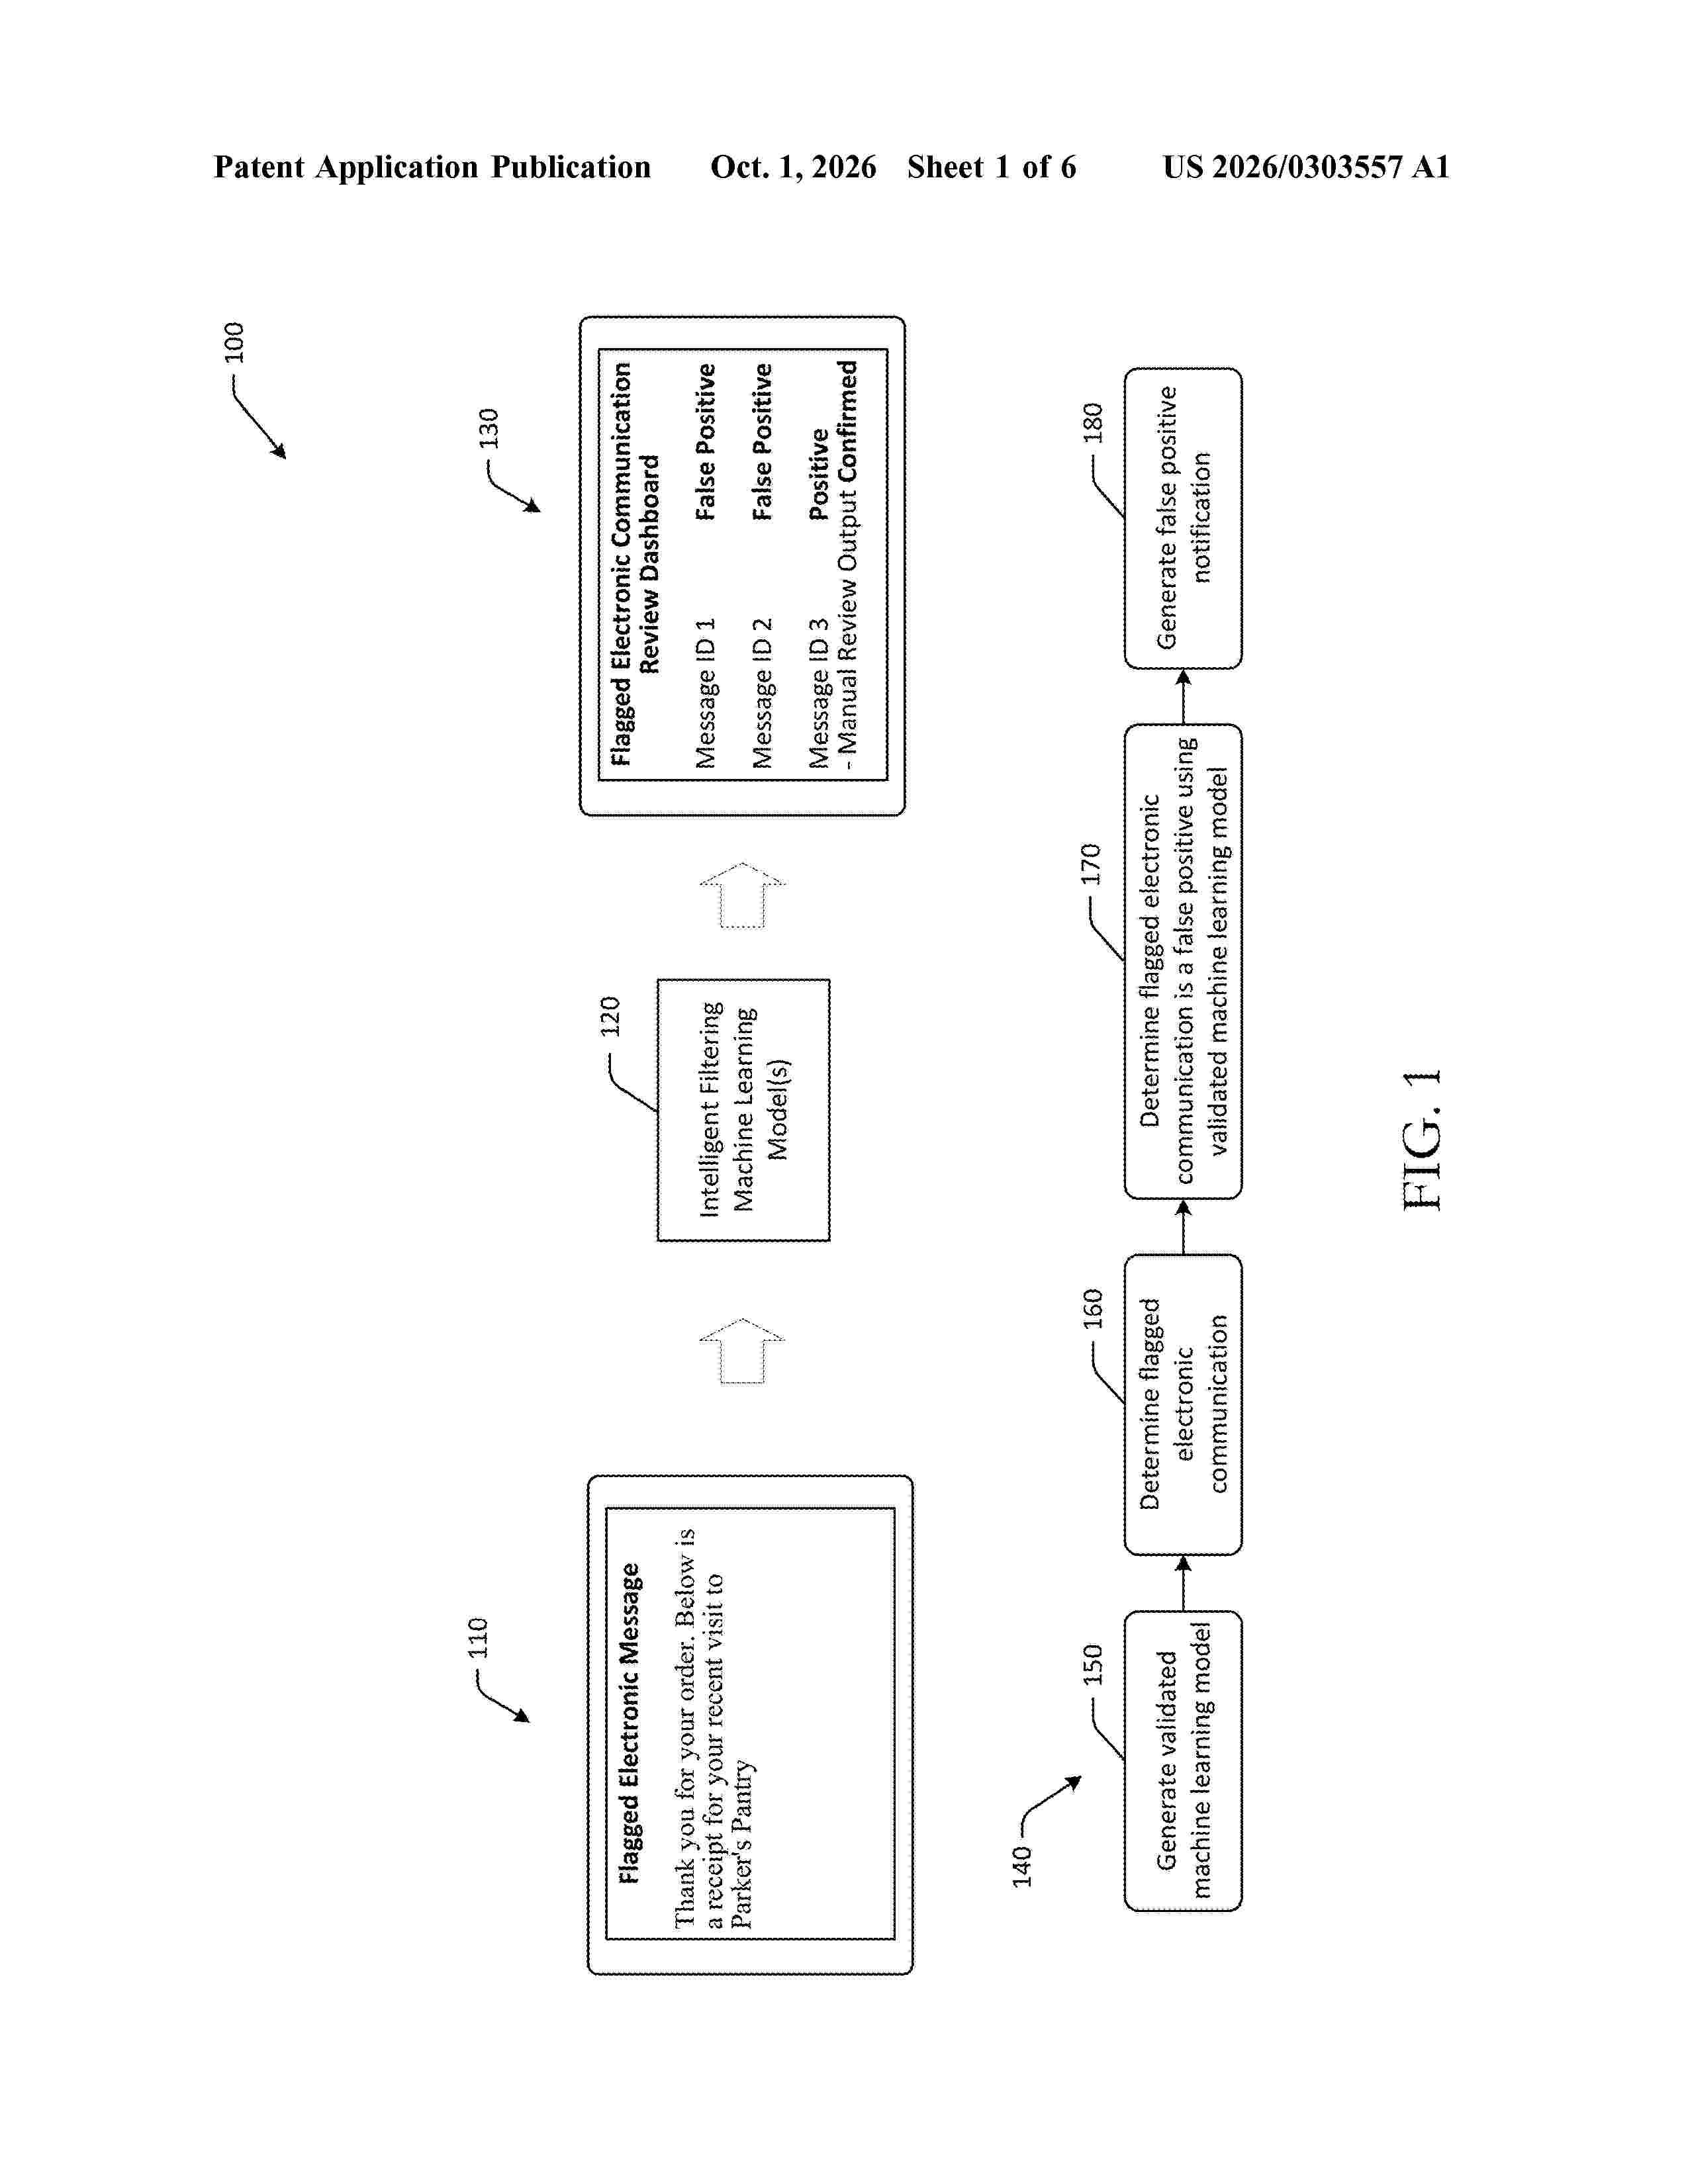
Systems, methods, and computer-readable media are disclosed for systems and methods for intelligent filtering of flagged electronic communications using machine learning. Example methods include determining a first flagged electronic communication using a first machine learning model, where the first flagged electronic communication is flagged due to presence of a phrase, determining, using a second machine learning model, a first false positive score of the first electronic communication, and determining that the first false positive score is less than or equal to a first threshold. The method may include generating a manual review notification for the first flagged electronic communication, determining a manual review output signal associated with the first flagged electronic communication, and causing the second machine learning model to be retrained based at least in part on the manual review output signal.
Resumen de: US20260300827A1
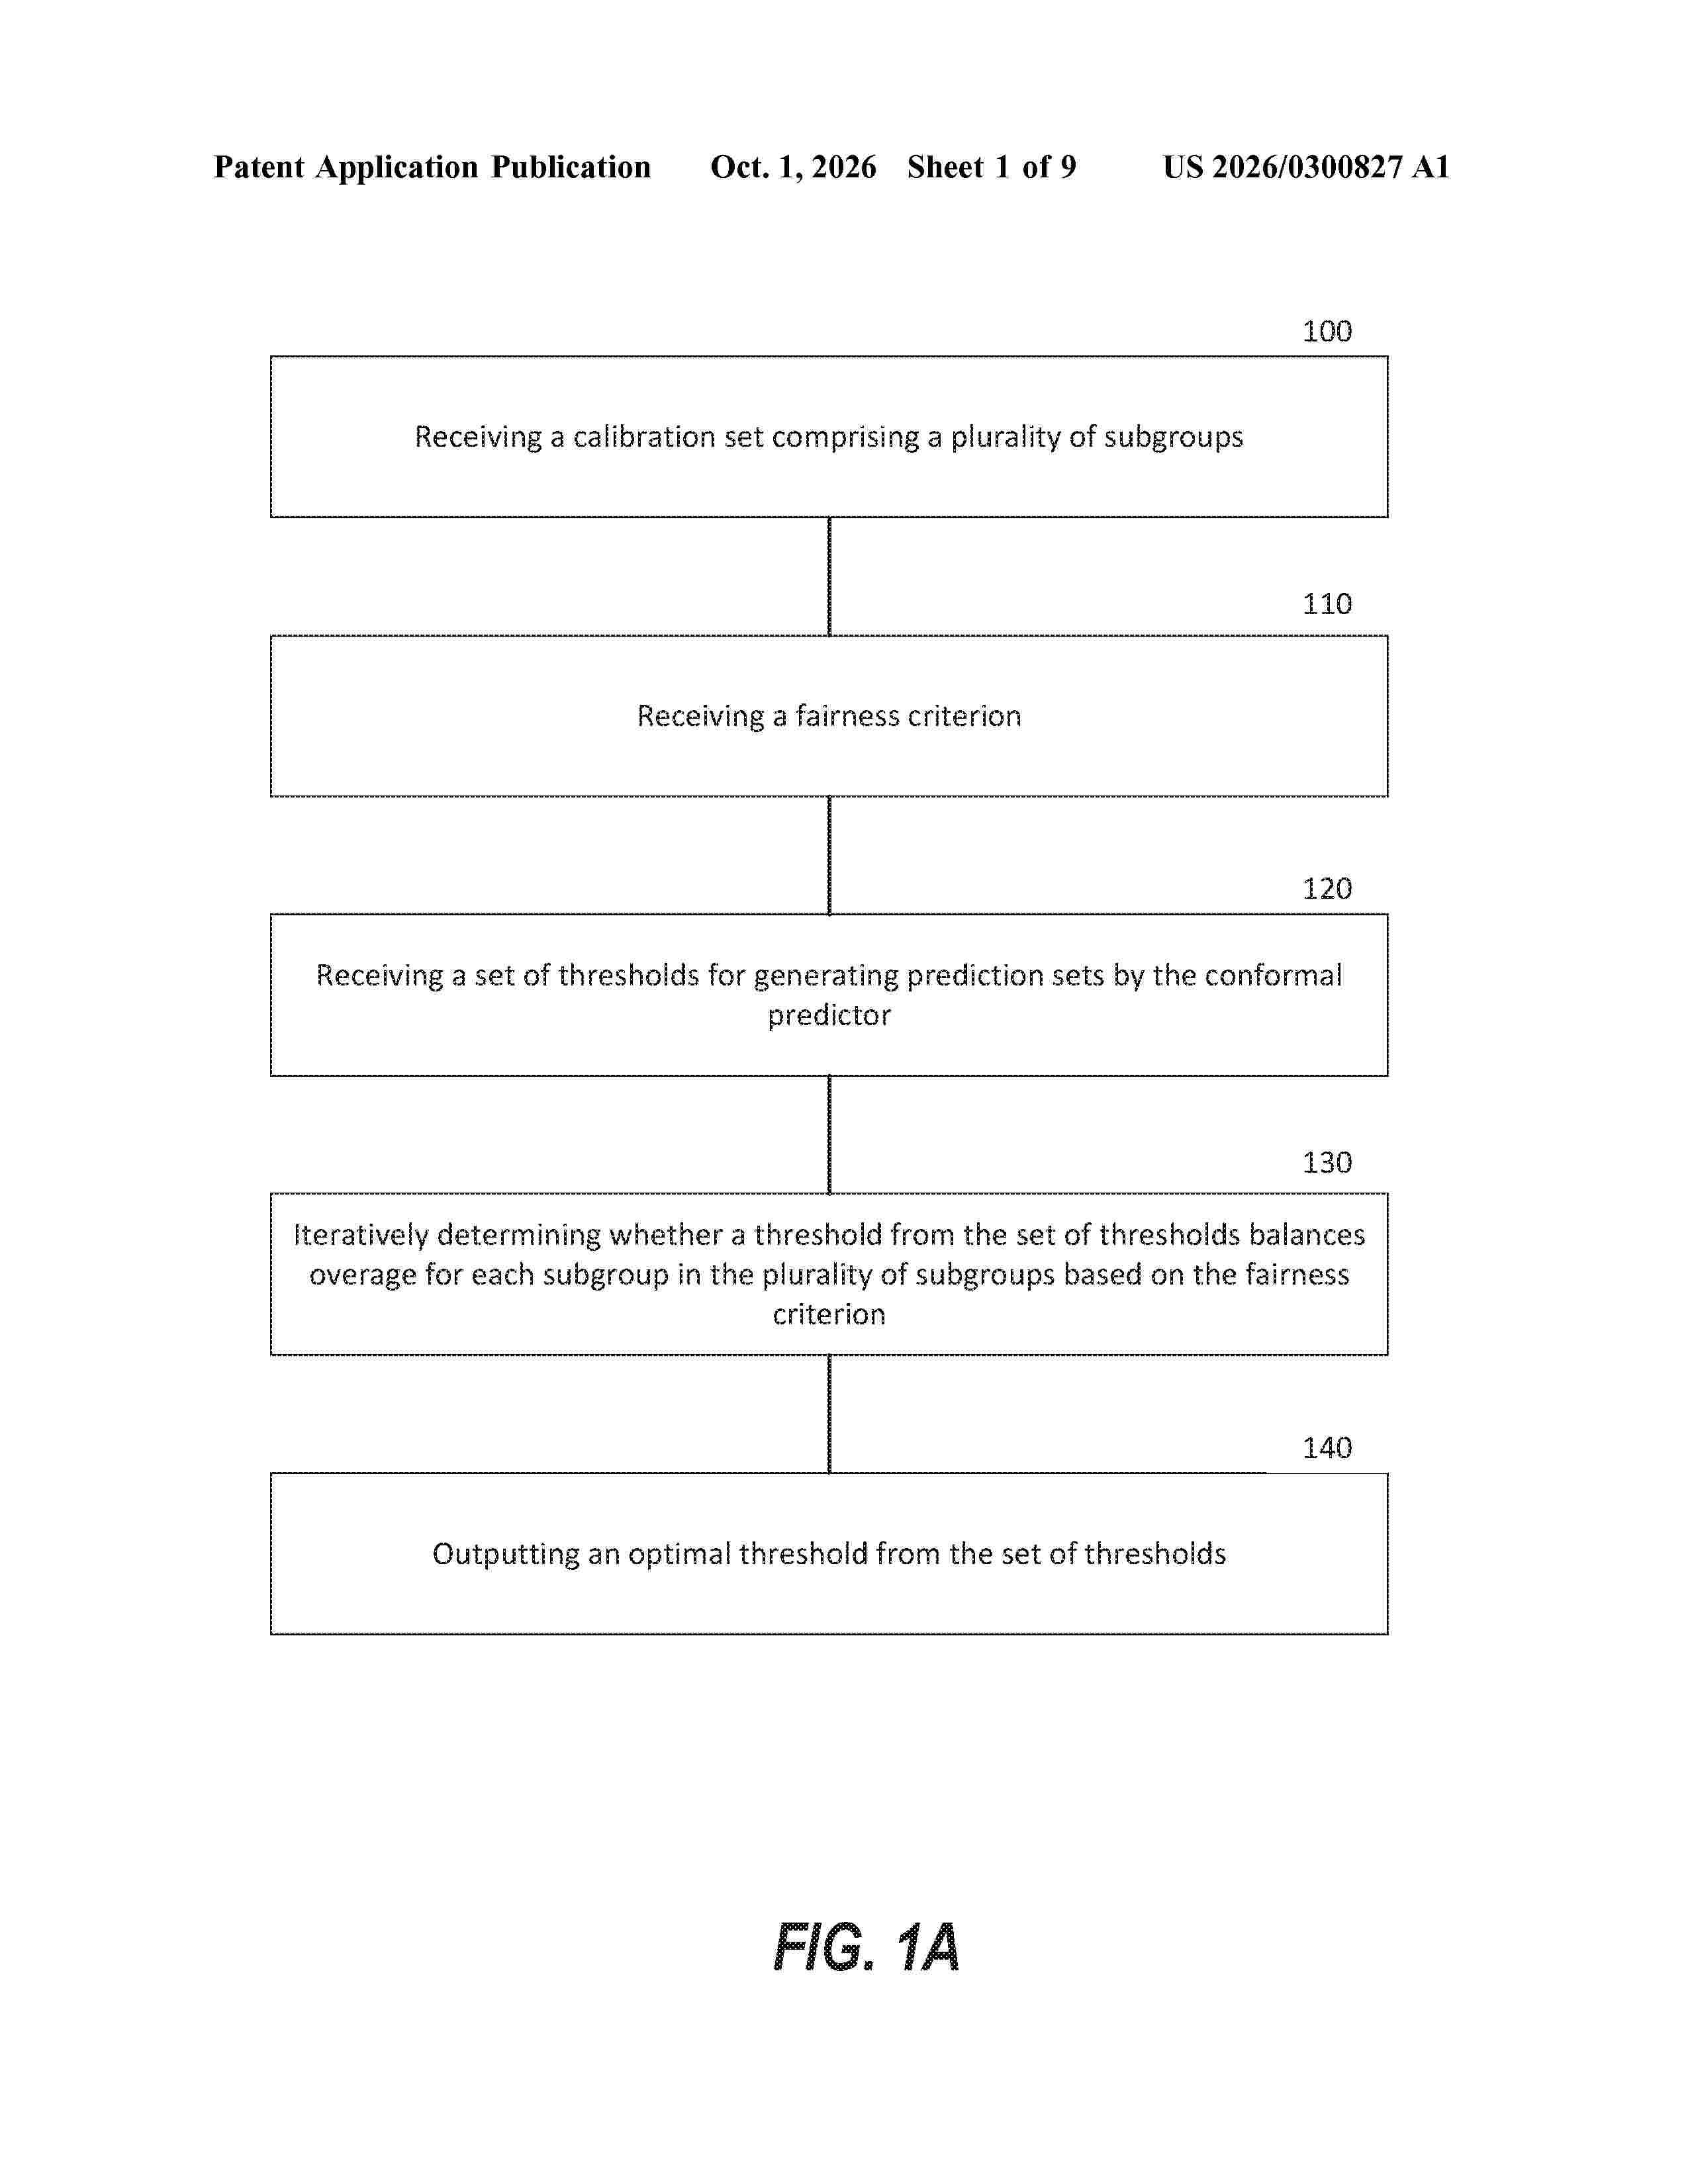
0000 An example computer-implemented method of improving fairness of a conformal predictor associated with a machine learning model includes receiving a calibration set including a plurality of subgroups; receiving a fairness criterion; receiving a set of thresholds for generating prediction sets by the conformal predictor; iteratively determining whether a threshold from the set of thresholds balances coverage for each subgroup in the plurality of subgroups based on the fairness criterion; and outputting an optimal threshold from the set of thresholds;
Resumen de: US20260300762A1
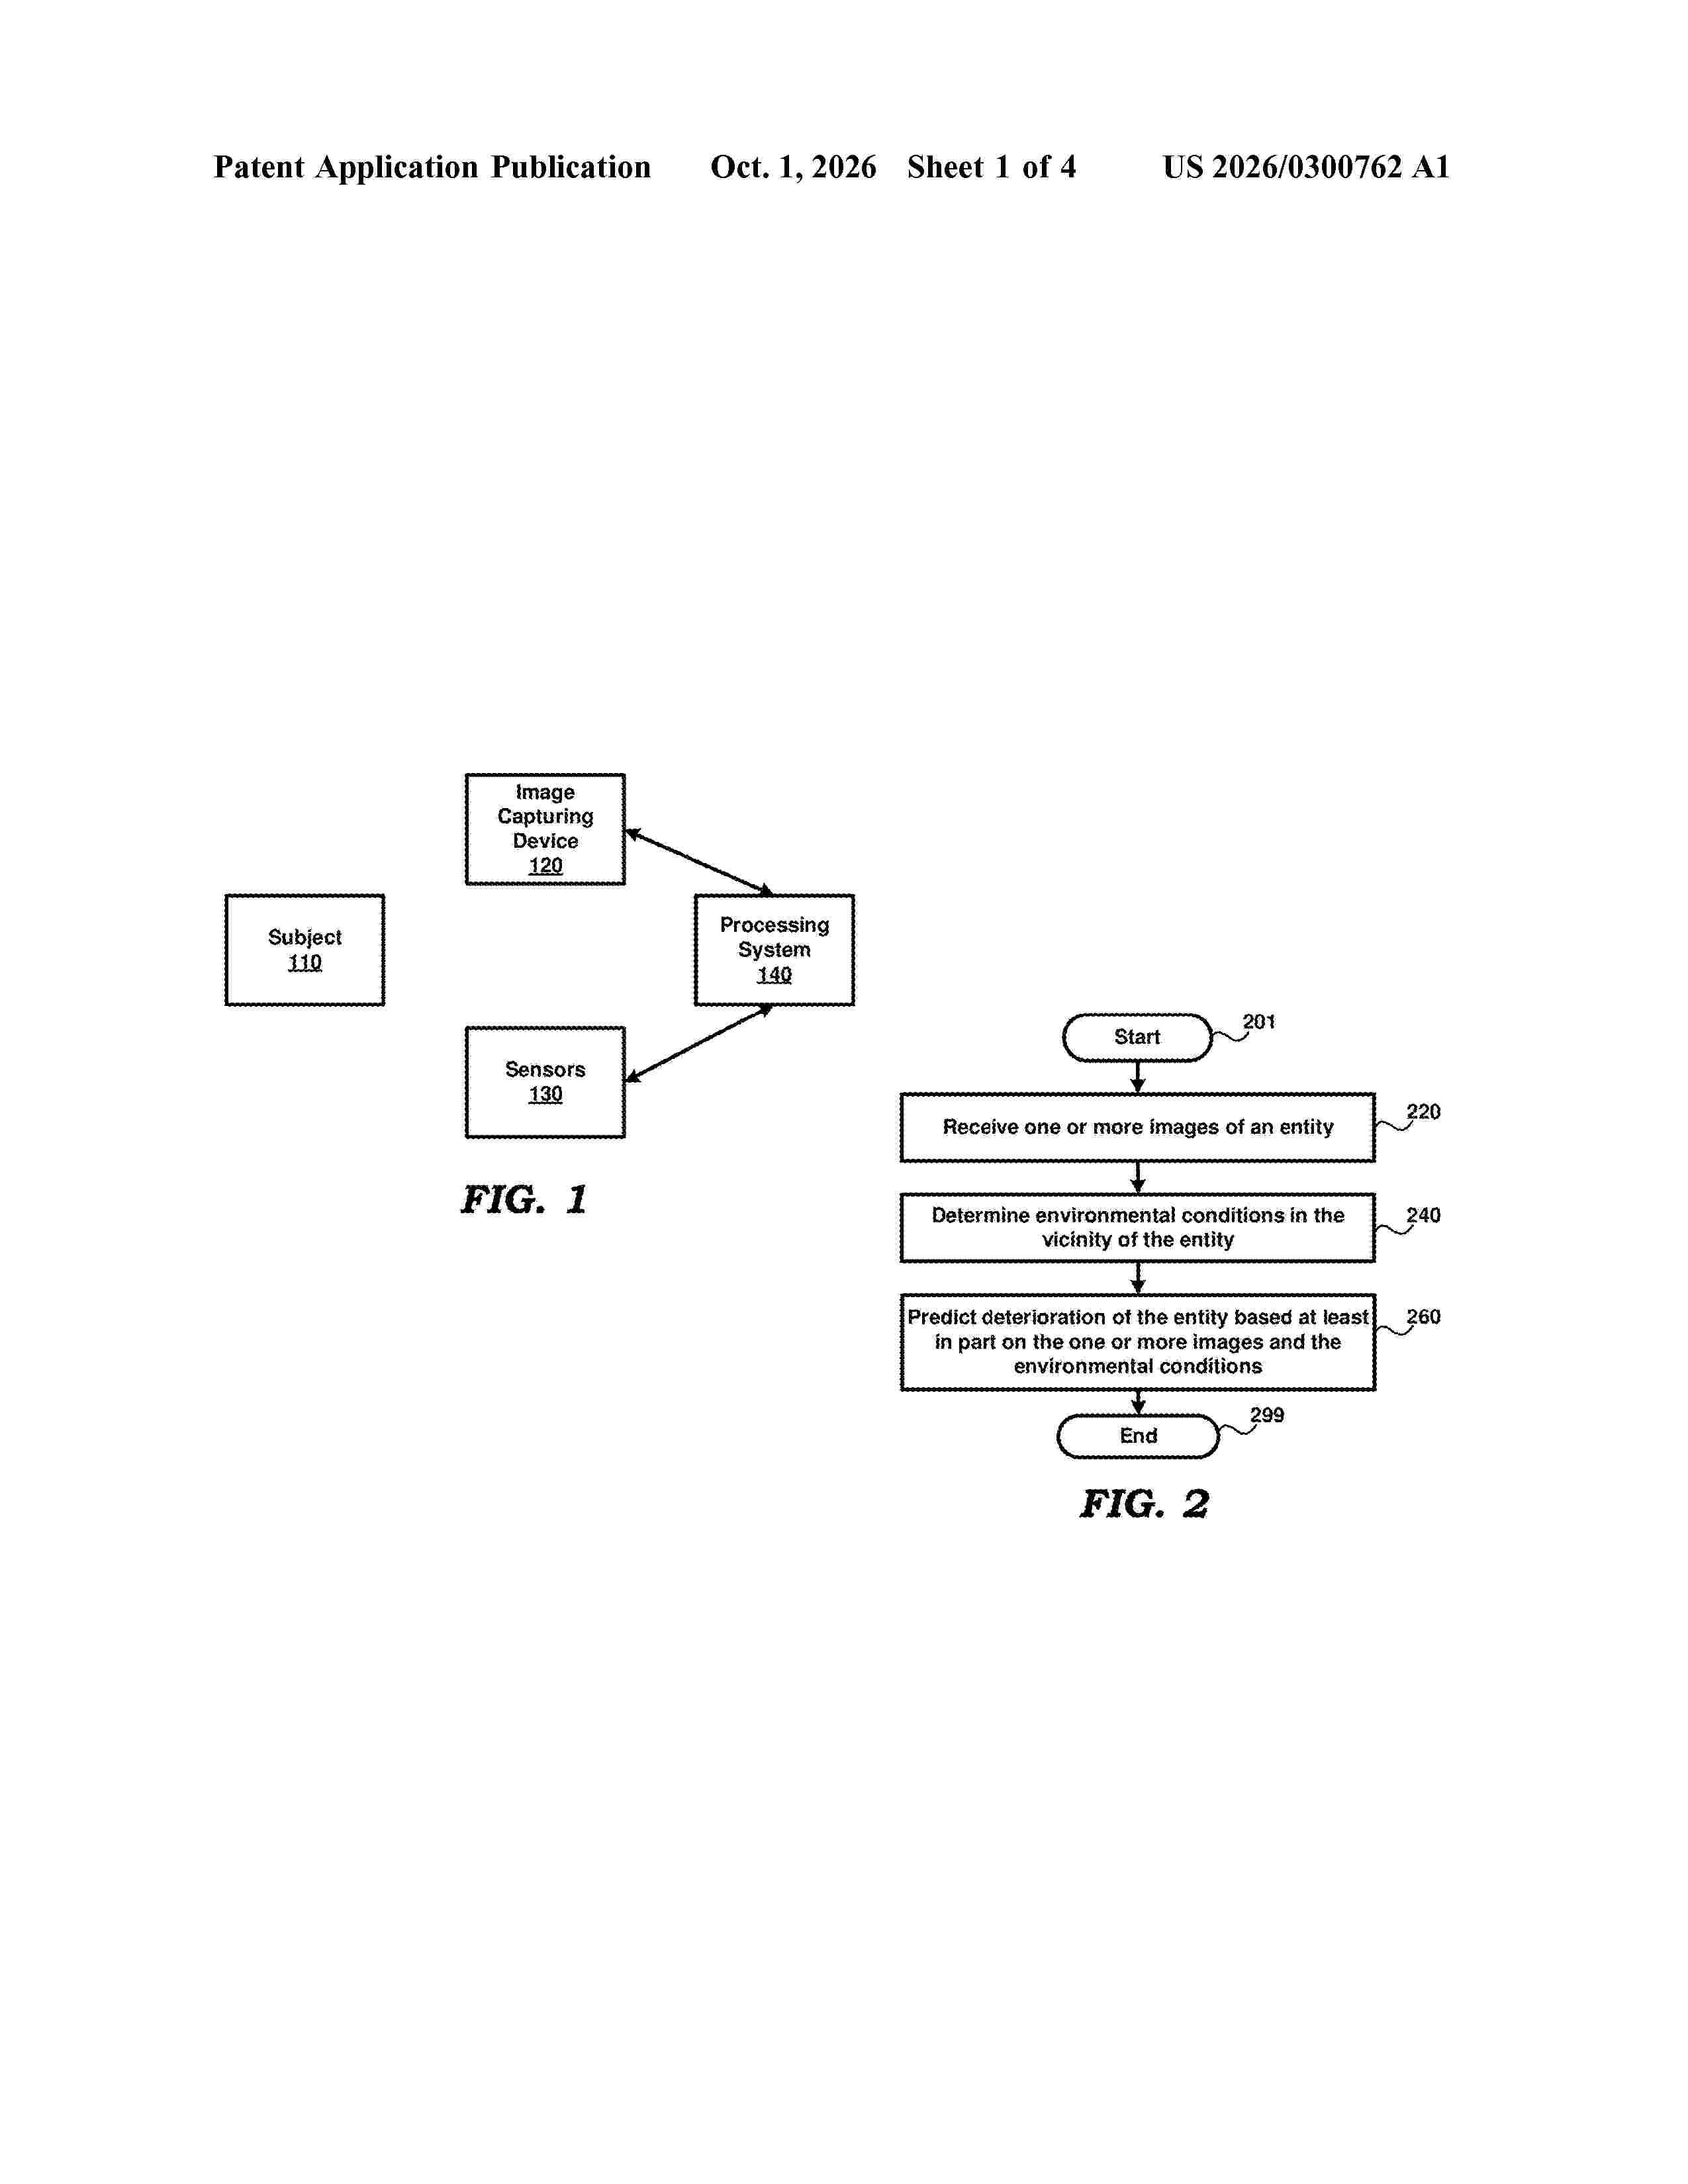
An aspect of the present disclosure provides for prediction of deterioration of entities. In an embodiment, one or more images of an entity are received, environmental conditions in the vicinity of the entity are determined, and deterioration of the entity is predicted, based at least in part, on the one or more images of the entity and the environmental conditions, using one or more machine learning models. The one or more images of the entity indicate a first state of the entity, the deterioration includes change in the state of the entity from the first state to a second state, and the prediction includes estimation of the time required for the state of the entity to change from the first state to the second state. The one or more machine learning models include a multimodal regression model, whose outputs include the estimated time and a level of deterioration.
Resumen de: WO2026207217A1
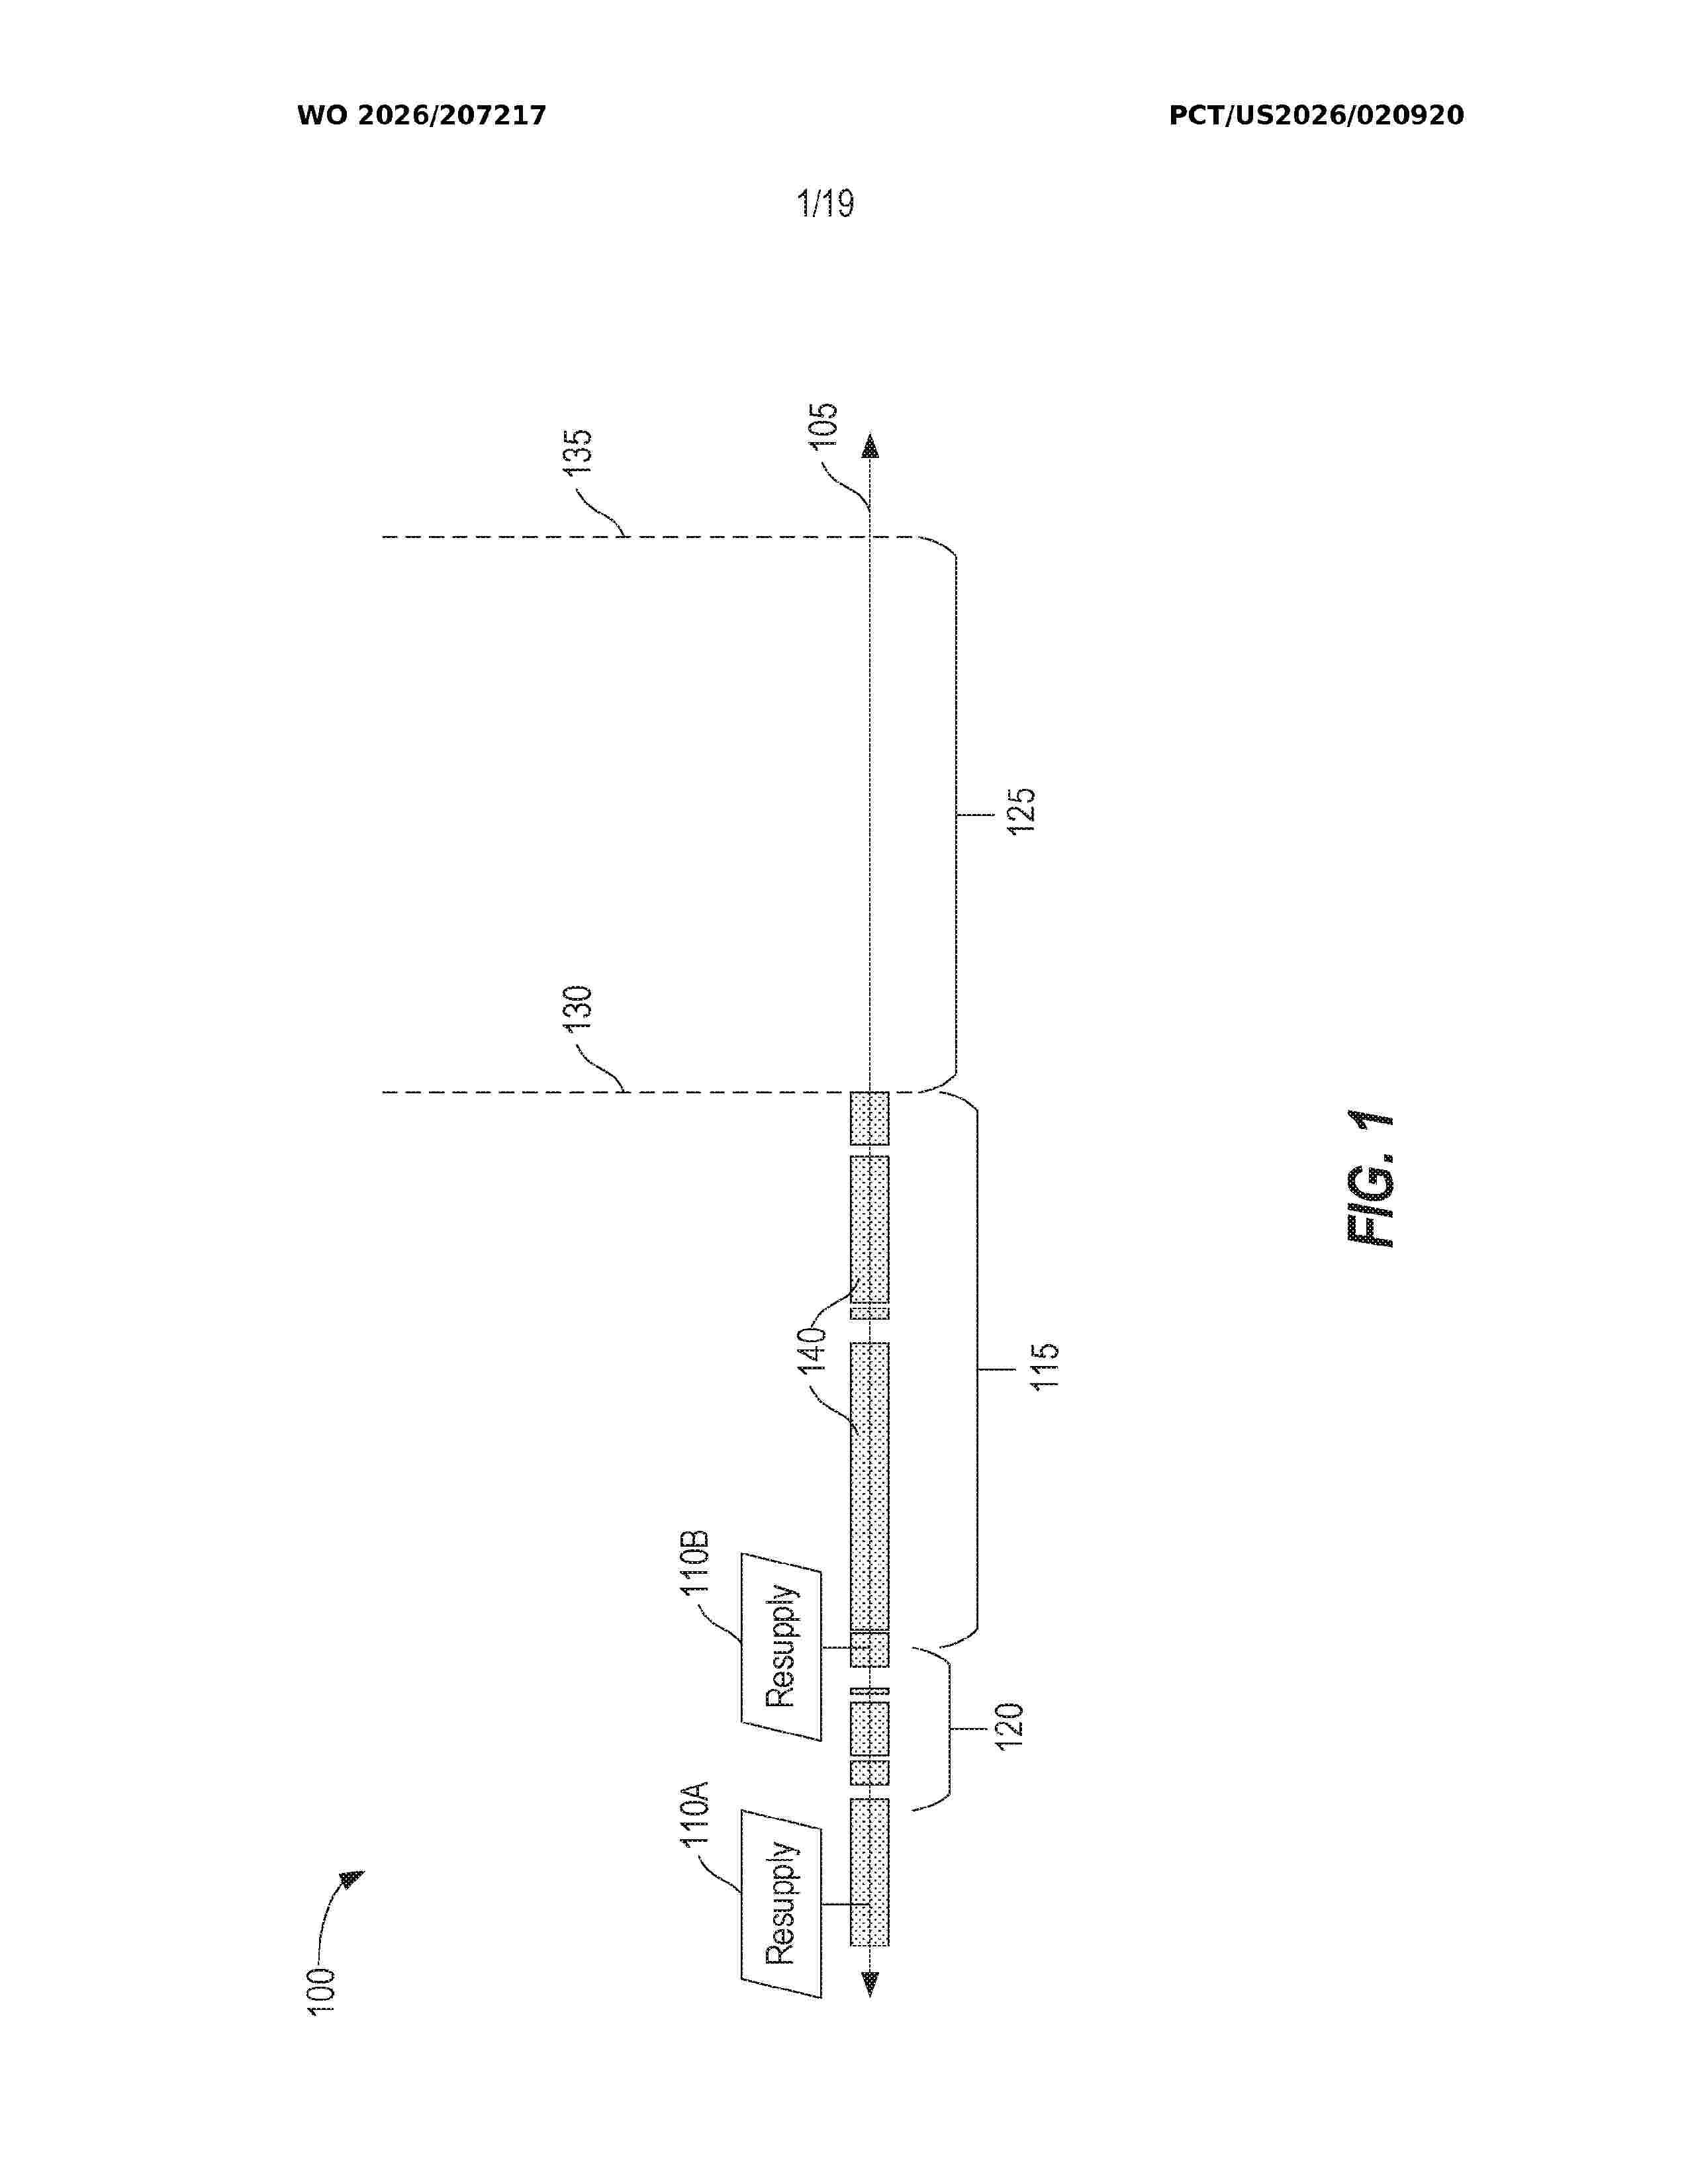
Techniques for improved machine learning are provided. Resupply history for a plurality of users of respiratory therapy is accessed. It is determined that a first user of the plurality of users is approaching resupply attrition based on the resupply history. In response to determining that the first user is approaching resupply attrition, therapy data, for the first user, associated with the respiratory therapy is collected, and an attrition prediction for the first user is generated based on processing the therapy data using a machine learning model. An intervention is facilitated for the first user based on the attrition prediction.
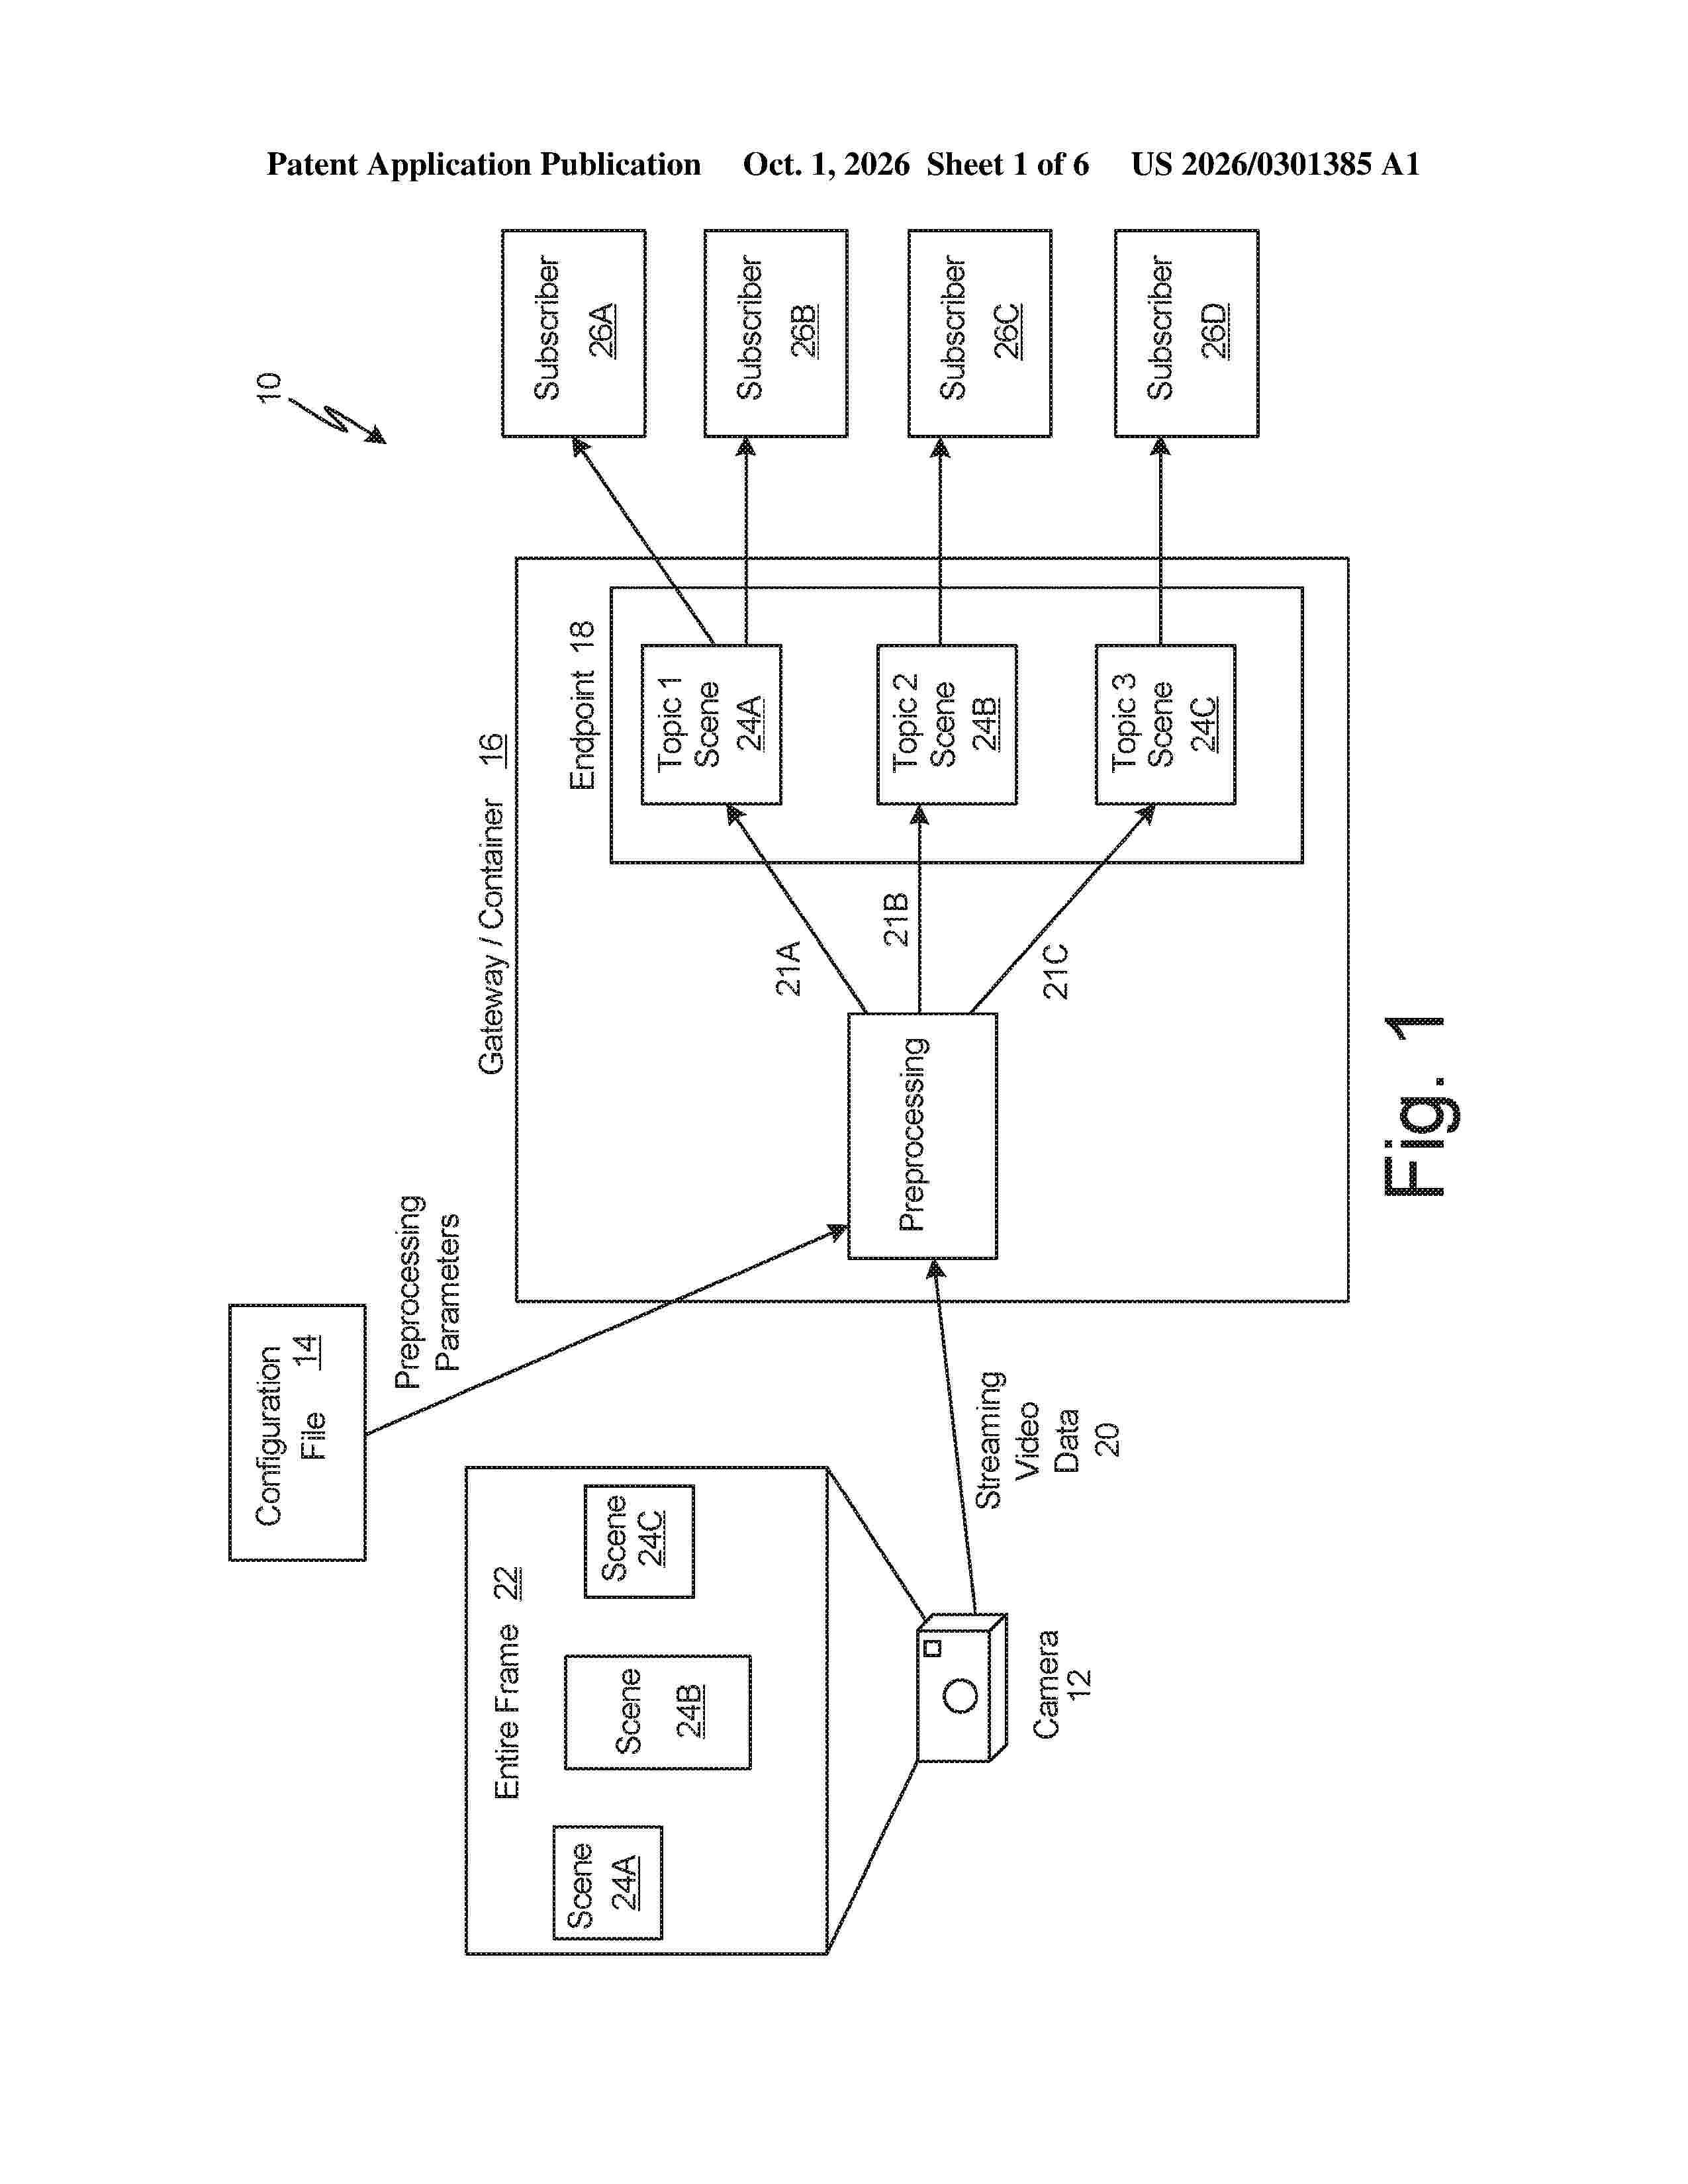
Resumen de: US20260301385A1
0000 A method of improving a main output of a main AI model includes processing first video data using a machine learning model includes continuously analyzing incoming video data via a first processing pipeline and concurrently via a second processing pipeline. The first processing pipeline can include preprocessing incoming video data according to first preprocessing parameters that format the incoming video data to create the first video data and processing the first video data by the main AI model to determine the main output that is indicative of a first inference dependent upon the first video data. The second processing pipeline can include identifying first test preprocessing parameters that are predictive to produce a first test output that satisfies a baseline criterion and preprocessing the incoming video data according to the first test preprocessing parameters that format the incoming video data to create first test video data.
Nº publicación: US20260300443A1 01/10/2026
Solicitante:
CAPITAL ONE FINANCIAL CORP [US]
Capital One Financial Corporation
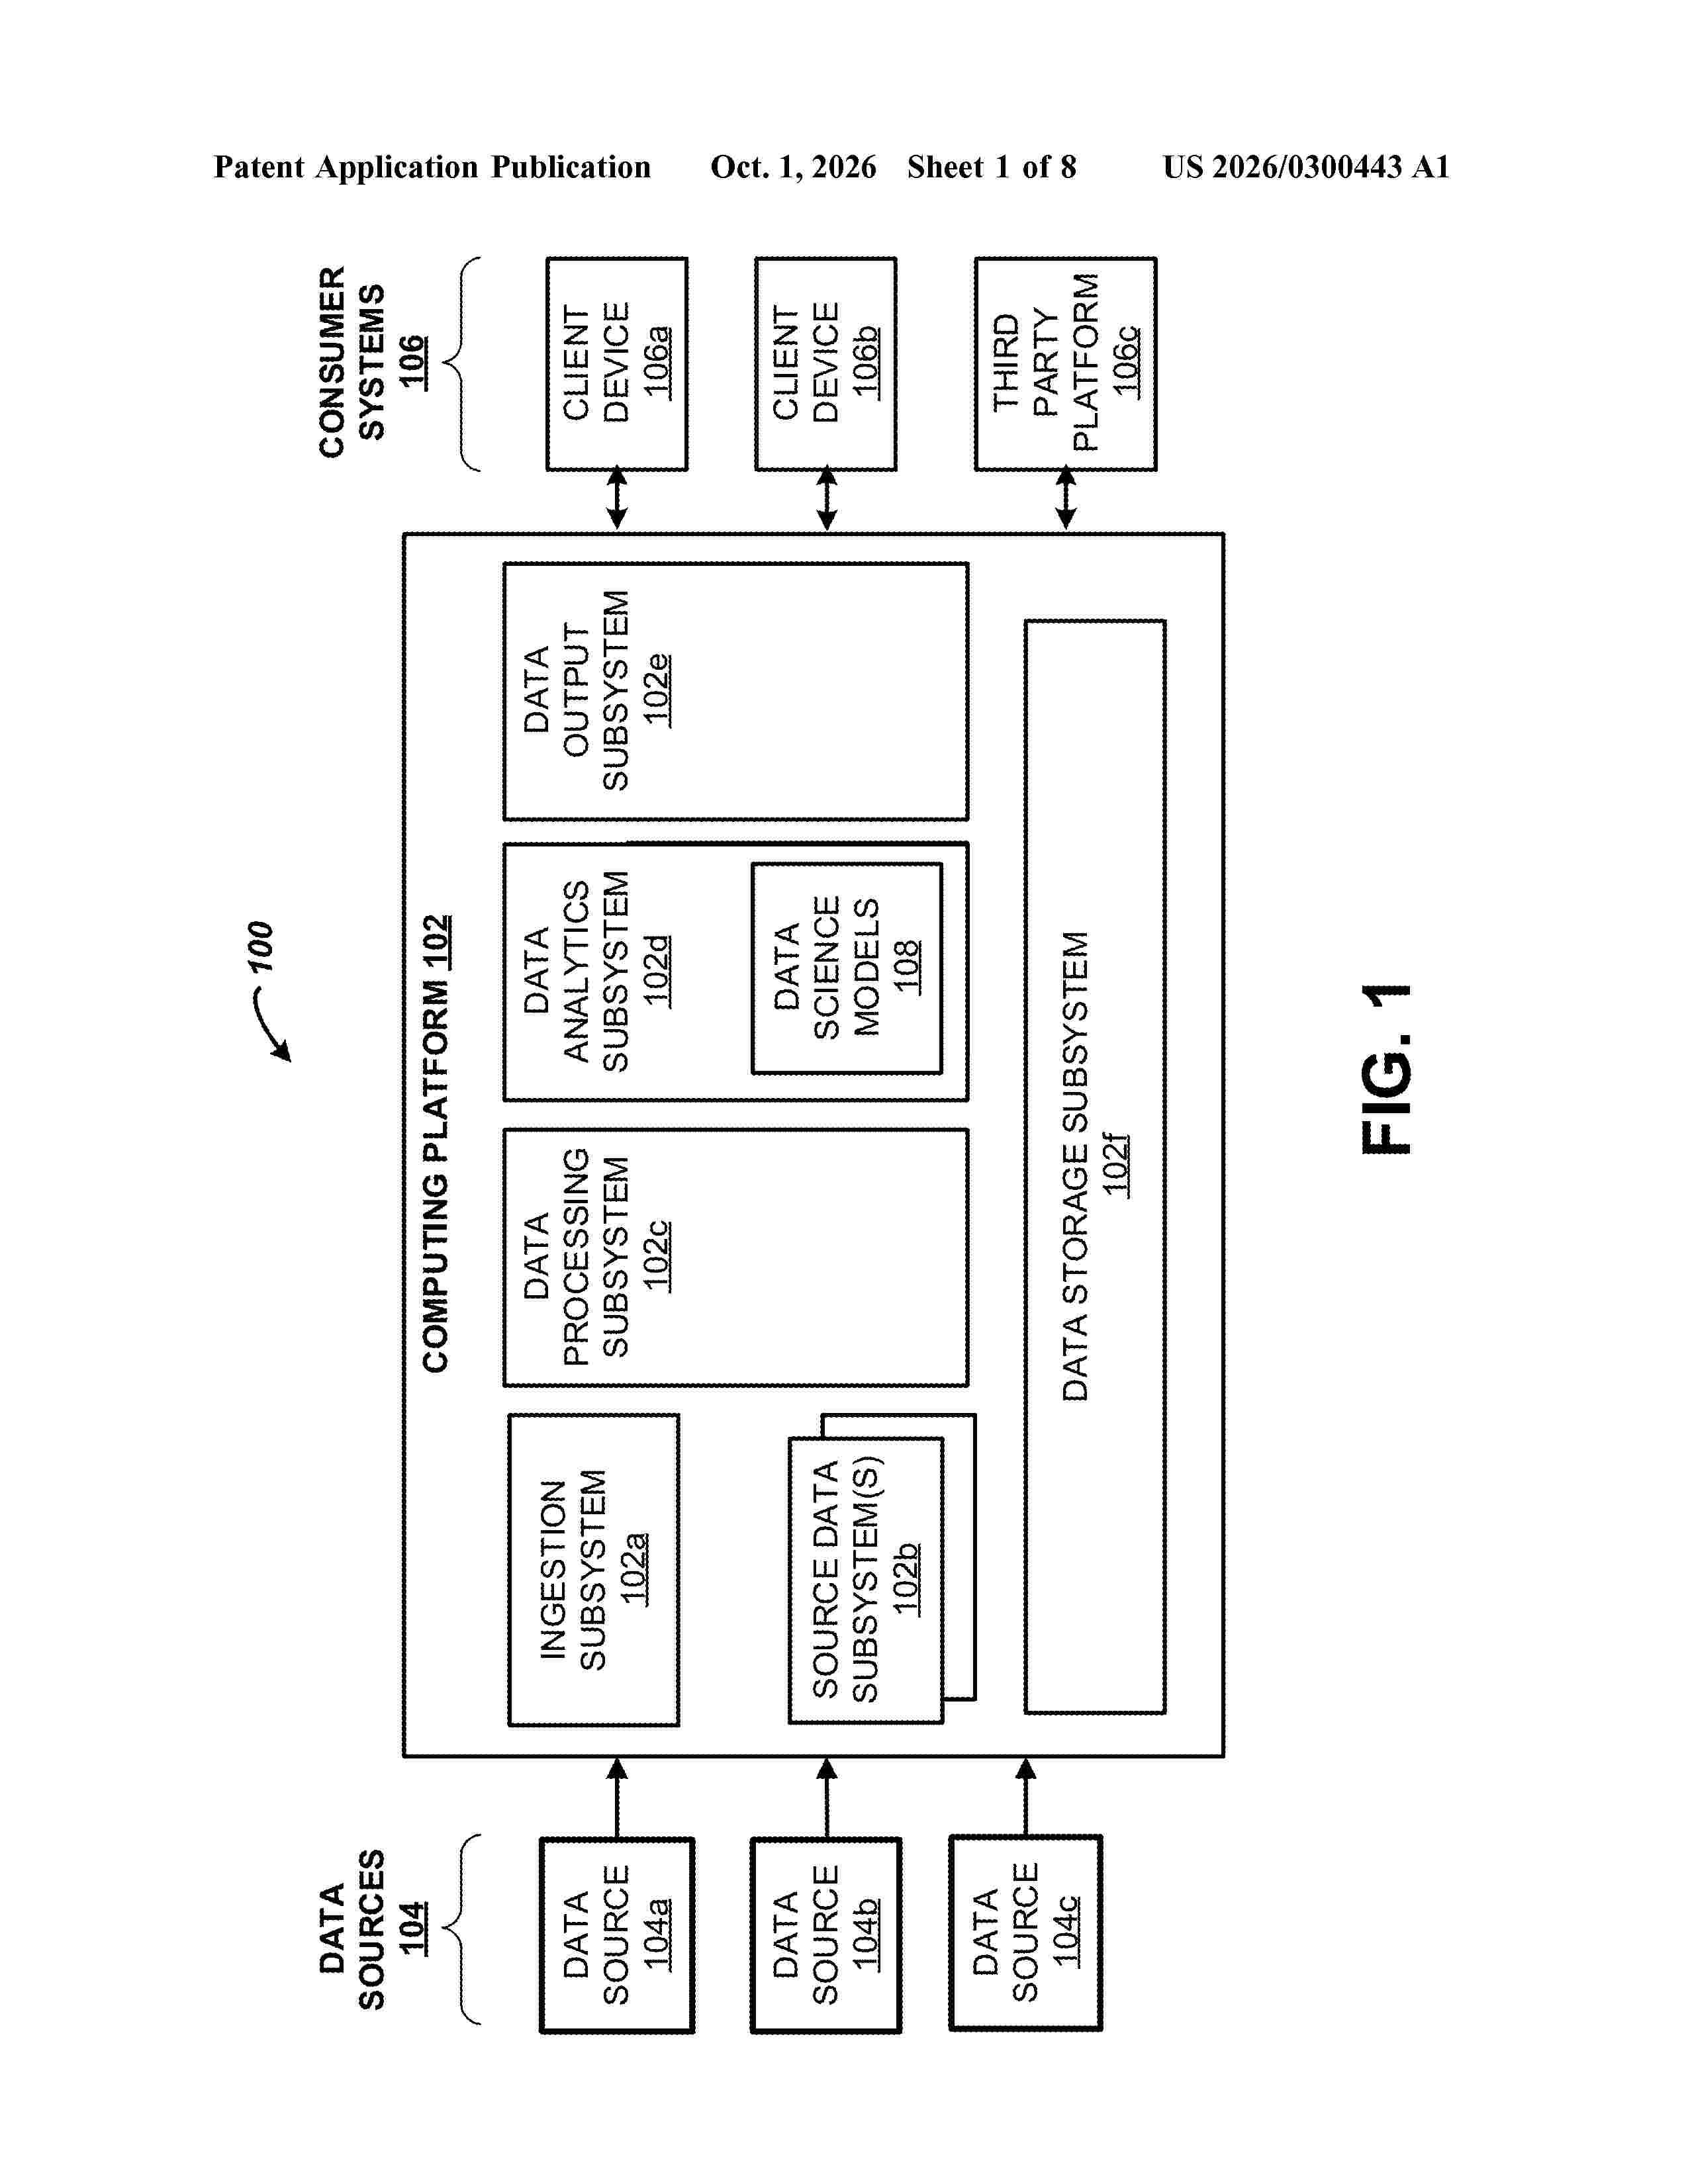
Resumen de: US20260300443A1
A computing platform installed with executable software for producing a fairer version of a machine learning (ML) model that is configured to output a predicted value for a numerical variable, where the computing platform is programmed to (i) initialize a subpopulation-dependent fairer version of the ML model, (ii) train a subpopulation-independent projection of the subpopulation-dependent fairer ML model, (iii) evaluate multiple candidate instances of a subpopulation-independent fairer version of the ML model comprising a linear combination of (a) an unadjusted predicted value for the numerical variable that is output by the ML model and (b) a fairness-adjusted predicted value for the numerical variable that is output by the subpopulation-independent projection, and (iv) based on evaluating the multiple candidate instances of the subpopulation-independent fairer ML model, select a given candidate instance of the subpopulation-independent fairer ML model that is thereafter deployed.
 BOPI
 Sede Electrónica